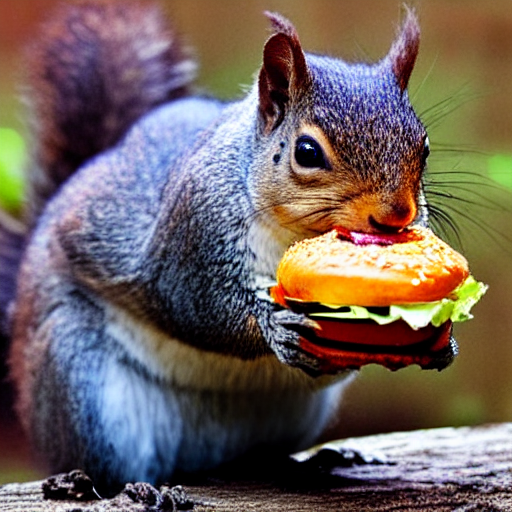
diff --git a/.github/workflows/build_documentation.yml b/.github/workflows/build_documentation.yml index 3bcf7cc77345..0b2c2b85f5a4 100644 --- a/.github/workflows/build_documentation.yml +++ b/.github/workflows/build_documentation.yml @@ -17,7 +17,7 @@ permissions: jobs: build: - uses: huggingface/doc-builder/.github/workflows/build_main_documentation.yml@e60a538eea9817ab312196d0d233604b01697265 # main + uses: huggingface/doc-builder/.github/workflows/build_main_documentation.yml@9fc8a41d7729c424fdb2192f2f85ff63102ec9a3 # main with: commit_sha: ${{ github.sha }} install_libgl1: true diff --git a/.github/workflows/build_pr_documentation.yml b/.github/workflows/build_pr_documentation.yml index a329a3b97fb0..0a3d298f68e6 100644 --- a/.github/workflows/build_pr_documentation.yml +++ b/.github/workflows/build_pr_documentation.yml @@ -44,7 +44,7 @@ jobs: build: needs: check-links - uses: huggingface/doc-builder/.github/workflows/build_pr_documentation.yml@e60a538eea9817ab312196d0d233604b01697265 # main + uses: huggingface/doc-builder/.github/workflows/build_pr_documentation.yml@9fc8a41d7729c424fdb2192f2f85ff63102ec9a3 # main with: commit_sha: ${{ github.event.pull_request.head.sha }} pr_number: ${{ github.event.number }} diff --git a/.github/workflows/upload_pr_documentation.yml b/.github/workflows/upload_pr_documentation.yml index a97f2a9e10e6..8dcddd44fae5 100644 --- a/.github/workflows/upload_pr_documentation.yml +++ b/.github/workflows/upload_pr_documentation.yml @@ -11,7 +11,7 @@ permissions: jobs: build: - uses: huggingface/doc-builder/.github/workflows/upload_pr_documentation.yml@9ad2de8582b56c017cb530c1165116d40433f1c6 # main + uses: huggingface/doc-builder/.github/workflows/upload_pr_documentation.yml@9fc8a41d7729c424fdb2192f2f85ff63102ec9a3 # main with: package_name: diffusers secrets: diff --git a/docs/source/en/_toctree.yml b/docs/source/en/_toctree.yml index 9295218fd687..4b4e4247195d 100644 --- a/docs/source/en/_toctree.yml +++ b/docs/source/en/_toctree.yml @@ -24,6 +24,8 @@ title: Schedulers - local: using-diffusers/weighted_prompts title: Prompting + - local: using-diffusers/image_quality + title: FreeU - local: using-diffusers/reusing_seeds title: Reproducibility - local: using-diffusers/callback @@ -68,24 +70,14 @@ title: Inference - isExpanded: false sections: - - local: optimization/pruna - title: Pruna - - local: optimization/xformers - title: xFormers - - local: optimization/tome - title: Token merging - - local: optimization/deepcache - title: DeepCache - local: optimization/cache_dit title: CacheDiT - - local: optimization/tgate - title: TGATE - - local: optimization/xdit - title: xDiT - local: optimization/para_attn title: ParaAttention - - local: using-diffusers/image_quality - title: FreeU + - local: optimization/pruna + title: Pruna + - local: optimization/xdit + title: xDiT title: Community methods - isExpanded: false sections: @@ -210,6 +202,8 @@ title: Training methods - local: training/nemo_automodel title: NeMo Automodel + - local: training/jobs + title: Hugging Face Jobs title: Train and fine-tune - isExpanded: false sections: @@ -375,6 +369,8 @@ title: JoyImageEditPlusTransformer3DModel - local: api/models/transformer_joyimage title: JoyImageEditTransformer3DModel + - local: api/models/kandinsky6_transformer + title: Kandinsky 6 Transformers - local: api/models/krea2_transformer2d title: Krea2Transformer2DModel - local: api/models/latte_transformer3d @@ -501,6 +497,8 @@ title: AutoencoderSAME - local: api/models/consistency_decoder_vae title: ConsistencyDecoderVAE + - local: api/models/kandinsky6_vae + title: Kandinsky 6 VAEs - local: api/models/ltx2_diffusion_decoder title: LTX2VideoDiffusionDecoderModel - local: api/models/autoencoder_oobleck @@ -725,6 +723,8 @@ title: HunyuanVideo1.5 - local: api/pipelines/kandinsky5_video title: Kandinsky 5.0 Video + - local: api/pipelines/kandinsky6 + title: Kandinsky 6 - local: api/pipelines/latte title: Latte - local: api/pipelines/ltx2 @@ -816,6 +816,8 @@ title: LMSDiscreteScheduler - local: api/schedulers/minimax_h3 title: MiniMaxH3Scheduler + - local: api/schedulers/piflow + title: PiflowScheduler - local: api/schedulers/pndm title: PNDMScheduler - local: api/schedulers/repaint diff --git a/docs/source/en/api/models/kandinsky6_transformer.md b/docs/source/en/api/models/kandinsky6_transformer.md new file mode 100644 index 000000000000..a6139b2fb14f --- /dev/null +++ b/docs/source/en/api/models/kandinsky6_transformer.md @@ -0,0 +1,53 @@ + + +# Kandinsky 6 Transformers + +Kandinsky 6 uses a multimodal diffusion transformer that denoises video and audio latents together for +text/image-to-video-and-audio generation, and a text-free diffusion transformer for video super-resolution. + +## Kandinsky6Transformer3DModel + +The multimodal transformer used by [`Kandinsky6TI2VAPipeline`]. + +```python +import torch +from diffusers import Kandinsky6Transformer3DModel + +transformer = Kandinsky6Transformer3DModel.from_pretrained( + "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16 +) +``` + +[[autodoc]] Kandinsky6Transformer3DModel + - all + - forward + +## Kandinsky6SRTransformer3DModel + +The text-free transformer used by [`Kandinsky6SRPipeline`] to refine one tile of the upscaled video at a time. + +```python +import torch +from diffusers import Kandinsky6SRTransformer3DModel + +transformer = Kandinsky6SRTransformer3DModel.from_pretrained( + "kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16 +) +# The transformer always runs NABLA sparse attention (`nabla_threshold`, 0.8 by default) on the `flex` backend. +# Compile it, otherwise flex falls back to an eager implementation that needs far more memory at video resolutions. +transformer.compile_repeated_blocks(fullgraph=True) +``` + +[[autodoc]] Kandinsky6SRTransformer3DModel + - all + - forward diff --git a/docs/source/en/api/models/kandinsky6_vae.md b/docs/source/en/api/models/kandinsky6_vae.md new file mode 100644 index 000000000000..b4e42a23f65b --- /dev/null +++ b/docs/source/en/api/models/kandinsky6_vae.md @@ -0,0 +1,66 @@ + + +# Kandinsky 6 VAEs + +Kandinsky 6 uses a causal 3D K-VAE for video super-resolution and the MMAudio mel-spectrogram VAE, paired with a +separate BigVGAN [`MMAudioVocoder`], for synchronized audio generation. + +## Kandinsky6SRVAE + +The causal 3D K-VAE used by [`Kandinsky6SRPipeline`]. It processes arbitrarily long videos in bounded-memory +segments while reproducing the exact output of a single, non-segmented pass. + +```python +import torch +from diffusers import Kandinsky6SRVAE + +vae = Kandinsky6SRVAE.from_pretrained( + "kandinskylab/Kandinsky-6.0-VSR-5s-Diffusers", subfolder="vae", torch_dtype=torch.bfloat16 +) +``` + +[[autodoc]] Kandinsky6SRVAE + - encode + - decode + - all + +## MMAudioVAE + +The mel-spectrogram VAE used by [`Kandinsky6TI2VAPipeline`] when `sample_audio=True`. Its `decode` output is a mel +spectrogram; pass it through [`MMAudioVocoder`] to get a waveform. + +The reference implementation can be found at [hkchengrex/MMAudio](https://github.com/hkchengrex/MMAudio) (MIT +license). + +```python +import torch +from diffusers import MMAudioVAE + +audio_vae = MMAudioVAE.from_pretrained( + "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers", subfolder="audio_vae", torch_dtype=torch.bfloat16 +) +``` + +[[autodoc]] MMAudioVAE + - encode + - decode + - all + +## MMAudioVocoder + +Adapted from the BigVGAN-v2 vocoder MMAudio bundles, itself from +[NVIDIA/BigVGAN](https://github.com/NVIDIA/BigVGAN) (MIT license), with the anti-aliased Snake activations of +[alias-free-torch](https://github.com/junjun3518/alias-free-torch) (Apache License 2.0). + +[[autodoc]] MMAudioVocoder + - forward diff --git a/docs/source/en/api/pipelines/kandinsky.md b/docs/source/en/api/pipelines/kandinsky.md index a1965eb3cb72..5347c6f895e1 100644 --- a/docs/source/en/api/pipelines/kandinsky.md +++ b/docs/source/en/api/pipelines/kandinsky.md @@ -712,7 +712,7 @@ make_image_grid([img.resize((512, 512)), image.resize((512, 512))], rows=1, cols Kandinsky is unique because it requires a prior pipeline to generate the mappings, and a second pipeline to decode the latents into an image. Optimization efforts should be focused on the second pipeline because that is where the bulk of the computation is done. Here are some tips to improve Kandinsky during inference. -1. Enable [xFormers](../../optimization/xformers) if you're using PyTorch < 2.0: +1. Enable [xFormers](../../optimization/attention_backends) if you're using PyTorch < 2.0: ```diff from diffusers import DiffusionPipeline diff --git a/docs/source/en/api/pipelines/kandinsky6.md b/docs/source/en/api/pipelines/kandinsky6.md new file mode 100644 index 000000000000..db4cdb1944cc --- /dev/null +++ b/docs/source/en/api/pipelines/kandinsky6.md @@ -0,0 +1,150 @@ + + +# Kandinsky 6 + +Kandinsky 6 is a family of video generation models from [Kandinsky Lab](https://huggingface.co/kandinskylab). The +main model generates video and synchronized audio from text or a reference image with a single multimodal diffusion +transformer: video and audio latents are denoised together through fused blocks that cross-attend between the two +modalities, each conditioned on its own Qwen2.5-VL text branch and a CLIP pooled embedding. A separate +super-resolution model upscales the generated video tile by tile in the latent space of a causal 3D K-VAE. + +> [!TIP] +> Check out the [Kandinsky Lab](https://huggingface.co/kandinskylab) organization on the Hub for the full set of +> official checkpoints, including flow-matching and distilled variants of both the base and super-resolution models. +> +> Distilled checkpoints ship with the few-step [`PiflowScheduler`] and must be run with `guidance_scale=1.0`. + +## Available models + +| Model | Pipeline | Notes | +|---|---|---| +| [`kandinskylab/Kandinsky-6.0-Pro-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-Pro-5s-Diffusers) | [`Kandinsky6TI2VAPipeline`] | Flow matching, `guidance_scale=5.0`, 50 steps | +| [`kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers) | [`Kandinsky6TI2VAPipeline`] | Distilled, `guidance_scale=1.0`, 10 steps | +| [`kandinskylab/Kandinsky-6.0-Lite-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-Lite-5s-Diffusers) | [`Kandinsky6TI2VAPipeline`] | Flow matching, `guidance_scale=5.0`, 50 steps | +| [`kandinskylab/Kandinsky-6.0-Lite-distill-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-Lite-distill-5s-Diffusers) | [`Kandinsky6TI2VAPipeline`] | Distilled, `guidance_scale=1.0`, 10 steps | +| [`kandinskylab/Kandinsky-6.0-Pro-pretrain-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-Pro-pretrain-5s-Diffusers) | [`Kandinsky6TI2VAPipeline`] | Flow matching, `guidance_scale=5.0`, 50 steps | +| [`kandinskylab/Kandinsky-6.0-Lite-pretrain-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-Lite-pretrain-5s-Diffusers) | [`Kandinsky6TI2VAPipeline`] | Flow matching, `guidance_scale=5.0`, 50 steps | +| [`kandinskylab/Kandinsky-6.0-VSR-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-VSR-5s-Diffusers) | [`Kandinsky6SRPipeline`] | Flow matching super-resolution | +| [`kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers`](https://huggingface.co/kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers) | [`Kandinsky6SRPipeline`] | Distilled super-resolution, 2 steps | + +## Text/image-to-video-and-audio + +```python +import torch +from diffusers import Kandinsky6TI2VAPipeline +from diffusers.utils import encode_video + +pipe = Kandinsky6TI2VAPipeline.from_pretrained( + "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers", torch_dtype=torch.bfloat16 +) +pipe.enable_model_cpu_offload() + +output = pipe( + prompt="A cat and a dog baking a cake together in a kitchen.", + height=480, + width=864, + num_frames=121, + num_inference_steps=10, + guidance_scale=1.0, +) +encode_video( + output.frames[0], + fps=24, + output_path="output.mp4", + audio=output.audio[0][None], + audio_sample_rate=pipe.audio_sample_rate, +) +``` + +Pass `image=` to condition the first frame on a reference image, `sample_audio=False` to generate video only, and +`expand_prompts=True` to let the Qwen2.5-VL text encoder rewrite short prompts into detailed ones first. + +## Video super-resolution + +[`Kandinsky6SRPipeline`] takes the frames produced by [`Kandinsky6TI2VAPipeline`] and upscales them by `2`, `4`, or +`2.25` (a 1.125x bilinear pre-upscale followed by the 2x path). The video is split into overlapping tiles, every tile +is refined at one of the tile sizes the SR transformer was trained on, and the tiles are blended back with Hann +windows. + +```python +# required: lets inductor pick flex-attention tiles that fit the SR block mask +torch._inductor.config.max_autotune = True + +sr_pipe = Kandinsky6SRPipeline.from_pretrained( + "kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers", torch_dtype=torch.bfloat16 +) +# The SR transformer always runs NABLA sparse attention on the `flex` backend. Compile it, otherwise flex falls +# back to an eager implementation that needs far more memory at video resolutions. +sr_pipe.enable_model_cpu_offload() +sr_pipe.transformer.set_attention_backend("flex") +sr_pipe.transformer.compile_repeated_blocks(fullgraph=True) + +upscaled = sr_pipe(video=output.frames[0], resolution_scale=2.25, num_inference_steps=2).frames[0] +``` + +## Memory optimization + +Refer to the [Reduce memory usage](../../optimization/memory) guide for the general set of techniques. Both +[`Kandinsky6TI2VAPipeline`] and [`Kandinsky6SRPipeline`] support [model offloading](../../optimization/memory#model-offloading) +(used above) and, for a smaller footprint at the cost of speed, [sequential CPU offloading](../../optimization/memory#cpu-offloading): + +```python +pipe.enable_sequential_cpu_offload() +``` + +[`Kandinsky6TI2VAPipeline`]'s video VAE also supports [tiled decoding](../../optimization/memory#vae-tiling) for high +resolutions or long videos: + +```python +pipe.vae.enable_tiling() +``` + +## Notes + +- `height` and `width` must be divisible by the video VAE's spatial compression ratio times the transformer's patch + size — `16` with the default [`Kandinsky6TI2VAPipeline`] configuration (`AutoencoderKLHunyuanVideo` at a + compression ratio of `8`, `patch_size=(1, 2, 2)`). `480x864`, used in the example above, satisfies this. +- [`Kandinsky6SRPipeline`]'s input `video` must have `1 + k * vae_scale_factor_temporal` frames for some integer `k` + (a temporal compression ratio of `4` with the default K-VAE configuration, so `121` frames works but `120` doesn't) + — trim or pad a video that doesn't already satisfy this before upscaling it. +- `expand_prompts=True` reuses the already-loaded Qwen2.5-VL text encoder for an extra generation pass before + denoising, so it adds latency but no extra model weights. +- Compile the repeated transformer blocks for faster repeated inference: + ```python + pipe.transformer.compile_repeated_blocks(fullgraph=True) + ``` + +## Kandinsky6TI2VAPipeline + +[[autodoc]] Kandinsky6TI2VAPipeline + - all + - __call__ + +## Kandinsky6SRPipeline + +[[autodoc]] Kandinsky6SRPipeline + - all + - __call__ + +## Kandinsky6SRLatentUpscalerBank + +[[autodoc]] Kandinsky6SRLatentUpscalerBank + - forward + +## Kandinsky6TI2VAPipelineOutput + +[[autodoc]] pipelines.kandinsky6.pipeline_output.Kandinsky6TI2VAPipelineOutput + +## Kandinsky6SRPipelineOutput + +[[autodoc]] pipelines.kandinsky6.pipeline_output.Kandinsky6SRPipelineOutput diff --git a/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md b/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md index 69f45576ca10..b87a442272aa 100644 --- a/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md +++ b/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md @@ -448,7 +448,7 @@ SDXL is a large model, and you may need to optimize memory to get it to run on y + refiner.unet = torch.compile(refiner.unet, mode="reduce-overhead", fullgraph=True) ``` -3. Enable [xFormers](../../../optimization/xformers) to run SDXL if `torch<2.0`: +3. Enable [xFormers](../../../optimization/attention_backends) to run SDXL if `torch<2.0`: ```diff + base.enable_xformers_memory_efficient_attention() diff --git a/docs/source/en/api/schedulers/piflow.md b/docs/source/en/api/schedulers/piflow.md new file mode 100644 index 000000000000..1845c05aa5cd --- /dev/null +++ b/docs/source/en/api/schedulers/piflow.md @@ -0,0 +1,30 @@ + + +# PiflowScheduler + +`PiflowScheduler` is the few-step scheduler of the distilled Kandinsky 6 checkpoints, both the +text/image-to-video-and-audio model and the video super-resolution model. It implements +[π-Flow](https://huggingface.co/papers/2510.14974): the transformer predicts `n_grid` denoised estimates per latent +channel at a small number of grid points, and the scheduler integrates a network-free policy between them. + +The reference implementation can be found at [Lakonik/LakonLab](https://github.com/Lakonik/LakonLab). + +## PiflowScheduler + +[[autodoc]] PiflowScheduler + - set_timesteps + - step + +## PiflowSchedulerOutput + +[[autodoc]] schedulers.scheduling_piflow.PiflowSchedulerOutput diff --git a/docs/source/en/optimization/cache_dit.md b/docs/source/en/optimization/cache_dit.md index 9c3edb23fdf7..16beb5ee5b3f 100644 --- a/docs/source/en/optimization/cache_dit.md +++ b/docs/source/en/optimization/cache_dit.md @@ -1,270 +1,84 @@ -## CacheDiT +# CacheDiT -CacheDiT is a unified, flexible, and training-free cache acceleration framework designed to support nearly all Diffusers' DiT-based pipelines. It provides a unified cache API that supports automatic block adapter, DBCache, and more. +[CacheDiT](https://github.com/vipshop/cache-dit) speeds up DiT pipelines by reusing transformer block outputs across denoising steps. It does not need training and supports most Diffusers DiT pipelines, including Flux, Qwen-Image, Wan, and HunyuanVideo. Diffusers also has [built-in caching](./cache) which doesn't require an extra dependency. -To learn more, refer to the [CacheDiT](https://github.com/vipshop/cache-dit) repository. - -Install a stable release of CacheDiT from PyPI or you can install the latest version from GitHub. - - - +Install CacheDiT from PyPI. ```bash -pip3 install -U cache-dit +pip install -U cache-dit ``` - - - -```bash -pip3 install git+https://github.com/vipshop/cache-dit.git -``` - - - - -Run the command below to view supported DiT pipelines. - -```python ->>> import cache_dit ->>> cache_dit.supported_pipelines() -(30, ['Flux*', 'Mochi*', 'CogVideoX*', 'Wan*', 'HunyuanVideo*', 'QwenImage*', 'LTX*', 'Allegro*', -'CogView3Plus*', 'CogView4*', 'Cosmos*', 'EasyAnimate*', 'SkyReelsV2*', 'StableDiffusion3*', -'ConsisID*', 'DiT*', 'Amused*', 'Bria*', 'Lumina*', 'OmniGen*', 'PixArt*', 'Sana*', 'StableAudio*', -'VisualCloze*', 'AuraFlow*', 'Chroma*', 'ShapE*', 'HiDream*', 'HunyuanDiT*', 'HunyuanDiTPAG*']) -``` +Call `cache_dit.supported_pipelines()` to list the pipeline families CacheDiT supports. -For a complete benchmark, please refer to [Benchmarks](https://github.com/vipshop/cache-dit/blob/main/bench/). - - -## Unified Cache API - -CacheDiT works by matching specific input/output patterns as shown below. - -![](https://github.com/vipshop/cache-dit/raw/main/assets/patterns-v1.png) - -Call the `enable_cache()` function on a pipeline to enable cache acceleration. This function is the entry point to many of CacheDiT's features. - -```python +```py import cache_dit -from diffusers import DiffusionPipeline - -# Can be any diffusion pipeline -pipe = DiffusionPipeline.from_pretrained("Qwen/Qwen-Image") - -# One-line code with default cache options. -cache_dit.enable_cache(pipe) -# Just call the pipe as normal. -output = pipe(...) - -# Disable cache and run original pipe. -cache_dit.disable_cache(pipe) +cache_dit.supported_pipelines() ``` -## Automatic Block Adapter - -For custom or modified pipelines or transformers not included in Diffusers, use the `BlockAdapter` in `auto` mode or via manual configuration. Please check the [BlockAdapter](https://github.com/vipshop/cache-dit/blob/main/docs/User_Guide.md#automatic-block-adapter) docs for more details. Refer to [Qwen-Image w/ BlockAdapter](https://github.com/vipshop/cache-dit/blob/main/examples/adapter/run_qwen_image_adapter.py) as an example. - - -```python -from cache_dit import ForwardPattern, BlockAdapter +## Enable caching -# Use 🔥BlockAdapter with `auto` mode. -cache_dit.enable_cache( - BlockAdapter( - # Any DiffusionPipeline, Qwen-Image, etc. - pipe=pipe, auto=True, - # Check `📚Forward Pattern Matching` documentation and hack the code of - # of Qwen-Image, you will find that it has satisfied `FORWARD_PATTERN_1`. - forward_pattern=ForwardPattern.Pattern_1, - ), -) +Call `cache_dit.enable_cache` on a pipeline to cache it with the default settings, then run the pipeline as usual. -# Or, manually setup transformer configurations. -cache_dit.enable_cache( - BlockAdapter( - pipe=pipe, # Qwen-Image, etc. - transformer=pipe.transformer, - blocks=pipe.transformer.transformer_blocks, - forward_pattern=ForwardPattern.Pattern_1, - ), -) -``` +```py +import torch +import cache_dit +from diffusers import FluxPipeline -Sometimes, a Transformer class will contain more than one transformer `blocks`. For example, FLUX.1 (HiDream, Chroma, etc) contains `transformer_blocks` and `single_transformer_blocks` (with different forward patterns). The BlockAdapter is able to detect this hybrid pattern type as well. -Refer to [FLUX.1](https://github.com/vipshop/cache-dit/blob/main/examples/adapter/run_flux_adapter.py) as an example. +pipeline = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", dtype=torch.bfloat16 +).to("cuda") +cache_dit.enable_cache(pipeline) -```python -# For diffusers <= 0.34.0, FLUX.1 transformer_blocks and -# single_transformer_blocks have different forward patterns. -cache_dit.enable_cache( - BlockAdapter( - pipe=pipe, # FLUX.1, etc. - transformer=pipe.transformer, - blocks=[ - pipe.transformer.transformer_blocks, - pipe.transformer.single_transformer_blocks, - ], - forward_pattern=[ - ForwardPattern.Pattern_1, - ForwardPattern.Pattern_3, - ], - ), -) +image = pipeline( + "A cat holding a sign that says hello world", num_inference_steps=28 +).images[0] ``` -This also works if there is more than one transformer (namely `transformer` and `transformer_2`) in its structure. Refer to [Wan 2.2 MoE](https://github.com/vipshop/cache-dit/blob/main/examples/pipeline/run_wan_2.2.py) as an example. - -## Patch Functor - -For any pattern not included in CacheDiT, use the Patch Functor to convert the pattern into a known pattern. You need to subclass the Patch Functor and may also need to fuse the operations within the blocks for loop into block `forward`. After implementing a Patch Functor, set the `patch_functor` property in `BlockAdapter`. +CacheDiT also works with `torch.compile`. Compile the transformer after you call `enable_cache`. See the [compile](https://github.com/vipshop/cache-dit/blob/main/docs/user_guide/COMPILE.md) docs for settings that avoid recompilation with dynamic input shapes. -![](https://github.com/vipshop/cache-dit/raw/main/assets/patch-functor.png) - -Some Patch Functors are already provided in CacheDiT, [HiDreamPatchFunctor](https://github.com/vipshop/cache-dit/blob/main/src/cache_dit/cache_factory/patch_functors/functor_hidream.py), [ChromaPatchFunctor](https://github.com/vipshop/cache-dit/blob/main/src/cache_dit/cache_factory/patch_functors/functor_chroma.py), etc. - -```python -@BlockAdapterRegistry.register("HiDream") -def hidream_adapter(pipe, **kwargs) -> BlockAdapter: - from diffusers import HiDreamImageTransformer2DModel - from cache_dit.cache_factory.patch_functors import HiDreamPatchFunctor - - assert isinstance(pipe.transformer, HiDreamImageTransformer2DModel) - return BlockAdapter( - pipe=pipe, - transformer=pipe.transformer, - blocks=[ - pipe.transformer.double_stream_blocks, - pipe.transformer.single_stream_blocks, - ], - forward_pattern=[ - ForwardPattern.Pattern_0, - ForwardPattern.Pattern_3, - ], - # NOTE: Setup your custom patch functor here. - patch_functor=HiDreamPatchFunctor(), - **kwargs, - ) +```py +pipeline.transformer = torch.compile(pipeline.transformer) ``` -Finally, you can call the `cache_dit.summary()` function on a pipeline after its completed inference to get the cache acceleration details. +Call `cache_dit.summary` after inference to log how many steps were cached and the residual differences between steps. -```python -stats = cache_dit.summary(pipe) +```py +stats = cache_dit.summary(pipeline) ``` -```python -⚡️Cache Steps and Residual Diffs Statistics: QwenImagePipeline +Call `cache_dit.disable_cache` to restore the original pipeline. -| Cache Steps | Diffs Min | Diffs P25 | Diffs P50 | Diffs P75 | Diffs P95 | Diffs Max | -|-------------|-----------|-----------|-----------|-----------|-----------|-----------| -| 23 | 0.045 | 0.084 | 0.114 | 0.147 | 0.241 | 0.297 | +```py +cache_dit.disable_cache(pipeline) ``` -## DBCache: Dual Block Cache - -![](https://github.com/vipshop/cache-dit/raw/main/assets/dbcache-v1.png) - -DBCache (Dual Block Caching) supports different configurations of compute blocks (F8B12, etc.) to enable a balanced trade-off between performance and precision. -- Fn_compute_blocks: Specifies that DBCache uses the **first n** Transformer blocks to fit the information at time step t, enabling the calculation of a more stable L1 diff and delivering more accurate information to subsequent blocks. -- Bn_compute_blocks: Further fuses approximate information in the **last n** Transformer blocks to enhance prediction accuracy. These blocks act as an auto-scaler for approximate hidden states that use residual cache. - - -```python -import cache_dit -from diffusers import FluxPipeline +## Configure the cache -pipe_or_adapter = FluxPipeline.from_pretrained( - "black-forest-labs/FLUX.1-dev", - dtype=torch.bfloat16, -).to("cuda") # or "mps", "xpu", "cpu" +DBCache (Dual Block Cache) computes the first n blocks (Fn) at every step. When their output barely changes from the previous step, it reuses the cached output for the remaining blocks, and it can recompute the last n blocks (Bn) to correct it. The TaylorSeer calibrator predicts the cached output from earlier steps instead of reusing it as is. -# Default options, F8B0, 8 warmup steps, and unlimited cached -# steps for good balance between performance and precision -cache_dit.enable_cache(pipe_or_adapter) +`enable_cache` defaults to DBCache with the first 8 blocks always computed (F8B0) and 8 uncached warmup steps. To trade speed for quality, raise `Fn_compute_blocks` or lower `residual_diff_threshold` (default `0.08`). For the best quality at high cache rates, add the TaylorSeer calibrator. -# Custom options, F8B8, higher precision -from cache_dit import BasicCacheConfig +```py +from cache_dit import DBCacheConfig, TaylorSeerCalibratorConfig cache_dit.enable_cache( - pipe_or_adapter, - cache_config=BasicCacheConfig( - max_warmup_steps=8, # steps do not cache - max_cached_steps=-1, # -1 means no limit - Fn_compute_blocks=8, # Fn, F8, etc. - Bn_compute_blocks=8, # Bn, B8, etc. + pipeline, + cache_config=DBCacheConfig( + max_warmup_steps=8, + Fn_compute_blocks=8, + Bn_compute_blocks=0, residual_diff_threshold=0.12, ), -) -``` -Check the [DBCache](https://github.com/vipshop/cache-dit/blob/main/docs/DBCache.md) and [User Guide](https://github.com/vipshop/cache-dit/blob/main/docs/User_Guide.md#dbcache) docs for more design details. - -## TaylorSeer Calibrator - -The [TaylorSeers](https://huggingface.co/papers/2503.06923) algorithm further improves the precision of DBCache in cases where the cached steps are large (Hybrid TaylorSeer + DBCache). At timesteps with significant intervals, the feature similarity in diffusion models decreases substantially, significantly harming the generation quality. - -TaylorSeer employs a differential method to approximate the higher-order derivatives of features and predict features in future timesteps with Taylor series expansion. The TaylorSeer implemented in CacheDiT supports both hidden states and residual cache types. F_pred can be a residual cache or a hidden-state cache. - -```python -from cache_dit import BasicCacheConfig, TaylorSeerCalibratorConfig - -cache_dit.enable_cache( - pipe_or_adapter, - # Basic DBCache w/ FnBn configurations - cache_config=BasicCacheConfig( - max_warmup_steps=8, # steps do not cache - max_cached_steps=-1, # -1 means no limit - Fn_compute_blocks=8, # Fn, F8, etc. - Bn_compute_blocks=8, # Bn, B8, etc. - residual_diff_threshold=0.12, - ), - # Then, you can use the TaylorSeer Calibrator to approximate - # the values in cached steps, taylorseer_order default is 1. - calibrator_config=TaylorSeerCalibratorConfig( - taylorseer_order=1, - ), -) -``` - -> [!TIP] -> The `Bn_compute_blocks` parameter of DBCache can be set to `0` if you use TaylorSeer as the calibrator for approximate hidden states. DBCache's `Bn_compute_blocks` also acts as a calibrator, so you can choose either `Bn_compute_blocks` > 0 or TaylorSeer. We recommend using the configuration scheme of TaylorSeer + DBCache FnB0. - -## Hybrid Cache CFG - -CacheDiT supports caching for CFG (classifier-free guidance). For models that fuse CFG and non-CFG into a single forward step, or models that do not include CFG in the forward step, please set `enable_separate_cfg` parameter to `False (default, None)`. Otherwise, set it to `True`. - -```python -from cache_dit import BasicCacheConfig - -cache_dit.enable_cache( - pipe_or_adapter, - cache_config=BasicCacheConfig( - ..., - # For example, set it as True for Wan 2.1, Qwen-Image - # and set it as False for FLUX.1, HunyuanVideo, etc. - enable_separate_cfg=True, - ), + calibrator_config=TaylorSeerCalibratorConfig(taylorseer_order=1), ) ``` -## torch.compile - -CacheDiT is designed to work with torch.compile for even better performance. Call `torch.compile` after enabling the cache. - +For supported pipelines, CacheDiT already knows whether CFG runs as a separate forward pass. For other models, set `enable_separate_cfg=True` in `DBCacheConfig` if the model runs the conditional and unconditional passes separately, or `False` if it fuses them or doesn't use CFG. -```python -cache_dit.enable_cache(pipe) +See the [DBCache design](https://github.com/vipshop/cache-dit/blob/main/docs/user_guide/DBCACHE_DESIGN.md) docs for how the Fn and Bn blocks work, and the [cache benchmarks](https://github.com/vipshop/cache-dit/blob/main/bench/cache/README.md) for speed and quality numbers. -# Compile the Transformer module -pipe.transformer = torch.compile(pipe.transformer) -``` - -If you're using CacheDiT with dynamic input shapes, consider increasing the `recompile_limit` of `torch._dynamo`. Otherwise, the `recompile_limit` error may be triggered, causing the module to fall back to eager mode. - -```python -torch._dynamo.config.recompile_limit = 96 # default is 8 -torch._dynamo.config.accumulated_recompile_limit = 2048 # default is 256 -``` +## Next steps -Please check [perf.py](https://github.com/vipshop/cache-dit/blob/main/bench/perf.py) for more details. +- For pipelines CacheDiT doesn't support yet, see the [BlockAdapter](https://github.com/vipshop/cache-dit/blob/main/docs/user_guide/CACHE_API.md#automatic-block-adapter) docs. +- CacheDiT also supports [context parallelism](https://github.com/vipshop/cache-dit/blob/main/docs/user_guide/CONTEXT_PARALLEL.md) and [quantization](https://github.com/vipshop/cache-dit/blob/main/docs/user_guide/QUANTIZATION.md). diff --git a/docs/source/en/optimization/deepcache.md b/docs/source/en/optimization/deepcache.md deleted file mode 100644 index 2514867a504f..000000000000 --- a/docs/source/en/optimization/deepcache.md +++ /dev/null @@ -1,62 +0,0 @@ - - -# DeepCache -[DeepCache](https://huggingface.co/papers/2312.00858) accelerates [`StableDiffusionPipeline`] and [`StableDiffusionXLPipeline`] by strategically caching and reusing high-level features while efficiently updating low-level features by taking advantage of the U-Net architecture. - -Start by installing [DeepCache](https://github.com/horseee/DeepCache): -```bash -pip install DeepCache -``` - -Then load and enable the [`DeepCacheSDHelper`](https://github.com/horseee/DeepCache#usage): - -```diff - import torch - from diffusers import StableDiffusionPipeline - pipe = StableDiffusionPipeline.from_pretrained('stable-diffusion-v1-5/stable-diffusion-v1-5', dtype=torch.float16).to("cuda") # or "mps", "xpu", "cpu" - -+ from DeepCache import DeepCacheSDHelper -+ helper = DeepCacheSDHelper(pipe=pipe) -+ helper.set_params( -+ cache_interval=3, -+ cache_branch_id=0, -+ ) -+ helper.enable() - - image = pipe("a photo of an astronaut on a moon").images[0] -``` - -The `set_params` method accepts two arguments: `cache_interval` and `cache_branch_id`. `cache_interval` means the frequency of feature caching, specified as the number of steps between each cache operation. `cache_branch_id` identifies which branch of the network (ordered from the shallowest to the deepest layer) is responsible for executing the caching processes. -Opting for a lower `cache_branch_id` or a larger `cache_interval` can lead to faster inference speed at the expense of reduced image quality (ablation experiments of these two hyperparameters can be found in the [paper](https://huggingface.co/papers/2312.00858)). Once those arguments are set, use the `enable` or `disable` methods to activate or deactivate the `DeepCacheSDHelper`. - -
- -
- -You can find more generated samples (original pipeline vs DeepCache) and the corresponding inference latency in the [WandB report](https://wandb.ai/horseee/DeepCache/runs/jwlsqqgt?workspace=user-horseee). The prompts are randomly selected from the [MS-COCO 2017](https://cocodataset.org/#home) dataset. - -## Benchmark - -We tested how much faster DeepCache accelerates [Stable Diffusion v2.1](https://huggingface.co/stabilityai/stable-diffusion-2-1) with 50 inference steps on an NVIDIA RTX A5000, using different configurations for resolution, batch size, cache interval (I), and cache branch (B). - -| **Resolution** | **Batch size** | **Original** | **DeepCache(I=3, B=0)** | **DeepCache(I=5, B=0)** | **DeepCache(I=5, B=1)** | -|----------------|----------------|--------------|-------------------------|-------------------------|-------------------------| -| 512| 8| 15.96| 6.88(2.32x)| 5.03(3.18x)| 7.27(2.20x)| -| | 4| 8.39| 3.60(2.33x)| 2.62(3.21x)| 3.75(2.24x)| -| | 1| 2.61| 1.12(2.33x)| 0.81(3.24x)| 1.11(2.35x)| -| 768| 8| 43.58| 18.99(2.29x)| 13.96(3.12x)| 21.27(2.05x)| -| | 4| 22.24| 9.67(2.30x)| 7.10(3.13x)| 10.74(2.07x)| -| | 1| 6.33| 2.72(2.33x)| 1.97(3.21x)| 2.98(2.12x)| -| 1024| 8| 101.95| 45.57(2.24x)| 33.72(3.02x)| 53.00(1.92x)| -| | 4| 49.25| 21.86(2.25x)| 16.19(3.04x)| 25.78(1.91x)| -| | 1| 13.83| 6.07(2.28x)| 4.43(3.12x)| 7.15(1.93x)| diff --git a/docs/source/en/optimization/tgate.md b/docs/source/en/optimization/tgate.md deleted file mode 100644 index 57e18090c03d..000000000000 --- a/docs/source/en/optimization/tgate.md +++ /dev/null @@ -1,182 +0,0 @@ -# T-GATE - -[T-GATE](https://github.com/HaozheLiu-ST/T-GATE/tree/main) accelerates inference for [Stable Diffusion](../api/pipelines/stable_diffusion/overview), [PixArt](../api/pipelines/pixart), and [Latency Consistency Model](../api/pipelines/latent_consistency_models.md) pipelines by skipping the cross-attention calculation once it converges. This method doesn't require any additional training and it can speed up inference from 10-50%. T-GATE is also compatible with other optimization methods like [DeepCache](./deepcache). - -Before you begin, make sure you install T-GATE. - -```bash -pip install tgate -pip install -U torch diffusers transformers accelerate DeepCache -``` - - -To use T-GATE with a pipeline, you need to use its corresponding loader. - -| Pipeline | T-GATE Loader | -|---|---| -| PixArt | TgatePixArtLoader | -| Stable Diffusion XL | TgateSDXLLoader | -| Stable Diffusion XL + DeepCache | TgateSDXLDeepCacheLoader | -| Stable Diffusion | TgateSDLoader | -| Stable Diffusion + DeepCache | TgateSDDeepCacheLoader | - -Next, create a `TgateLoader` with a pipeline, the gate step (the time step to stop calculating the cross attention), and the number of inference steps. Then call the `tgate` method on the pipeline with a prompt, gate step, and the number of inference steps. - -Let's see how to enable this for several different pipelines. - - - - -Accelerate `PixArtAlphaPipeline` with T-GATE: - -```py -import torch -from diffusers import PixArtAlphaPipeline -from tgate import TgatePixArtLoader - -pipe = PixArtAlphaPipeline.from_pretrained("PixArt-alpha/PixArt-XL-2-1024-MS", dtype=torch.float16) - -gate_step = 8 -inference_step = 25 -pipe = TgatePixArtLoader( - pipe, - gate_step=gate_step, - num_inference_steps=inference_step, -).to("cuda") # or "mps", "xpu", "cpu" - -image = pipe.tgate( - "An alpaca made of colorful building blocks, cyberpunk.", - gate_step=gate_step, - num_inference_steps=inference_step, -).images[0] -``` - - - -Accelerate `StableDiffusionXLPipeline` with T-GATE: - -```py -import torch -from diffusers import StableDiffusionXLPipeline -from diffusers import DPMSolverMultistepScheduler -from tgate import TgateSDXLLoader - -pipe = StableDiffusionXLPipeline.from_pretrained( - "stabilityai/stable-diffusion-xl-base-1.0", - dtype=torch.float16, - variant="fp16", - use_safetensors=True, -) -pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) - -gate_step = 10 -inference_step = 25 -pipe = TgateSDXLLoader( - pipe, - gate_step=gate_step, - num_inference_steps=inference_step, -).to("cuda") # or "mps", "xpu", "cpu" - -image = pipe.tgate( - "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k.", - gate_step=gate_step, - num_inference_steps=inference_step -).images[0] -``` - - - -Accelerate `StableDiffusionXLPipeline` with [DeepCache](https://github.com/horseee/DeepCache) and T-GATE: - -```py -import torch -from diffusers import StableDiffusionXLPipeline -from diffusers import DPMSolverMultistepScheduler -from tgate import TgateSDXLDeepCacheLoader - -pipe = StableDiffusionXLPipeline.from_pretrained( - "stabilityai/stable-diffusion-xl-base-1.0", - dtype=torch.float16, - variant="fp16", - use_safetensors=True, -) -pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) - -gate_step = 10 -inference_step = 25 -pipe = TgateSDXLDeepCacheLoader( - pipe, - cache_interval=3, - cache_branch_id=0, -).to("cuda") # or "mps", "xpu", "cpu" - -image = pipe.tgate( - "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k.", - gate_step=gate_step, - num_inference_steps=inference_step -).images[0] -``` - - - -Accelerate `latent-consistency/lcm-sdxl` with T-GATE: - -```py -import torch -from diffusers import StableDiffusionXLPipeline -from diffusers import UNet2DConditionModel, LCMScheduler -from diffusers import DPMSolverMultistepScheduler -from tgate import TgateSDXLLoader - -unet = UNet2DConditionModel.from_pretrained( - "latent-consistency/lcm-sdxl", - dtype=torch.float16, - variant="fp16", -) -pipe = StableDiffusionXLPipeline.from_pretrained( - "stabilityai/stable-diffusion-xl-base-1.0", - unet=unet, - dtype=torch.float16, - variant="fp16", -) -pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config) - -gate_step = 1 -inference_step = 4 -pipe = TgateSDXLLoader( - pipe, - gate_step=gate_step, - num_inference_steps=inference_step, - lcm=True -).to("cuda") # or "mps", "xpu", "cpu" - -image = pipe.tgate( - "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k.", - gate_step=gate_step, - num_inference_steps=inference_step -).images[0] -``` - - - -T-GATE also supports [`StableDiffusionPipeline`] and [PixArt-alpha/PixArt-LCM-XL-2-1024-MS](https://hf.co/PixArt-alpha/PixArt-LCM-XL-2-1024-MS). - -## Benchmarks -| Model | MACs | Param | Latency | Zero-shot 10K-FID on MS-COCO | -|-----------------------|----------|-----------|---------|---------------------------| -| SD-1.5 | 16.938T | 859.520M | 7.032s | 23.927 | -| SD-1.5 w/ T-GATE | 9.875T | 815.557M | 4.313s | 20.789 | -| SD-2.1 | 38.041T | 865.785M | 16.121s | 22.609 | -| SD-2.1 w/ T-GATE | 22.208T | 815.433 M | 9.878s | 19.940 | -| SD-XL | 149.438T | 2.570B | 53.187s | 24.628 | -| SD-XL w/ T-GATE | 84.438T | 2.024B | 27.932s | 22.738 | -| Pixart-Alpha | 107.031T | 611.350M | 61.502s | 38.669 | -| Pixart-Alpha w/ T-GATE | 65.318T | 462.585M | 37.867s | 35.825 | -| DeepCache (SD-XL) | 57.888T | - | 19.931s | 23.755 | -| DeepCache w/ T-GATE | 43.868T | - | 14.666s | 23.999 | -| LCM (SD-XL) | 11.955T | 2.570B | 3.805s | 25.044 | -| LCM w/ T-GATE | 11.171T | 2.024B | 3.533s | 25.028 | -| LCM (Pixart-Alpha) | 8.563T | 611.350M | 4.733s | 36.086 | -| LCM w/ T-GATE | 7.623T | 462.585M | 4.543s | 37.048 | - -The latency is tested on an NVIDIA 1080TI, MACs and Params are calculated with [calflops](https://github.com/MrYxJ/calculate-flops.pytorch), and the FID is calculated with [PytorchFID](https://github.com/mseitzer/pytorch-fid). diff --git a/docs/source/en/optimization/tome.md b/docs/source/en/optimization/tome.md deleted file mode 100644 index 833bd69058a9..000000000000 --- a/docs/source/en/optimization/tome.md +++ /dev/null @@ -1,96 +0,0 @@ - - -# Token merging - -[Token merging](https://huggingface.co/papers/2303.17604) (ToMe) merges redundant tokens/patches progressively in the forward pass of a Transformer-based network which can speed-up the inference latency of [`StableDiffusionPipeline`]. - -Install ToMe from `pip`: - -```bash -pip install tomesd -``` - -You can use ToMe from the [`tomesd`](https://github.com/dbolya/tomesd) library with the [`apply_patch`](https://github.com/dbolya/tomesd?tab=readme-ov-file#usage) function: - -```diff - from diffusers import StableDiffusionPipeline - import torch - import tomesd - - pipeline = StableDiffusionPipeline.from_pretrained( - "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, use_safetensors=True, - ).to("cuda") # or "mps", "xpu", "cpu" -+ tomesd.apply_patch(pipeline, ratio=0.5) - - image = pipeline("a photo of an astronaut riding a horse on mars").images[0] -``` - -The `apply_patch` function exposes a number of [arguments](https://github.com/dbolya/tomesd#usage) to help strike a balance between pipeline inference speed and the quality of the generated tokens. The most important argument is `ratio` which controls the number of tokens that are merged during the forward pass. - -As reported in the [paper](https://huggingface.co/papers/2303.17604), ToMe can greatly preserve the quality of the generated images while boosting inference speed. By increasing the `ratio`, you can speed-up inference even further, but at the cost of some degraded image quality. - -To test the quality of the generated images, we sampled a few prompts from [Parti Prompts](https://parti.research.google/) and performed inference with the [`StableDiffusionPipeline`] with the following settings: - -
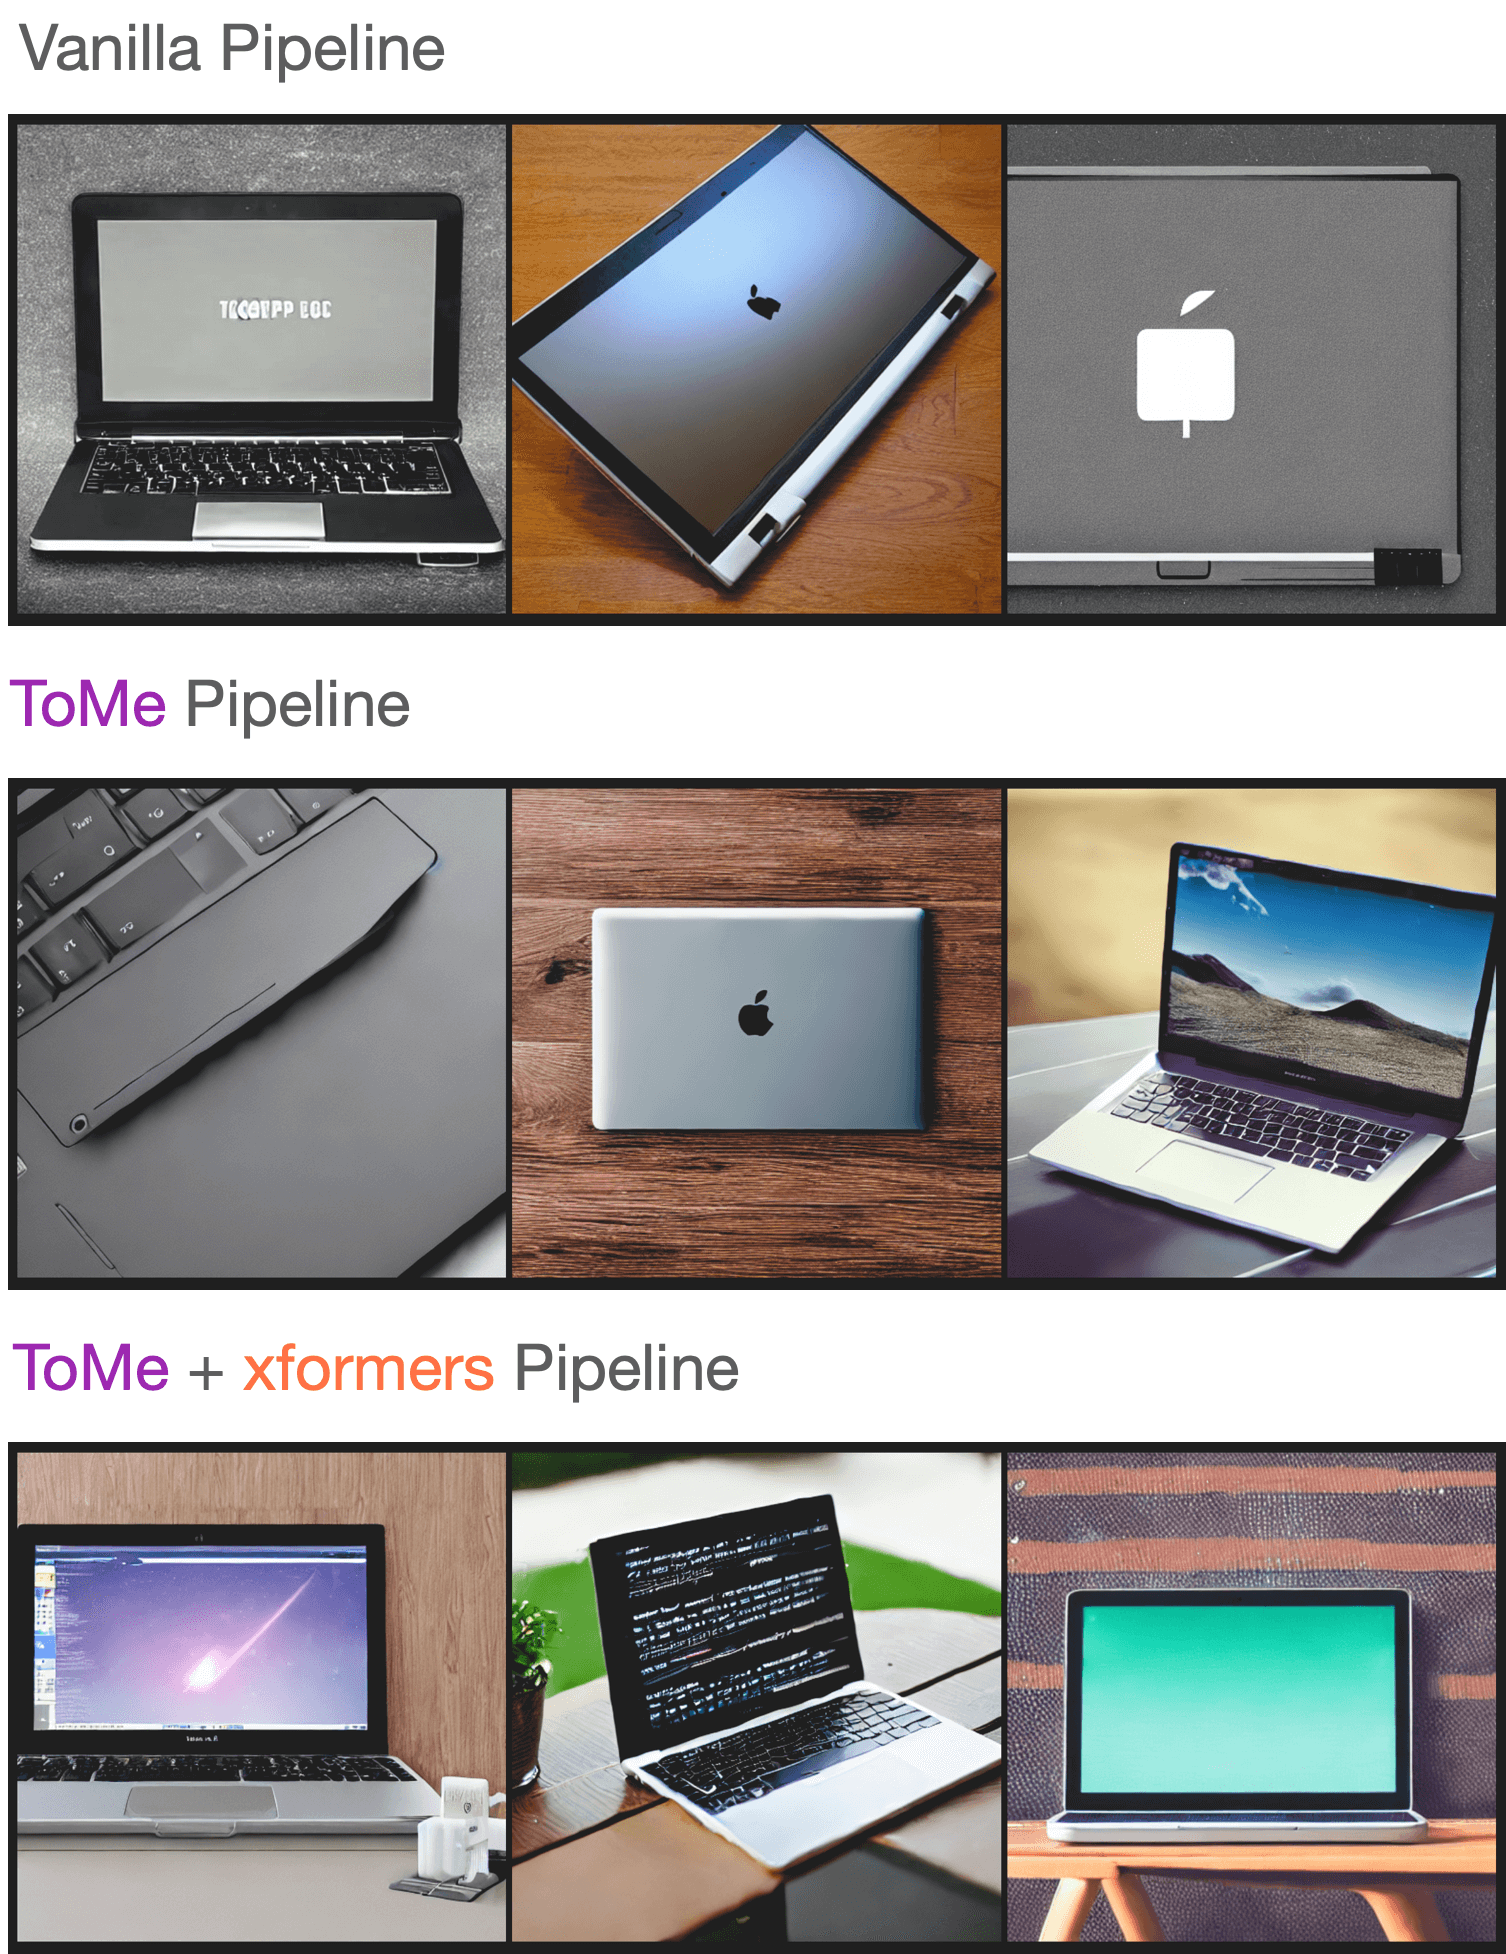
- -
- -We didn’t notice any significant decrease in the quality of the generated samples, and you can check out the generated samples in this [WandB report](https://wandb.ai/sayakpaul/tomesd-results/runs/23j4bj3i?workspace=). If you're interested in reproducing this experiment, use this [script](https://gist.github.com/sayakpaul/8cac98d7f22399085a060992f411ecbd). - -## Benchmarks - -We also benchmarked the impact of `tomesd` on the [`StableDiffusionPipeline`] with [xFormers](https://huggingface.co/docs/diffusers/optimization/xformers) enabled across several image resolutions. The results are obtained from A100 and V100 GPUs in the following development environment: - -```bash -- `diffusers` version: 0.15.1 -- Python version: 3.8.16 -- PyTorch version (GPU?): 1.13.1+cu116 (True) -- Huggingface_hub version: 0.13.2 -- Transformers version: 4.27.2 -- Accelerate version: 0.18.0 -- xFormers version: 0.0.16 -- tomesd version: 0.1.2 -``` - -To reproduce this benchmark, feel free to use this [script](https://gist.github.com/sayakpaul/27aec6bca7eb7b0e0aa4112205850335). The results are reported in seconds, and where applicable we report the speed-up percentage over the vanilla pipeline when using ToMe and ToMe + xFormers. - -| **GPU** | **Resolution** | **Batch size** | **Vanilla** | **ToMe** | **ToMe + xFormers** | -|----------|----------------|----------------|-------------|----------------|---------------------| -| **A100** | 512 | 10 | 6.88 | 5.26 (+23.55%) | 4.69 (+31.83%) | -| | 768 | 10 | OOM | 14.71 | 11 | -| | | 8 | OOM | 11.56 | 8.84 | -| | | 4 | OOM | 5.98 | 4.66 | -| | | 2 | 4.99 | 3.24 (+35.07%) | 2.1 (+37.88%) | -| | | 1 | 3.29 | 2.24 (+31.91%) | 2.03 (+38.3%) | -| | 1024 | 10 | OOM | OOM | OOM | -| | | 8 | OOM | OOM | OOM | -| | | 4 | OOM | 12.51 | 9.09 | -| | | 2 | OOM | 6.52 | 4.96 | -| | | 1 | 6.4 | 3.61 (+43.59%) | 2.81 (+56.09%) | -| **V100** | 512 | 10 | OOM | 10.03 | 9.29 | -| | | 8 | OOM | 8.05 | 7.47 | -| | | 4 | 5.7 | 4.3 (+24.56%) | 3.98 (+30.18%) | -| | | 2 | 3.14 | 2.43 (+22.61%) | 2.27 (+27.71%) | -| | | 1 | 1.88 | 1.57 (+16.49%) | 1.57 (+16.49%) | -| | 768 | 10 | OOM | OOM | 23.67 | -| | | 8 | OOM | OOM | 18.81 | -| | | 4 | OOM | 11.81 | 9.7 | -| | | 2 | OOM | 6.27 | 5.2 | -| | | 1 | 5.43 | 3.38 (+37.75%) | 2.82 (+48.07%) | -| | 1024 | 10 | OOM | OOM | OOM | -| | | 8 | OOM | OOM | OOM | -| | | 4 | OOM | OOM | 19.35 | -| | | 2 | OOM | 13 | 10.78 | -| | | 1 | OOM | 6.66 | 5.54 | - -As seen in the tables above, the speed-up from `tomesd` becomes more pronounced for larger image resolutions. It is also interesting to note that with `tomesd`, it is possible to run the pipeline on a higher resolution like 1024x1024. You may be able to speed-up inference even more with [`torch.compile`](fp16#torchcompile). diff --git a/docs/source/en/optimization/xformers.md b/docs/source/en/optimization/xformers.md deleted file mode 100644 index a5ef4c6fbdb9..000000000000 --- a/docs/source/en/optimization/xformers.md +++ /dev/null @@ -1,29 +0,0 @@ - - -# xFormers - -We recommend [xFormers](https://github.com/facebookresearch/xformers) for both inference and training. In our tests, the optimizations performed in the attention blocks allow for both faster speed and reduced memory consumption. - -Install xFormers from `pip`: - -```bash -pip install xformers -``` - -> [!TIP] -> The xFormers `pip` package requires the latest version of PyTorch. If you need to use a previous version of PyTorch, then we recommend [installing xFormers from the source](https://github.com/facebookresearch/xformers#installing-xformers). - -After xFormers is installed, you can use it with [`~ModelMixin.set_attention_backend`] as shown in the [Attention backends](./attention_backends) guide. - -> [!WARNING] -> According to this [issue](https://github.com/huggingface/diffusers/issues/2234#issuecomment-1416931212), xFormers `v0.0.16` cannot be used for training (fine-tune or DreamBooth) in some GPUs. If you observe this problem, please install a development version as indicated in the issue comments. diff --git a/docs/source/en/training/controlnet.md b/docs/source/en/training/controlnet.md index f52ba33f242f..9cb7526dd131 100644 --- a/docs/source/en/training/controlnet.md +++ b/docs/source/en/training/controlnet.md @@ -14,7 +14,7 @@ specific language governing permissions and limitations under the License. [ControlNet](https://hf.co/papers/2302.05543) models are adapters trained on top of another pretrained model. It allows for a greater degree of control over image generation by conditioning the model with an additional input image. The input image can be a canny edge, depth map, human pose, and many more. -If you're training on a GPU with limited vRAM, you should try enabling the `gradient_checkpointing`, `gradient_accumulation_steps`, and `mixed_precision` parameters in the training command. You can also reduce your memory footprint by using memory-efficient attention with [xFormers](../optimization/xformers). +If you're training on a GPU with limited vRAM, you should try enabling the `gradient_checkpointing`, `gradient_accumulation_steps`, and `mixed_precision` parameters in the training command. You can also reduce your memory footprint by using memory-efficient attention with [xFormers](../optimization/attention_backends). This guide will explore the [train_controlnet.py](https://github.com/huggingface/diffusers/blob/main/examples/controlnet/train_controlnet.py) training script to help you become familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/training/dreambooth.md b/docs/source/en/training/dreambooth.md index ed2a79c8a889..87d8817055db 100644 --- a/docs/source/en/training/dreambooth.md +++ b/docs/source/en/training/dreambooth.md @@ -16,7 +16,7 @@ specific language governing permissions and limitations under the License. To load a trained checkpoint for inference, see [Load a DreamBooth model for inference](../using-diffusers/dreambooth). -If you're training on a GPU with limited vRAM, you should try enabling the `gradient_checkpointing` and `mixed_precision` parameters in the training command. You can also reduce your memory footprint by using memory-efficient attention with [xFormers](../optimization/xformers). +If you're training on a GPU with limited vRAM, you should try enabling the `gradient_checkpointing` and `mixed_precision` parameters in the training command. You can also reduce your memory footprint by using memory-efficient attention with [xFormers](../optimization/attention_backends). This guide will explore the [train_dreambooth.py](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth.py) script to help you become more familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/training/jobs.md b/docs/source/en/training/jobs.md new file mode 100644 index 000000000000..ed4677cb765c --- /dev/null +++ b/docs/source/en/training/jobs.md @@ -0,0 +1,137 @@ + + +# Hugging Face Jobs + +[Hugging Face Jobs](https://huggingface.co/docs/hub/jobs) runs on Hugging Face GPUs, so you don't need to set up a machine, and the run keeps going if you close your terminal. The Diffusers training scripts run on Jobs straight from their GitHub URL without needing to clone the repository or install anything locally. + +Before you start, follow the [Jobs quickstart](https://huggingface.co/docs/hub/jobs-quickstart) to install the `hf` CLI, log in, and add credits to your account. + +## Train a LoRA on Jobs + +The command below trains a LoRA for [FLUX.2-klein-4B](https://huggingface.co/black-forest-labs/FLUX.2-klein-4B) on the five dog photos in [diffusers/dog-example](https://huggingface.co/datasets/diffusers/dog-example). It runs on a single A10G and pushes the LoRA to your namespace on the Hub. + +```bash +# 20 steps is a test run. For a real run, raise --max_train_steps +# (the FLUX.2 README uses 500) and --timeout to match. +hf jobs uv run --flavor a10g-small --timeout 30m -s HF_TOKEN -- \ + https://raw.githubusercontent.com/huggingface/diffusers/main/examples/dreambooth/train_dreambooth_lora_flux2_klein.py \ + --pretrained_model_name_or_path black-forest-labs/FLUX.2-klein-4B \ + --dataset_name diffusers/dog-example \ + --instance_prompt "a photo of sks dog" \ + --resolution 512 --mixed_precision bf16 --guidance_scale 1 \ + --gradient_checkpointing --cache_latents \ + --optimizer adamW --use_8bit_adam --learning_rate 1e-4 \ + --max_train_steps 20 --seed 0 \ + --output_dir /tmp/out \ + --push_to_hub --hub_model_id your-username/klein-dog-lora +``` + +`uv` installs the dependencies listed in the script's `# /// script` header, including Diffusers from `main`. Jobs don't get a Hugging Face token by default, so `-s HF_TOKEN` forwards yours to let the script push the LoRA. The Job's disk is discarded when the Job ends, and anything you don't push is lost. The [DreamBooth](./dreambooth) and [LoRA](./lora) guides explain the training arguments. + +## Managing a Job + +The training logs print to your terminal while the Job runs. Closing the terminal or pressing `Ctrl+C` doesn't stop training, because the Job runs on Hugging Face's machines. To launch a long run without tying up your terminal, add `-d` before `--`. The command prints the Job ID and returns. + +Use the Job ID to reattach to the logs, check GPU memory and utilization while the model trains, or stop a run. + +```bash +hf jobs logs -f +hf jobs stats +hf jobs cancel +``` + +If the run fails, `hf jobs inspect ` shows the error message. See [Manage Jobs](https://huggingface.co/docs/hub/jobs-manage) for the other commands. + +## Train on your own images + +To train on your images, mount their folder into the Job with `-v` and pass the mount path to `--instance_data_dir` instead of `--dataset_name`. Jobs uploads the folder to a private bucket before the Job starts and mounts it read-only. Uploading the same folder again only sends new or changed files. + +```bash +hf jobs uv run --flavor a10g-small --timeout 30m -s HF_TOKEN \ + -v ./my-dog:/data -- \ + https://raw.githubusercontent.com/huggingface/diffusers/main/examples/dreambooth/train_dreambooth_lora_flux2_klein.py \ + --pretrained_model_name_or_path black-forest-labs/FLUX.2-klein-4B \ + --instance_data_dir /data \ + --instance_prompt "a photo of sks dog" \ + --resolution 512 --mixed_precision bf16 --guidance_scale 1 \ + --gradient_checkpointing --cache_latents \ + --optimizer adamW --use_8bit_adam --learning_rate 1e-4 \ + --max_train_steps 20 --seed 0 \ + --output_dir /tmp/out \ + --push_to_hub --hub_model_id your-username/klein-dog-lora +``` + +The script opens every file in `--instance_data_dir` as an image, so keep only images in the folder. A hidden file such as `.DS_Store` makes the run fail. See [Local directories](https://huggingface.co/docs/hub/jobs-configuration#local-directories) for more about mounting a folder. + +With `--with_prior_preservation`, the script generates class images into `--class_data_dir` before training starts. Point it at a path the Job can write to. To reuse the class images in later runs, put them in a read-write bucket mount like the one in [Save checkpoints for long runs](#save-checkpoints-for-long-runs). + +## Train in FP8 + +The FLUX.2, Z-Image, Ideogram 4, and Krea 2 DreamBooth LoRA scripts take `--do_fp8_training` to train in FP8 with [torchao](https://github.com/pytorch/ao), which lowers memory use. No script header includes torchao, so add `--with torchao` before `--`. FP8 also needs a GPU with compute capability 8.9 or higher, such as an L4 (`l4x1`) or L40S (`l40sx1`). The A10G (8.6) and A100 (8.0) don't support it. + +## Run a script without a dependency header + +Only the scripts in [examples/dreambooth](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth) and [examples/advanced_diffusion_training](https://github.com/huggingface/diffusers/tree/main/examples/advanced_diffusion_training) declare their dependencies in a `# /// script` block at the top of the file. Some scripts in those folders, such as `train_dreambooth_lora_sdxl.py`, don't have one. + +For a script without a header, pass each dependency with `--with`. Install Diffusers from source, because the training scripts require the development version. The other dependencies come from the script's `requirements.txt` file and its imports. + +```bash +hf jobs uv run --flavor a10g-small --timeout 30m -s HF_TOKEN \ + --with "diffusers @ git+https://github.com/huggingface/diffusers.git" \ + --with torch --with torchvision --with accelerate --with transformers \ + --with peft --with datasets --with bitsandbytes \ + --with ftfy --with tensorboard --with Jinja2 -- \ + https://raw.githubusercontent.com/huggingface/diffusers/main/examples/dreambooth/train_dreambooth_lora_sdxl.py \ + --pretrained_model_name_or_path stabilityai/stable-diffusion-xl-base-1.0 \ + --pretrained_vae_model_name_or_path madebyollin/sdxl-vae-fp16-fix \ + --dataset_name diffusers/dog-example \ + --instance_prompt "a photo of sks dog" \ + --resolution 1024 --mixed_precision fp16 \ + --gradient_checkpointing --use_8bit_adam --learning_rate 1e-4 \ + --max_train_steps 20 --seed 0 \ + --output_dir /tmp/out \ + --push_to_hub --hub_model_id your-username/sdxl-dog-lora +``` + +## Save checkpoints for long runs + +A run that takes hours can time out or crash before it finishes. To keep its progress, mount a [Storage Bucket](https://huggingface.co/docs/hub/storage-buckets) into the Job with `-v` and point `--output_dir` at it. Create the bucket first with `hf buckets create`. + +The script saves a `checkpoint-` folder to `--output_dir` every `--checkpointing_steps` steps (500 by default), so the checkpoints land in the bucket as training goes. `--checkpoints_total_limit` caps how many are kept. `--resume_from_checkpoint latest` picks up from the newest checkpoint in `--output_dir`, and starts from scratch if there isn't one, so the same command works for the first run and for each restart. + +```bash +hf jobs uv run --flavor a10g-small --timeout 8h -s HF_TOKEN \ + -v hf://buckets/your-username/checkpoints:/ckpt -- \ + https://raw.githubusercontent.com/huggingface/diffusers/main/examples/dreambooth/train_dreambooth_lora_flux2_klein.py \ + --pretrained_model_name_or_path black-forest-labs/FLUX.2-klein-4B \ + --dataset_name diffusers/dog-example \ + --instance_prompt "a photo of sks dog" \ + --resolution 1024 --mixed_precision bf16 --guidance_scale 1 \ + --gradient_checkpointing --cache_latents \ + --optimizer adamW --use_8bit_adam --learning_rate 1e-4 \ + --max_train_steps 5000 --seed 0 \ + --checkpointing_steps 500 --checkpoints_total_limit 3 \ + --resume_from_checkpoint latest \ + --output_dir /ckpt/klein-dog +``` + +When training ends, the LoRA is saved to the bucket as `pytorch_lora_weights.safetensors`. See [Volumes](https://huggingface.co/docs/hub/jobs-configuration#volumes) for the mount options. + +> [!NOTE] +> Don't add `--push_to_hub` when `--output_dir` holds checkpoints. The upload skips only `step_*` and `epoch_*` folders, so the `checkpoint-` folders are pushed to the model repo along with the LoRA. Upload `pytorch_lora_weights.safetensors` to a model repo yourself instead. + +## Next steps + +- Read [Train Models on Jobs](https://huggingface.co/docs/hub/jobs-training) in the Hub docs for the checks to run before a long job and how to read a failed one. +- Load your trained LoRA for inference with the [LoRA](../tutorials/using_peft_for_inference) guide. +- Browse the [DreamBooth README files](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth) for model-specific commands and memory options. diff --git a/docs/source/en/training/kandinsky.md b/docs/source/en/training/kandinsky.md index 89532c556031..3653b4c84b84 100644 --- a/docs/source/en/training/kandinsky.md +++ b/docs/source/en/training/kandinsky.md @@ -17,7 +17,7 @@ specific language governing permissions and limitations under the License. Kandinsky 2.2 is a multilingual text-to-image model capable of producing more photorealistic images. The model includes an image prior model for creating image embeddings from text prompts, and a decoder model that generates images based on the prior model's embeddings. That's why you'll find two separate scripts in Diffusers for Kandinsky 2.2, one for training the prior model and one for training the decoder model. You can train both models separately, but to get the best results, you should train both the prior and decoder models. -Depending on your GPU, you may need to enable `gradient_checkpointing` (⚠️ not supported for the prior model!), `mixed_precision`, and `gradient_accumulation_steps` to help fit the model into memory and to speedup training. You can reduce your memory-usage even more by enabling memory-efficient attention with [xFormers](../optimization/xformers) (version [v0.0.16](https://github.com/huggingface/diffusers/issues/2234#issuecomment-1416931212) fails for training on some GPUs so you may need to install a development version instead). +Depending on your GPU, you may need to enable `gradient_checkpointing` (⚠️ not supported for the prior model!), `mixed_precision`, and `gradient_accumulation_steps` to help fit the model into memory and to speedup training. You can reduce your memory-usage even more by enabling memory-efficient attention with [xFormers](../optimization/attention_backends) (version [v0.0.16](https://github.com/huggingface/diffusers/issues/2234#issuecomment-1416931212) fails for training on some GPUs so you may need to install a development version instead). This guide explores the [train_text_to_image_prior.py](https://github.com/huggingface/diffusers/blob/main/examples/kandinsky2_2/text_to_image/train_text_to_image_prior.py) and the [train_text_to_image_decoder.py](https://github.com/huggingface/diffusers/blob/main/examples/kandinsky2_2/text_to_image/train_text_to_image_decoder.py) scripts to help you become more familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/training/lcm_distill.md b/docs/source/en/training/lcm_distill.md index cfe7d7e2fdce..9bdc3130ac59 100644 --- a/docs/source/en/training/lcm_distill.md +++ b/docs/source/en/training/lcm_distill.md @@ -14,7 +14,7 @@ specific language governing permissions and limitations under the License. [Latent Consistency Models (LCMs)](https://hf.co/papers/2310.04378) are able to generate high-quality images in just a few steps, representing a big leap forward because many pipelines require at least 25+ steps. LCMs are produced by applying the latent consistency distillation method to any Stable Diffusion model. This method works by applying *one-stage guided distillation* to the latent space, and incorporating a *skipping-step* method to consistently skip timesteps to accelerate the distillation process (refer to section 4.1, 4.2, and 4.3 of the paper for more details). -If you're training on a GPU with limited vRAM, try enabling `gradient_checkpointing`, `gradient_accumulation_steps`, and `mixed_precision` to reduce memory-usage and speedup training. You can reduce your memory-usage even more by enabling memory-efficient attention with [xFormers](../optimization/xformers) and [bitsandbytes'](https://github.com/TimDettmers/bitsandbytes) 8-bit optimizer. +If you're training on a GPU with limited vRAM, try enabling `gradient_checkpointing`, `gradient_accumulation_steps`, and `mixed_precision` to reduce memory-usage and speedup training. You can reduce your memory-usage even more by enabling memory-efficient attention with [xFormers](../optimization/attention_backends) and [bitsandbytes'](https://github.com/TimDettmers/bitsandbytes) 8-bit optimizer. This guide will explore the [train_lcm_distill_sd_wds.py](https://github.com/huggingface/diffusers/blob/main/examples/consistency_distillation/train_lcm_distill_sd_wds.py) script to help you become more familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/training/overview.md b/docs/source/en/training/overview.md index ecd7e7780ccf..b33bee8730a5 100644 --- a/docs/source/en/training/overview.md +++ b/docs/source/en/training/overview.md @@ -59,4 +59,4 @@ pip install -r requirements_sdxl.txt To speedup training and reduce memory-usage, we recommend: - using PyTorch 2.0 or higher to automatically use [scaled dot product attention](../optimization/fp16#scaled-dot-product-attention) during training (you don't need to make any changes to the training code) -- installing [xFormers](../optimization/xformers) to enable memory-efficient attention +- installing [xFormers](../optimization/attention_backends) to enable memory-efficient attention diff --git a/docs/source/en/training/sdxl.md b/docs/source/en/training/sdxl.md index cdbea957e2b2..79ee1df9bdca 100644 --- a/docs/source/en/training/sdxl.md +++ b/docs/source/en/training/sdxl.md @@ -17,7 +17,7 @@ specific language governing permissions and limitations under the License. [Stable Diffusion XL (SDXL)](https://hf.co/papers/2307.01952) is a larger and more powerful iteration of the Stable Diffusion model, capable of producing higher resolution images. -SDXL's UNet is 3x larger and the model adds a second text encoder to the architecture. Depending on the hardware available to you, this can be very computationally intensive and it may not run on a consumer GPU like a Tesla T4. To help fit this larger model into memory and to speedup training, try enabling `gradient_checkpointing`, `mixed_precision`, and `gradient_accumulation_steps`. You can reduce your memory-usage even more by enabling memory-efficient attention with [xFormers](../optimization/xformers) and using [bitsandbytes'](https://github.com/TimDettmers/bitsandbytes) 8-bit optimizer. +SDXL's UNet is 3x larger and the model adds a second text encoder to the architecture. Depending on the hardware available to you, this can be very computationally intensive and it may not run on a consumer GPU like a Tesla T4. To help fit this larger model into memory and to speedup training, try enabling `gradient_checkpointing`, `mixed_precision`, and `gradient_accumulation_steps`. You can reduce your memory-usage even more by enabling memory-efficient attention with [xFormers](../optimization/attention_backends) and using [bitsandbytes'](https://github.com/TimDettmers/bitsandbytes) 8-bit optimizer. This guide will explore the [train_text_to_image_sdxl.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_sdxl.py) training script to help you become more familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/training/text2image.md b/docs/source/en/training/text2image.md index 33df598ea16b..00ddd1214168 100644 --- a/docs/source/en/training/text2image.md +++ b/docs/source/en/training/text2image.md @@ -17,7 +17,7 @@ specific language governing permissions and limitations under the License. Text-to-image models like Stable Diffusion are conditioned to generate images given a text prompt. -Training a model can be taxing on your hardware, but if you enable `gradient_checkpointing` and `mixed_precision`, it is possible to train a model on a single 24GB GPU. If you're training with larger batch sizes or want to train faster, it's better to use GPUs with more than 30GB of memory. You can reduce your memory footprint by enabling memory-efficient attention with [xFormers](../optimization/xformers). +Training a model can be taxing on your hardware, but if you enable `gradient_checkpointing` and `mixed_precision`, it is possible to train a model on a single 24GB GPU. If you're training with larger batch sizes or want to train faster, it's better to use GPUs with more than 30GB of memory. You can reduce your memory footprint by enabling memory-efficient attention with [xFormers](../optimization/attention_backends). This guide will explore the [train_text_to_image.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py) training script to help you become familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/training/text_inversion.md b/docs/source/en/training/text_inversion.md index a9116b0a1b61..c1914de57785 100644 --- a/docs/source/en/training/text_inversion.md +++ b/docs/source/en/training/text_inversion.md @@ -16,7 +16,7 @@ specific language governing permissions and limitations under the License. For inference with trained embeddings, see [Textual inversion inference](../using-diffusers/legacy_adapters#textual-inversion). -If you're training on a GPU with limited vRAM, you should try enabling the `gradient_checkpointing` and `mixed_precision` parameters in the training command. You can also reduce your memory footprint by using memory-efficient attention with [xFormers](../optimization/xformers). +If you're training on a GPU with limited vRAM, you should try enabling the `gradient_checkpointing` and `mixed_precision` parameters in the training command. You can also reduce your memory footprint by using memory-efficient attention with [xFormers](../optimization/attention_backends). This guide will explore the [textual_inversion.py](https://github.com/huggingface/diffusers/blob/main/examples/textual_inversion/textual_inversion.py) script to help you become more familiar with it, and how you can adapt it for your own use-case. diff --git a/docs/source/en/using-diffusers/image_quality.md b/docs/source/en/using-diffusers/image_quality.md index 8cbf11ea5388..f7c53c6816bb 100644 --- a/docs/source/en/using-diffusers/image_quality.md +++ b/docs/source/en/using-diffusers/image_quality.md @@ -12,68 +12,14 @@ specific language governing permissions and limitations under the License. # FreeU -[FreeU](https://hf.co/papers/2309.11497) improves image details by rebalancing the UNet's backbone and skip connection weights. The skip connections can cause the model to overlook some of the backbone semantics which may lead to unnatural image details in the generated image. This technique does not require any additional training and can be applied on the fly during inference for tasks like image-to-image and text-to-video. +[FreeU](https://huggingface.co/papers/2309.11497) improves image detail by rebalancing how much the UNet decoder draws from backbone features versus skip-connection features. Skip connections can drown out the backbone's semantic features, which produces unnatural detail in the output. FreeU needs no training, and you can turn it on or off at inference time for text-to-image and text-to-video pipelines. -Use the [`~pipelines.StableDiffusionMixin.enable_freeu`] method on your pipeline and configure the scaling factors for the backbone (`b1` and `b2`) and skip connections (`s1` and `s2`). The number after each scaling factor corresponds to the stage in the UNet where the factor is applied. Take a look at the [FreeU](https://github.com/ChenyangSi/FreeU#parameters) repository for reference hyperparameters for different models. +> [!NOTE] +> FreeU only works with UNet-based pipelines like Stable Diffusion, SDXL, and AnimateDiff. It isn't supported by transformer-based pipelines like Flux or Qwen-Image. - - +Use the [`~pipelines.StableDiffusionMixin.enable_freeu`] method on your pipeline and configure the scaling factors. `b1` and `b2` amplify the backbone features, and `s1` and `s2` dampen the skip features. The `1` and `2` refer to the first two upsampling stages of the UNet decoder. See the [FreeU](https://github.com/ChenyangSi/FreeU#parameters) repository for reference hyperparameters for different models. -```py -import torch -from diffusers import DiffusionPipeline - -pipeline = DiffusionPipeline.from_pretrained( - "stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16, safety_checker=None -).to("cuda") # or "mps", "xpu", "cpu" -pipeline.enable_freeu(s1=0.9, s2=0.2, b1=1.5, b2=1.6) -generator = torch.Generator(device="cpu").manual_seed(33) -prompt = "" -image = pipeline(prompt, generator=generator).images[0] -image -``` - -
-
- -
FreeU disabled
-
-
- -
FreeU enabled
-
-
- -
- - -```py -import torch -from diffusers import DiffusionPipeline - -pipeline = DiffusionPipeline.from_pretrained( - "stabilityai/stable-diffusion-2-1", dtype=torch.float16, safety_checker=None -).to("cuda") # or "mps", "xpu", "cpu" -pipeline.enable_freeu(s1=0.9, s2=0.2, b1=1.4, b2=1.6) -generator = torch.Generator(device="cpu").manual_seed(80) -prompt = "A squirrel eating a burger" -image = pipeline(prompt, generator=generator).images[0] -image -``` - -
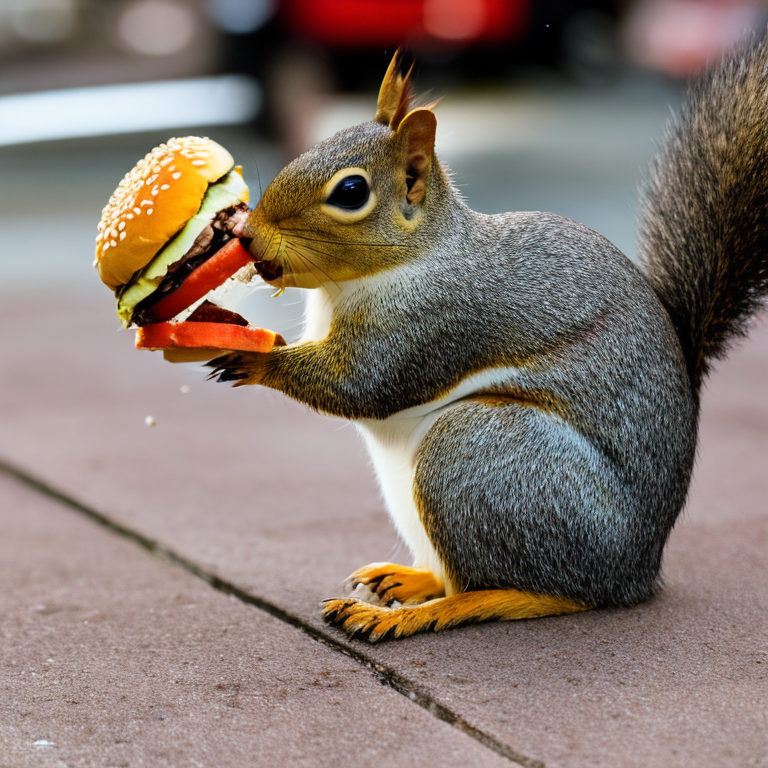
-
- -
FreeU disabled
-
-
- -
FreeU enabled
-
-
- -
- +Start with the repository values for a model. To tune for other models, keep `s1=0.9` and `s2=0.2` and adjust `b1` and `b2` first. Setting all four factors to `1.0` is the same as disabling FreeU. Larger `b` values strengthen the effect but can oversmooth fine texture, and lowering `s1` and `s2` counteracts that. ```py import torch @@ -100,41 +46,13 @@ image - - - -```py -import torch -from diffusers import DiffusionPipeline -from diffusers.utils import export_to_video - -pipeline = DiffusionPipeline.from_pretrained( - "damo-vilab/text-to-video-ms-1.7b", dtype=torch.float16 -).to("cuda") # or "mps", "xpu", "cpu" -# values come from https://github.com/lyn-rgb/FreeU_Diffusers#video-pipelines -pipeline.enable_freeu(b1=1.2, b2=1.4, s1=0.9, s2=0.2) -prompt = "Confident teddy bear surfer rides the wave in the tropics" -generator = torch.Generator(device="cpu").manual_seed(47) -video_frames = pipeline(prompt, generator=generator).frames[0] -export_to_video(video_frames, "teddy_bear.mp4", fps=10) -``` - -
-
- -
FreeU disabled
-
-
- -
FreeU enabled
-
-
- -
-
- Call the [`~pipelines.StableDiffusionMixin.disable_freeu`] method to disable FreeU. ```py pipeline.disable_freeu() ``` + +## Next steps + +- See the [`~pipelines.StableDiffusionMixin.enable_freeu`] API reference for the full parameter descriptions. +- Try FreeU on video with [AnimateDiff](../api/pipelines/animatediff). diff --git a/docs/source/en/using-diffusers/img2img.md b/docs/source/en/using-diffusers/img2img.md index 366be176bd86..e689f6d9fce6 100644 --- a/docs/source/en/using-diffusers/img2img.md +++ b/docs/source/en/using-diffusers/img2img.md @@ -580,7 +580,7 @@ make_image_grid([init_image, depth_image, image_control_net, image_elden_ring], ## Optimize -Running diffusion models is computationally expensive and intensive, but with a few optimization tricks, it is entirely possible to run them on consumer and free-tier GPUs. For example, you can use a more memory-efficient form of attention such as PyTorch 2.0's [scaled-dot product attention](../optimization/fp16#scaled-dot-product-attention) or [xFormers](../optimization/xformers) (you can use one or the other, but there's no need to use both). You can also offload the model to the GPU while the other pipeline components wait on the CPU. +Running diffusion models is computationally expensive and intensive, but with a few optimization tricks, it is entirely possible to run them on consumer and free-tier GPUs. For example, you can use a more memory-efficient form of attention such as PyTorch 2.0's [scaled-dot product attention](../optimization/fp16#scaled-dot-product-attention) or [xFormers](../optimization/attention_backends) (you can use one or the other, but there's no need to use both). You can also offload the model to the GPU while the other pipeline components wait on the CPU. ```diff + pipeline.enable_model_cpu_offload() diff --git a/docs/source/en/using-diffusers/inpaint.md b/docs/source/en/using-diffusers/inpaint.md index b0fb51bcdb89..6d7d174e2bd1 100644 --- a/docs/source/en/using-diffusers/inpaint.md +++ b/docs/source/en/using-diffusers/inpaint.md @@ -782,7 +782,7 @@ make_image_grid([init_image, mask_image, image, image_elden_ring], rows=2, cols= ## Optimize -It can be difficult and slow to run diffusion models if you're resource constrained, but it doesn't have to be with a few optimization tricks. One of the biggest (and easiest) optimizations you can enable is switching to memory-efficient attention. If you're using PyTorch 2.0, [scaled-dot product attention](../optimization/fp16#scaled-dot-product-attention) is automatically enabled and you don't need to do anything else. For non-PyTorch 2.0 users, you can install and use [xFormers](../optimization/xformers)'s implementation of memory-efficient attention. Both options reduce memory usage and accelerate inference. +It can be difficult and slow to run diffusion models if you're resource constrained, but it doesn't have to be with a few optimization tricks. One of the biggest (and easiest) optimizations you can enable is switching to memory-efficient attention. If you're using PyTorch 2.0, [scaled-dot product attention](../optimization/fp16#scaled-dot-product-attention) is automatically enabled and you don't need to do anything else. For non-PyTorch 2.0 users, you can install and use [xFormers](../optimization/attention_backends)'s implementation of memory-efficient attention. Both options reduce memory usage and accelerate inference. You can also offload the model to the CPU to save even more memory: diff --git a/src/diffusers/__init__.py b/src/diffusers/__init__.py index 651592e6e8da..599237a6f2a0 100644 --- a/src/diffusers/__init__.py +++ b/src/diffusers/__init__.py @@ -307,6 +307,10 @@ "JoyImageEditTransformer3DModel", "Kandinsky3UNet", "Kandinsky5Transformer3DModel", + "Kandinsky6SRLatentUpscalerBank", + "Kandinsky6SRTransformer3DModel", + "Kandinsky6SRVAE", + "Kandinsky6Transformer3DModel", "Krea2Transformer2DModel", "LatteTransformer3DModel", "LongCatAudioDiTTransformer", @@ -322,6 +326,8 @@ "MiniMaxMusic3RVQDepthDecoder", "MiniMaxMusic3Transformer1DModel", "MiniMaxMusic3Vocoder", + "MMAudioVAE", + "MMAudioVocoder", "MochiTransformer3DModel", "ModelMixin", "MotifVideoTransformer3DModel", @@ -461,6 +467,7 @@ "LCMScheduler", "LTXEulerAncestralRFScheduler", "MiniMaxH3Scheduler", + "PiflowScheduler", "PNDMScheduler", "RePaintScheduler", "SASolverScheduler", @@ -703,6 +710,10 @@ "Kandinsky5I2VPipeline", "Kandinsky5T2IPipeline", "Kandinsky5T2VPipeline", + "Kandinsky6SRPipeline", + "Kandinsky6SRPipelineOutput", + "Kandinsky6TI2VAPipeline", + "Kandinsky6TI2VAPipelineOutput", "KandinskyCombinedPipeline", "KandinskyImg2ImgCombinedPipeline", "KandinskyImg2ImgPipeline", @@ -1189,6 +1200,10 @@ JoyImageEditTransformer3DModel, Kandinsky3UNet, Kandinsky5Transformer3DModel, + Kandinsky6SRLatentUpscalerBank, + Kandinsky6SRTransformer3DModel, + Kandinsky6SRVAE, + Kandinsky6Transformer3DModel, Krea2Transformer2DModel, LatteTransformer3DModel, LongCatAudioDiTTransformer, @@ -1204,6 +1219,8 @@ MiniMaxMusic3RVQDepthDecoder, MiniMaxMusic3Transformer1DModel, MiniMaxMusic3Vocoder, + MMAudioVAE, + MMAudioVocoder, MochiTransformer3DModel, ModelMixin, MotifVideoTransformer3DModel, @@ -1339,6 +1356,7 @@ LCMScheduler, LTXEulerAncestralRFScheduler, MiniMaxH3Scheduler, + PiflowScheduler, PNDMScheduler, RePaintScheduler, SASolverScheduler, @@ -1560,6 +1578,10 @@ Kandinsky5I2VPipeline, Kandinsky5T2IPipeline, Kandinsky5T2VPipeline, + Kandinsky6SRPipeline, + Kandinsky6SRPipelineOutput, + Kandinsky6TI2VAPipeline, + Kandinsky6TI2VAPipelineOutput, KandinskyCombinedPipeline, KandinskyImg2ImgCombinedPipeline, KandinskyImg2ImgPipeline, diff --git a/src/diffusers/loaders/lora_conversion_utils.py b/src/diffusers/loaders/lora_conversion_utils.py index cef2e88454a8..bfaec3b0b5a7 100644 --- a/src/diffusers/loaders/lora_conversion_utils.py +++ b/src/diffusers/loaders/lora_conversion_utils.py @@ -2736,6 +2736,160 @@ def _convert_to_ai_toolkit_cat(sds_sd, ait_sd, sds_key, ait_keys, dims=None): return ait_sd +def _bake_lokr_alpha_(state_dict): + """ + Consume `.alpha` keys by baking the LyCORIS `alpha / rank` scaling into the left Kronecker factor. The scaling only + applies when a factor is rank-decomposed (`lokr_w1_a/b` or `lokr_w2_a/b`); when both factors are stored as full + matrices, LoKr applies no alpha scaling and the alpha key is simply dropped. + """ + for alpha_key in [k for k in state_dict if k.endswith(".alpha")]: + alpha = state_dict.pop(alpha_key).item() + module = alpha_key.removesuffix(".alpha") + w1_b = state_dict.get(f"{module}.lokr_w1_b") + w2_b = state_dict.get(f"{module}.lokr_w2_b") + rank = w2_b.shape[0] if w2_b is not None else w1_b.shape[0] if w1_b is not None else None + if rank is None: + continue + w1_key = f"{module}.lokr_w1" if f"{module}.lokr_w1" in state_dict else f"{module}.lokr_w1_a" + state_dict[w1_key] = state_dict[w1_key] * (alpha / rank) + + +def _convert_non_diffusers_lokr_to_diffusers(state_dict): + """ + Convert a non-diffusers LoKr state dict whose module paths already match the diffusers model (e.g. ai-toolkit + Z-Image checkpoints with keys like `diffusion_model.layers.0.attention.to_q.lokr_w1`) to the peft-loadable format: + the `diffusion_model.` prefix is replaced with `transformer.` and the `.alpha` keys are consumed. + """ + state_dict = {k.removeprefix("diffusion_model."): v for k, v in state_dict.items()} + _bake_lokr_alpha_(state_dict) + + non_lokr_keys = [k for k in state_dict if ".lokr_" not in k] + if non_lokr_keys: + raise ValueError(f"`state_dict` contains unexpected non-LoKr keys: {non_lokr_keys}.") + + return {f"transformer.{k}": v for k, v in state_dict.items()} + + +_LOKR_SUFFIXES = ("lokr_w1", "lokr_w1_a", "lokr_w1_b", "lokr_w2", "lokr_w2_a", "lokr_w2_b") + + +def _convert_non_diffusers_flux2_lokr_to_diffusers(state_dict): + """ + Convert a BFL-format Flux2 LoKr state dict (e.g. trained with ai-toolkit, keys like + `diffusion_model.double_blocks.0.img_attn.qkv.lokr_w1`) to the peft-loadable diffusers format. + + BFL checkpoints apply LoKr to the fused QKV projections of the double blocks. Unlike a LoRA delta, a Kronecker + product delta over the fused projection cannot be split exactly into separate Q/K/V factors, so these are mapped to + the model's fused `to_qkv`/`to_added_qkv` projections instead; `Flux2LoraLoaderMixin.load_lora_weights` fuses the + model's projections before injecting such an adapter. + """ + original_state_dict = {k.removeprefix("diffusion_model."): v for k, v in state_dict.items()} + _bake_lokr_alpha_(original_state_dict) + + converted_state_dict = {} + + num_double_layers = 0 + num_single_layers = 0 + for key in original_state_dict.keys(): + if key.startswith("single_blocks."): + num_single_layers = max(num_single_layers, int(key.split(".")[1]) + 1) + elif key.startswith("double_blocks."): + num_double_layers = max(num_double_layers, int(key.split(".")[1]) + 1) + + def _remap(bfl_path, diffusers_path): + for suffix in _LOKR_SUFFIXES: + weight = original_state_dict.pop(f"{bfl_path}.{suffix}", None) + if weight is not None: + converted_state_dict[f"{diffusers_path}.{suffix}"] = weight + + for sl in range(num_single_layers): + _remap(f"single_blocks.{sl}.linear1", f"single_transformer_blocks.{sl}.attn.to_qkv_mlp_proj") + _remap(f"single_blocks.{sl}.linear2", f"single_transformer_blocks.{sl}.attn.to_out") + + for dl in range(num_double_layers): + tb = f"transformer_blocks.{dl}" + db = f"double_blocks.{dl}" + + _remap(f"{db}.img_attn.qkv", f"{tb}.attn.to_qkv") + _remap(f"{db}.txt_attn.qkv", f"{tb}.attn.to_added_qkv") + + _remap(f"{db}.img_attn.proj", f"{tb}.attn.to_out.0") + _remap(f"{db}.txt_attn.proj", f"{tb}.attn.to_add_out") + + _remap(f"{db}.img_mlp.0", f"{tb}.ff.linear_in") + _remap(f"{db}.img_mlp.2", f"{tb}.ff.linear_out") + _remap(f"{db}.txt_mlp.0", f"{tb}.ff_context.linear_in") + _remap(f"{db}.txt_mlp.2", f"{tb}.ff_context.linear_out") + + extra_mappings = { + "img_in": "x_embedder", + "txt_in": "context_embedder", + "time_in.in_layer": "time_guidance_embed.timestep_embedder.linear_1", + "time_in.out_layer": "time_guidance_embed.timestep_embedder.linear_2", + "guidance_in.in_layer": "time_guidance_embed.guidance_embedder.linear_1", + "guidance_in.out_layer": "time_guidance_embed.guidance_embedder.linear_2", + "final_layer.linear": "proj_out", + "final_layer.adaLN_modulation.1": "norm_out.linear", + "single_stream_modulation.lin": "single_stream_modulation.linear", + "double_stream_modulation_img.lin": "double_stream_modulation_img.linear", + "double_stream_modulation_txt.lin": "double_stream_modulation_txt.linear", + } + for bfl_key, diffusers_key in extra_mappings.items(): + _remap(bfl_key, diffusers_key) + + if len(original_state_dict) > 0: + raise ValueError(f"`original_state_dict` should be empty at this point but has {original_state_dict.keys()=}.") + + return {f"transformer.{k}": v for k, v in converted_state_dict.items()} + + +# Mapping from LyCORIS underscore-encoded sub-paths to dotted Flux2 module paths. +_LYCORIS_FLUX2_SUBPATH_MAP = { + "attn_to_q": "attn.to_q", + "attn_to_k": "attn.to_k", + "attn_to_v": "attn.to_v", + "attn_to_out_0": "attn.to_out.0", + "attn_to_add_out": "attn.to_add_out", + "attn_add_q_proj": "attn.add_q_proj", + "attn_add_k_proj": "attn.add_k_proj", + "attn_add_v_proj": "attn.add_v_proj", + "attn_to_qkv_mlp_proj": "attn.to_qkv_mlp_proj", + "attn_to_out": "attn.to_out", + "ff_linear_in": "ff.linear_in", + "ff_linear_out": "ff.linear_out", + "ff_context_linear_in": "ff_context.linear_in", + "ff_context_linear_out": "ff_context.linear_out", +} + + +def _convert_lycoris_flux2_lokr_to_diffusers(state_dict): + """ + Convert a LyCORIS-format Flux2 LoKr state dict (keys like `lycoris_transformer_blocks_0_attn_to_q.lokr_w1`) to the + peft-loadable diffusers format. LyCORIS wraps the diffusers model directly and encodes each module path with + underscores, which are decoded through a lookup of the known block sub-paths. + """ + state_dict = dict(state_dict) + _bake_lokr_alpha_(state_dict) + + lycoris_key_pattern = re.compile(r"^lycoris_((?:single_)?transformer_blocks)_(\d+)_(.+)\.(.+)$") + + converted_state_dict = {} + unrecognized_keys = [] + for key, value in state_dict.items(): + match = lycoris_key_pattern.match(key) + diffusers_sub_path = _LYCORIS_FLUX2_SUBPATH_MAP.get(match.group(3)) if match is not None else None + if diffusers_sub_path is None: + unrecognized_keys.append(key) + continue + container, block_idx, _, suffix = match.groups() + converted_state_dict[f"transformer.{container}.{block_idx}.{diffusers_sub_path}.{suffix}"] = value + + if unrecognized_keys: + raise ValueError(f"These keys are not LyCORIS Flux2 LoKr keys: {unrecognized_keys}.") + + return converted_state_dict + + def _convert_non_diffusers_z_image_lora_to_diffusers(state_dict): """ Convert non-diffusers ZImage LoRA state dict to diffusers format. diff --git a/src/diffusers/loaders/lora_pipeline.py b/src/diffusers/loaders/lora_pipeline.py index 1003aa57c420..46867b2257f7 100644 --- a/src/diffusers/loaders/lora_pipeline.py +++ b/src/diffusers/loaders/lora_pipeline.py @@ -45,13 +45,16 @@ _convert_hunyuan_video_lora_to_diffusers, _convert_kohya_flux2_lora_to_diffusers, _convert_kohya_flux_lora_to_diffusers, + _convert_lycoris_flux2_lokr_to_diffusers, _convert_musubi_wan_lora_to_diffusers, _convert_non_diffusers_ace_step_lora_to_diffusers, _convert_non_diffusers_anima_lora_to_diffusers, + _convert_non_diffusers_flux2_lokr_to_diffusers, _convert_non_diffusers_flux2_lora_to_diffusers, _convert_non_diffusers_hidream_lora_to_diffusers, _convert_non_diffusers_ideogram4_lora_to_diffusers, _convert_non_diffusers_krea2_lora_to_diffusers, + _convert_non_diffusers_lokr_to_diffusers, _convert_non_diffusers_lora_to_diffusers, _convert_non_diffusers_ltx2_lora_to_diffusers, _convert_non_diffusers_ltxv_lora_to_diffusers, @@ -5443,14 +5446,19 @@ def lora_state_dict( has_lora_unet = any(k.startswith("lora_unet_") for k in state_dict) has_diffusion_model = any(k.startswith("diffusion_model.") for k in state_dict) has_default = any("default." in k for k in state_dict) - if has_alphas_in_sd or has_lora_unet or has_diffusion_model or has_default: + is_lokr = any(".lokr_" in k for k in state_dict) + if is_lokr: + # ai-toolkit Z-Image LoKr checkpoints store module paths that already match the diffusers model. + if has_diffusion_model or has_alphas_in_sd: + state_dict = _convert_non_diffusers_lokr_to_diffusers(state_dict) + elif has_alphas_in_sd or has_lora_unet or has_diffusion_model or has_default: state_dict = _convert_non_diffusers_z_image_lora_to_diffusers(state_dict) out = (state_dict, metadata) if return_lora_metadata else state_dict return out @require_peft_backend - # Copied from diffusers.loaders.lora_pipeline.CogVideoXLoraLoaderMixin.load_lora_weights + # Copied from diffusers.loaders.lora_pipeline.Flux2LoraLoaderMixin.load_lora_weights def load_lora_weights( self, pretrained_model_name_or_path_or_dict: str | dict[str, torch.Tensor], @@ -5471,9 +5479,9 @@ def load_lora_weights( kwargs["return_lora_metadata"] = True state_dict, metadata = self.lora_state_dict(pretrained_model_name_or_path_or_dict, **kwargs) - is_correct_format = all("lora" in key for key in state_dict.keys()) + is_correct_format = all("lora" in key or "lokr" in key for key in state_dict.keys()) if not is_correct_format: - raise ValueError("Invalid LoRA checkpoint. Make sure all LoRA param names contain `'lora'` substring.") + raise ValueError("Invalid adapter checkpoint. We currently support LoRA and LoKr.") self.load_lora_into_transformer( state_dict, @@ -5831,15 +5839,23 @@ def lora_state_dict( if is_peft_format: state_dict = {k.replace("base_model.model.", "diffusion_model."): v for k, v in state_dict.items()} + is_lokr = any(".lokr_" in k for k in state_dict) is_ai_toolkit = any(k.startswith("diffusion_model.") for k in state_dict) - if is_ai_toolkit: + if is_lokr: + if any(k.startswith("lycoris_") for k in state_dict): + state_dict = _convert_lycoris_flux2_lokr_to_diffusers(state_dict) + elif is_ai_toolkit: + state_dict = _convert_non_diffusers_flux2_lokr_to_diffusers(state_dict) + elif not any(k.startswith("transformer.") for k in state_dict): + # Bare dotted diffusers module paths (e.g. SimpleTuner exports), possibly with alpha keys. + state_dict = _convert_non_diffusers_lokr_to_diffusers(state_dict) + elif is_ai_toolkit: state_dict = _convert_non_diffusers_flux2_lora_to_diffusers(state_dict) out = (state_dict, metadata) if return_lora_metadata else state_dict return out @require_peft_backend - # Copied from diffusers.loaders.lora_pipeline.CogVideoXLoraLoaderMixin.load_lora_weights def load_lora_weights( self, pretrained_model_name_or_path_or_dict: str | dict[str, torch.Tensor], @@ -5860,9 +5876,9 @@ def load_lora_weights( kwargs["return_lora_metadata"] = True state_dict, metadata = self.lora_state_dict(pretrained_model_name_or_path_or_dict, **kwargs) - is_correct_format = all("lora" in key for key in state_dict.keys()) + is_correct_format = all("lora" in key or "lokr" in key for key in state_dict.keys()) if not is_correct_format: - raise ValueError("Invalid LoRA checkpoint. Make sure all LoRA param names contain `'lora'` substring.") + raise ValueError("Invalid adapter checkpoint. We currently support LoRA and LoKr.") self.load_lora_into_transformer( state_dict, diff --git a/src/diffusers/loaders/peft.py b/src/diffusers/loaders/peft.py index 5ab34f4f0a3d..3f0652c979c5 100644 --- a/src/diffusers/loaders/peft.py +++ b/src/diffusers/loaders/peft.py @@ -37,7 +37,12 @@ set_adapter_layers, set_weights_and_activate_adapters, ) -from ..utils.peft_utils import _create_lora_config, _maybe_warn_for_unhandled_keys +from ..utils.peft_utils import ( + _create_lokr_config, + _create_lora_config, + _maybe_fuse_qkv_projections_for_lokr, + _maybe_warn_for_unhandled_keys, +) from .lora_base import _fetch_state_dict, _func_optionally_disable_offloading from .unet_loader_utils import _maybe_expand_lora_scales @@ -217,56 +222,65 @@ def load_lora_adapter( "Please choose an existing adapter name or set `hotswap=False` to prevent hotswapping." ) - # check with first key if is not in peft format - first_key = next(iter(state_dict.keys())) - if "lora_A" not in first_key: - state_dict = convert_unet_state_dict_to_peft(state_dict) - - # Control LoRA from SAI is different from BFL Control LoRA - # https://huggingface.co/stabilityai/control-lora - # https://huggingface.co/comfyanonymous/ControlNet-v1-1_fp16_safetensors - is_sai_sd_control_lora = "lora_controlnet" in state_dict - if is_sai_sd_control_lora: - state_dict = convert_sai_sd_control_lora_state_dict_to_peft(state_dict) - - rank = {} - for key, val in state_dict.items(): - # Cannot figure out rank from lora layers that don't have at least 2 dimensions. - # Bias layers in LoRA only have a single dimension - if "lora_B" in key and val.ndim > 1: - # Check out https://github.com/huggingface/peft/pull/2419 for the `^` symbol. - # We may run into some ambiguous configuration values when a model has module - # names, sharing a common prefix (`proj_out.weight` and `blocks.transformer.proj_out.weight`, - # for example) and they have different LoRA ranks. - rank[f"^{key}"] = val.shape[1] - - if network_alphas is not None and len(network_alphas) >= 1: - alpha_keys = [k for k in network_alphas.keys() if k.startswith(f"{prefix}.")] - network_alphas = { - k.removeprefix(f"{prefix}."): v for k, v in network_alphas.items() if k in alpha_keys - } - - # adapter_name if adapter_name is None: adapter_name = get_adapter_name(self) - # create LoraConfig - lora_config = _create_lora_config( - state_dict, - network_alphas, - metadata, - rank, - model_state_dict=self.state_dict(), - adapter_name=adapter_name, - ) + # LoKr adapters (Kronecker product factors) use a different peft config and state dict layout + # (`{module}.lokr_w1` etc.) than LoRA; detect them before any LoRA-specific key handling. + is_lokr = any(".lokr_" in k for k in state_dict) + + if is_lokr: + if hotswap: + raise ValueError("Hotswapping LoKr adapters is not supported.") + _maybe_fuse_qkv_projections_for_lokr(self, state_dict) + adapter_config = _create_lokr_config(state_dict, metadata) + else: + # check with first key if is not in peft format + first_key = next(iter(state_dict.keys())) + if "lora_A" not in first_key: + state_dict = convert_unet_state_dict_to_peft(state_dict) + + # Control LoRA from SAI is different from BFL Control LoRA + # https://huggingface.co/stabilityai/control-lora + # https://huggingface.co/comfyanonymous/ControlNet-v1-1_fp16_safetensors + is_sai_sd_control_lora = "lora_controlnet" in state_dict + if is_sai_sd_control_lora: + state_dict = convert_sai_sd_control_lora_state_dict_to_peft(state_dict) + + rank = {} + for key, val in state_dict.items(): + # Cannot figure out rank from lora layers that don't have at least 2 dimensions. + # Bias layers in LoRA only have a single dimension + if "lora_B" in key and val.ndim > 1: + # Check out https://github.com/huggingface/peft/pull/2419 for the `^` symbol. + # We may run into some ambiguous configuration values when a model has module + # names, sharing a common prefix (`proj_out.weight` and `blocks.transformer.proj_out.weight`, + # for example) and they have different LoRA ranks. + rank[f"^{key}"] = val.shape[1] + + if network_alphas is not None and len(network_alphas) >= 1: + alpha_keys = [k for k in network_alphas.keys() if k.startswith(f"{prefix}.")] + network_alphas = { + k.removeprefix(f"{prefix}."): v for k, v in network_alphas.items() if k in alpha_keys + } + + # create LoraConfig + adapter_config = _create_lora_config( + state_dict, + network_alphas, + metadata, + rank, + model_state_dict=self.state_dict(), + adapter_name=adapter_name, + ) - # Adjust LoRA config for Control LoRA - if is_sai_sd_control_lora: - lora_config.lora_alpha = lora_config.r - lora_config.alpha_pattern = lora_config.rank_pattern - lora_config.bias = "all" - lora_config.modules_to_save = lora_config.exclude_modules - lora_config.exclude_modules = None + # Adjust LoRA config for Control LoRA + if is_sai_sd_control_lora: + adapter_config.lora_alpha = adapter_config.r + adapter_config.alpha_pattern = adapter_config.rank_pattern + adapter_config.bias = "all" + adapter_config.modules_to_save = adapter_config.exclude_modules + adapter_config.exclude_modules = None # torch.Tensor: + if x.numel() <= CONV_CHUNK_ELEMENTS: + return super().forward(x) + + kernel_size = self.kernel_size[0] + chunks = torch.chunk(x, math.ceil(x.numel() / CONV_CHUNK_ELEMENTS), dim=2) + if kernel_size > 1 and any(chunk.size(2) < kernel_size for chunk in chunks): + # Chunks shorter than the kernel: slide one window at a time instead. + if chunks[0].numel() * (kernel_size / chunks[0].size(2)) >= CONV_CHUNK_ELEMENTS: + raise ValueError("frames are too big for Conv3d") + stride = self.stride[0] + windows = range(0, x.size(2) - kernel_size + 1, stride) + return torch.cat([super().forward(x[:, :, i : i + kernel_size]) for i in windows], dim=2) + + outputs = [] + for i, chunk in enumerate(chunks): + if i == 0 or kernel_size == 1: + carried = chunk + else: + carried = torch.cat([carried[:, :, -kernel_size + 1 :], chunk], dim=2) + outputs.append(super().forward(carried)) + return torch.cat(outputs, dim=2) + + +class Kandinsky6SRCausalConv3d(nn.Module): + """Causal 3D convolution whose temporal padding is carried across segments through a `cache` dict. + + Height and width are zero-padded symmetrically. Along time the first segment is padded by repeating its first frame + `kernel_size - 1` times; later segments are padded with the frames the previous segment left behind in + `cache["padding"]`, so a video processed segment by segment matches a single pass. + + This caching is not an optional performance knob: it is what lets `Kandinsky6SRVAE.encode`/`decode` process an + arbitrarily long video in bounded-memory segments (see `SEGMENT_FRAMES`) while reproducing the exact output of a + single non-causal pass. Without it, each segment would need the raw frames the previous segment already consumed in + order to rebuild correct padding — a lookback window that grows with network depth, rather than the bounded, + constant-size cache this class carries instead — which defeats the point of processing the video in segments. + + `cache` is mutated in place: the caller passes the same dict to every segment, and this class writes the padding it + leaves behind directly into `cache["padding"]` before returning. + """ + + def __init__( + self, + in_channels: int, + out_channels: int, + kernel_size: int | tuple[int, int, int], + stride: tuple[int, int, int] = (1, 1, 1), + ) -> None: + super().__init__() + if not isinstance(kernel_size, tuple): + kernel_size = (kernel_size,) * 3 + time_kernel_size, height_kernel_size, width_kernel_size = kernel_size + if not (height_kernel_size % 2 and width_kernel_size % 2): + raise ValueError( + f"height_kernel_size and width_kernel_size must be odd, got {height_kernel_size} and " + f"{width_kernel_size}" + ) + self.height_pad = height_kernel_size // 2 + self.width_pad = width_kernel_size // 2 + self.time_pad = time_kernel_size - 1 + self.time_kernel_size = time_kernel_size + self.time_stride = stride[0] + self.conv = Kandinsky6SRSafeConv3d(in_channels, out_channels, kernel_size, stride=stride) + + @staticmethod + def make_cache() -> dict: + return {"padding": None} + + def forward(self, hidden_states: torch.Tensor, cache: dict) -> torch.Tensor: + batch_size, _, num_frames, height, width = hidden_states.shape + hidden_states = F.pad(hidden_states, (self.width_pad, self.width_pad, self.height_pad, self.height_pad)) + + if cache["padding"] is None: + first_frame = hidden_states[:, :, :1] + padding = first_frame.expand(-1, -1, self.time_pad, -1, -1) + else: + padding = cache["padding"] + + stride = self.time_stride + output_frames = (num_frames + 1) // 2 if stride == 2 else num_frames + output = torch.empty( + (batch_size, self.conv.out_channels, output_frames, height, width), + dtype=hidden_states.dtype, + device=hidden_states.device, + ) + + # The frames that overlap the carried padding are convolved together with it; the rest run on their own. + offset_out = math.ceil(padding.size(2) / stride) + offset_in = offset_out * stride - padding.size(2) + if offset_out > 0: + padded = torch.cat([padding, hidden_states[:, :, : offset_in + self.time_kernel_size - stride]], dim=2) + output[:, :, :offset_out] = self.conv(padded) + if offset_out < output_frames: + output[:, :, offset_out:] = self.conv(hidden_states[:, :, offset_in:]) + + # The frames the next segment's first window still needs. + pad_offset = ( + offset_in + stride * math.trunc((num_frames - offset_in - self.time_kernel_size) / stride) + stride + ) + if pad_offset < 0: + cache["padding"] = torch.cat([padding[:, :, pad_offset:], hidden_states], dim=2) + else: + cache["padding"] = hidden_states[:, :, pad_offset:].clone() + return output + + +class Kandinsky6VAERMSNorm(nn.Module): + """RMS normalization over the channel axis of a `(B, C, T, H, W)` tensor, computed in float32. + + Same idea as `WanRMS_norm` (`autoencoder_kl_wan.py`) / `QwenImageRMS_norm` (`autoencoder_kl_qwenimage.py`), but not + a verbatim copy of either, so it is not marked `# Copied from`: it is hardcoded to the channel-first 5D layout used + throughout this VAE instead of taking `channel_first`/`images` flags, always upcasts to float32 rather than only + for fp16/bf16/fp8 inputs, and has no learnable bias term. + """ + + def __init__(self, num_channels: int) -> None: + super().__init__() + self.scale = num_channels**0.5 + self.gamma = nn.Parameter(torch.ones(num_channels, 1, 1, 1)) + + def forward(self, hidden_states: torch.Tensor) -> torch.Tensor: + normalized = F.normalize(hidden_states.float(), dim=1).to(hidden_states.dtype) + return normalized * self.scale * self.gamma + + +class Kandinsky6SRSpatialNorm3D(nn.Module): + """Spatial normalization conditioned on the latent `zq` (https://huggingface.co/papers/2209.09002), used here so + the decoder can inject the latent back in at every resnet block. Structurally this plays the same role as + `SpatialNorm` (`attention_processor.py`) / `CogVideoXSpatialNorm3D` (`autoencoder_kl_cogvideox.py`) — normalize the + features, then scale and shift by convolutions of the upsampled `zq`, carrying a `cache` dict across segments the + same way `CogVideoXSpatialNorm3D` threads its `conv_cache` — but it is not a `# Copied from` of either: it + normalizes with `Kandinsky6VAERMSNorm` instead of `GroupNorm` (matching the plain-RMSNorm blocks elsewhere in this + VAE), and interpolates `zq` in channel chunks to bound peak memory. + + `zq` is nearest-upsampled to the feature grid. In the first segment the first frame is upsampled separately, + because the temporal upsampler turns `T + 1` latent frames into `2T + 1` pixel frames. + """ + + def __init__(self, num_channels: int, zq_channels: int) -> None: + super().__init__() + self.norm_layer = Kandinsky6VAERMSNorm(num_channels) + self.conv_y = Kandinsky6SRSafeConv3d(zq_channels, num_channels, kernel_size=1) + self.conv_b = Kandinsky6SRSafeConv3d(zq_channels, num_channels, kernel_size=1) + + @staticmethod + def make_cache() -> dict: + return {"is_first_segment": True} + + def forward(self, hidden_states: torch.Tensor, zq: torch.Tensor, cache: dict) -> torch.Tensor: + if cache["is_first_segment"]: + zq_first = F.interpolate(zq[:, :, :1], size=hidden_states[:, :, :1].shape[-3:], mode="nearest") + if zq.size(2) > 1: + # Interpolate in channel chunks to bound the memory of the upsampled conditioning tensor. + zq_rest = torch.cat( + [ + F.interpolate(split, size=hidden_states[:, :, 1:].shape[-3:], mode="nearest") + for split in torch.split(zq[:, :, 1:], 32, dim=1) + ], + dim=1, + ) + zq = torch.cat([zq_first, zq_rest], dim=2) + else: + zq = zq_first + else: + zq = torch.cat( + [ + F.interpolate(split, size=hidden_states.shape[-3:], mode="nearest") + for split in torch.split(zq, 32, dim=1) + ], + dim=1, + ) + output = self.norm_layer(hidden_states) * self.conv_y(zq) + self.conv_b(zq) + cache["is_first_segment"] = False + return output + + +class Kandinsky6SRResnetBlock3D(nn.Module): + """Causal residual block; decoder blocks modulate their norms with the latent `zq`. + + `conv1`/`conv2` (`Kandinsky6SRCausalConv3d`) and, for decoder blocks, `norm1`/`norm2` (`Kandinsky6SRSpatialNorm3D`) + each mutate the matching key of the `cache` dict this block is given in place. + """ + + def __init__(self, in_channels: int, out_channels: int, zq_channels: int | None = None) -> None: + super().__init__() + self.in_channels = in_channels + self.out_channels = out_channels + if zq_channels is None: + self.norm1 = Kandinsky6VAERMSNorm(in_channels) + self.norm2 = Kandinsky6VAERMSNorm(out_channels) + else: + self.norm1 = Kandinsky6SRSpatialNorm3D(in_channels, zq_channels) + self.norm2 = Kandinsky6SRSpatialNorm3D(out_channels, zq_channels) + self.conv1 = Kandinsky6SRCausalConv3d(in_channels, out_channels, kernel_size=3) + self.conv2 = Kandinsky6SRCausalConv3d(out_channels, out_channels, kernel_size=3) + if in_channels != out_channels: + self.nin_shortcut = Kandinsky6SRSafeConv3d(in_channels, out_channels, kernel_size=1) + + def make_cache(self) -> dict: + cache = {"conv1": self.conv1.make_cache(), "conv2": self.conv2.make_cache()} + if isinstance(self.norm1, Kandinsky6SRSpatialNorm3D): + cache["norm1"] = self.norm1.make_cache() + cache["norm2"] = self.norm2.make_cache() + return cache + + def forward(self, hidden_states: torch.Tensor, cache: dict, zq: torch.Tensor | None = None) -> torch.Tensor: + residual = hidden_states + if zq is None: + hidden_states = self.norm1(hidden_states) + else: + hidden_states = self.norm1(hidden_states, zq, cache["norm1"]) + hidden_states = self.conv1(F.silu(hidden_states), cache["conv1"]) + if zq is None: + hidden_states = self.norm2(hidden_states) + else: + hidden_states = self.norm2(hidden_states, zq, cache["norm2"]) + hidden_states = self.conv2(F.silu(hidden_states), cache["conv2"]) + if self.in_channels != self.out_channels: + residual = self.nin_shortcut(residual) + return residual + hidden_states + + +class Kandinsky6SRDownsample(nn.Module): + """Spatial 2x downsample (strided conv plus pixel-unshuffle average) with an optional causal temporal 2x. + + See `Kandinsky6SRUpsample` for the upsampling counterpart. + """ + + def __init__(self, in_channels: int, compress_time: bool) -> None: + super().__init__() + out_channels = 2 * in_channels + self.compress_time = compress_time + self.unshuffle = nn.PixelUnshuffle(2) + self.spatial_conv = Kandinsky6SRSafeConv3d( + in_channels, out_channels, kernel_size=(1, 3, 3), stride=(1, 2, 2), padding=(0, 1, 1) + ) + if compress_time: + self.temporal_conv = nn.ModuleList( + [ + Kandinsky6SRCausalConv3d(out_channels, out_channels, kernel_size=(2, 1, 1), stride=(1, 1, 1)), + Kandinsky6SRCausalConv3d(out_channels, out_channels, kernel_size=(2, 1, 1), stride=(2, 1, 1)), + ] + ) + self.linear = Kandinsky6SRSafeConv3d(out_channels, out_channels, kernel_size=1) + + def make_cache(self) -> dict: + if not self.compress_time: + return {} + return {"temporal_conv": [conv.make_cache() for conv in self.temporal_conv]} + + def forward(self, hidden_states: torch.Tensor, cache: dict) -> torch.Tensor: + batch_size, channels, num_frames, height, width = hidden_states.shape + + # Spatial: pixel-unshuffle, average pairs of sub-pixel channels, add the strided convolution. + frames = hidden_states.permute(0, 2, 1, 3, 4).reshape(batch_size * num_frames, channels, height, width) + frames = self.unshuffle(frames) + frames = frames.view(batch_size * num_frames, 2 * channels, 2, height // 2, width // 2).mean(dim=2) + frames = frames.view(batch_size, num_frames, 2 * channels, height // 2, width // 2).permute(0, 2, 1, 3, 4) + hidden_states = self.spatial_conv(hidden_states) + frames + + if not self.compress_time: + return self.linear(hidden_states) + + # Temporal: average pairs of frames (the first segment keeps its first frame), add the causal convolutions. + batch_size, channels, num_frames, height, width = hidden_states.shape + sequence = hidden_states.permute(0, 3, 4, 1, 2).reshape(-1, channels, num_frames) + if cache["temporal_conv"][0]["padding"] is None: + first, rest = sequence[..., :1], sequence[..., 1:] + pooled = ( + torch.cat([first, F.avg_pool1d(rest, kernel_size=2, stride=2)], dim=-1) if rest.size(-1) else first + ) + else: + pooled = F.avg_pool1d(sequence, kernel_size=2, stride=2) + pooled = pooled.reshape(batch_size, height, width, channels, -1).permute(0, 3, 4, 1, 2) + + conv_out = self.temporal_conv[0](hidden_states, cache["temporal_conv"][0]) + conv_out = self.temporal_conv[1](conv_out, cache["temporal_conv"][1]) + return self.linear(conv_out + pooled) + + +class Kandinsky6SRUpsample(nn.Module): + """Spatial 2x nearest upsample with a convolutional residual, preceded by an optional causal temporal 2x. + + See `Kandinsky6SRDownsample` for the downsampling counterpart. + """ + + def __init__(self, channels: int, compress_time: bool) -> None: + super().__init__() + self.compress_time = compress_time + self.spatial_conv = Kandinsky6SRSafeConv3d(channels, channels, kernel_size=(1, 3, 3), padding=(0, 1, 1)) + if compress_time: + self.temporal_conv = Kandinsky6SRCausalConv3d(channels, channels, kernel_size=(3, 1, 1)) + self.linear = Kandinsky6SRSafeConv3d(channels, channels, kernel_size=1) + + def make_cache(self) -> dict: + return {"temporal_conv": self.temporal_conv.make_cache()} if self.compress_time else {} + + def forward(self, hidden_states: torch.Tensor, cache: dict) -> torch.Tensor: + if self.compress_time: + # `T + 1` frames become `2T + 1`: every frame is repeated and the first segment drops the extra copy of + # its first frame. + repeated = hidden_states.repeat_interleave(2, dim=2) + if cache["temporal_conv"]["padding"] is None: + repeated = repeated[:, :, 1:] + conv_out = self.temporal_conv(repeated, cache["temporal_conv"]) + hidden_states = conv_out + repeated + + hidden_states = F.interpolate(hidden_states, scale_factor=(1, 2, 2), mode="nearest") + hidden_states = hidden_states + self.spatial_conv(hidden_states) + return self.linear(hidden_states) + + +class Kandinsky6SREncoder3D(nn.Module): + """Causal encoder: `conv_in`, downsampling resnet levels, a resnet bottleneck, then `norm_out`/`conv_out`. + + Each submodule mutates the matching key of the `cache` dict it is given in place. Because the caller + (`Kandinsky6SRVAE.encode`) passes the same `cache` dict to every segment, that in-place mutation is what carries + the padding state from one segment to the next. + """ + + def __init__( + self, + in_channels: int, + latent_channels: int, + block_out_channels: tuple[int, ...], + layers_per_block: int, + temporal_compression_ratio: int, + temporal_compression_start_level: int, + ) -> None: + super().__init__() + num_levels = len(block_out_channels) + temporal_compression_end_level = int(math.log2(temporal_compression_ratio)) + temporal_compression_start_level + + self.conv_in = Kandinsky6SRCausalConv3d(in_channels, block_out_channels[0], kernel_size=3) + self.down = nn.ModuleList() + for level in range(num_levels): + # Every downsample doubles the channel count, so the next level starts at twice the previous width. + block_in = block_out_channels[0] if level == 0 else 2 * block_out_channels[level - 1] + block_out = block_out_channels[level] + blocks = nn.ModuleList() + for _ in range(layers_per_block): + blocks.append(Kandinsky6SRResnetBlock3D(block_in, block_out)) + block_in = block_out + down = nn.Module() + down.block = blocks + if level != num_levels - 1: + compress_time = temporal_compression_start_level <= level < temporal_compression_end_level + down.downsample = Kandinsky6SRDownsample(block_in, compress_time=compress_time) + self.down.append(down) + + self.mid = nn.Module() + self.mid.block_1 = Kandinsky6SRResnetBlock3D(block_in, block_in) + self.mid.block_2 = Kandinsky6SRResnetBlock3D(block_in, block_in) + self.norm_out = Kandinsky6VAERMSNorm(block_in) + self.conv_out = Kandinsky6SRCausalConv3d(block_in, 2 * latent_channels, kernel_size=3) + + def make_cache(self) -> dict: + return { + "conv_in": self.conv_in.make_cache(), + "down": [ + { + "block": [block.make_cache() for block in down.block], + "downsample": down.downsample.make_cache() if hasattr(down, "downsample") else {}, + } + for down in self.down + ], + "mid_1": self.mid.block_1.make_cache(), + "mid_2": self.mid.block_2.make_cache(), + "conv_out": self.conv_out.make_cache(), + } + + def forward(self, hidden_states: torch.Tensor, cache: dict) -> torch.Tensor: + hidden_states = self.conv_in(hidden_states, cache["conv_in"]) + for down, level_cache in zip(self.down, cache["down"]): + for i, block in enumerate(down.block): + hidden_states = block(hidden_states, level_cache["block"][i]) + if hasattr(down, "downsample"): + hidden_states = down.downsample(hidden_states, level_cache["downsample"]) + + hidden_states = self.mid.block_1(hidden_states, cache["mid_1"]) + hidden_states = self.mid.block_2(hidden_states, cache["mid_2"]) + + hidden_states = F.silu(self.norm_out(hidden_states)) + hidden_states = self.conv_out(hidden_states, cache["conv_out"]) + return hidden_states + + +class Kandinsky6SRDecoder3D(nn.Module): + """Causal decoder: `conv_in`, a `zq`-conditioned resnet bottleneck, upsampling resnet levels, then + `norm_out`/`conv_out`. + + Like `Kandinsky6SREncoder3D`, each submodule mutates the matching key of the `cache` dict it is given in place, + which is what carries the padding state across the segments `Kandinsky6SRVAE.decode` passes it. + """ + + def __init__( + self, + out_channels: int, + latent_channels: int, + block_out_channels: tuple[int, ...], + layers_per_block: int, + temporal_compression_ratio: int, + temporal_compression_start_level: int, + ) -> None: + super().__init__() + num_levels = len(block_out_channels) + temporal_compression_end_level = int(math.log2(temporal_compression_ratio)) + temporal_compression_start_level + + block_in = block_out_channels[-1] + self.conv_in = Kandinsky6SRCausalConv3d(latent_channels, block_in, kernel_size=3) + self.mid = nn.Module() + self.mid.block_1 = Kandinsky6SRResnetBlock3D(block_in, block_in, zq_channels=latent_channels) + self.mid.block_2 = Kandinsky6SRResnetBlock3D(block_in, block_in, zq_channels=latent_channels) + + self.up = nn.ModuleList() + for level in reversed(range(num_levels)): + block_out = block_out_channels[level] + blocks = nn.ModuleList() + for _ in range(layers_per_block + 1): + blocks.append(Kandinsky6SRResnetBlock3D(block_in, block_out, zq_channels=latent_channels)) + block_in = block_out + up = nn.Module() + up.block = blocks + if level != 0: + compress_time = ( + num_levels - temporal_compression_start_level + > level + >= num_levels - temporal_compression_end_level + ) + up.upsample = Kandinsky6SRUpsample(block_in, compress_time=compress_time) + self.up.insert(0, up) + + self.norm_out = Kandinsky6SRSpatialNorm3D(block_in, latent_channels) + self.conv_out = Kandinsky6SRCausalConv3d(block_in, out_channels, kernel_size=3) + + def make_cache(self) -> dict: + return { + "conv_in": self.conv_in.make_cache(), + "mid_1": self.mid.block_1.make_cache(), + "mid_2": self.mid.block_2.make_cache(), + "up": [ + { + "block": [block.make_cache() for block in up.block], + "upsample": up.upsample.make_cache() if hasattr(up, "upsample") else {}, + } + for up in self.up + ], + "norm_out": self.norm_out.make_cache(), + "conv_out": self.conv_out.make_cache(), + } + + def forward(self, latents: torch.Tensor, cache: dict) -> torch.Tensor: + hidden_states = self.conv_in(latents, cache["conv_in"]) + + hidden_states = self.mid.block_1(hidden_states, cache["mid_1"], zq=latents) + hidden_states = self.mid.block_2(hidden_states, cache["mid_2"], zq=latents) + + for level in reversed(range(len(self.up))): + up, level_cache = self.up[level], cache["up"][level] + for i, block in enumerate(up.block): + hidden_states = block(hidden_states, level_cache["block"][i], zq=latents) + if hasattr(up, "upsample"): + hidden_states = up.upsample(hidden_states, level_cache["upsample"]) + + hidden_states = self.norm_out(hidden_states, latents, cache["norm_out"]) + hidden_states = F.silu(hidden_states) + hidden_states = self.conv_out(hidden_states, cache["conv_out"]) + return hidden_states + + +class Kandinsky6SRVAE(ModelMixin, ConfigMixin): + r""" + Causal 3D K-VAE used by [`Kandinsky6SRPipeline`] to encode and decode video. + + Videos are processed in temporal segments of 16 pixel frames (plus the leading frame). The causal convolutions + carry their padding state between segments, so the segmentation only bounds peak memory and does not change the + result. + + Args: + in_channels (`int`, defaults to `3`): + Number of pixel channels. + out_channels (`int`, defaults to `3`): + Number of reconstructed pixel channels. + latent_channels (`int`, defaults to `64`): + Number of latent channels. + encoder_block_out_channels (`tuple[int, ...]`, defaults to `(16, 128, 256, 512, 1024)`): + Output width of the residual blocks at each encoder level; every level but the last halves the spatial size + and doubles the width on the way to the next level. + decoder_block_out_channels (`tuple[int, ...]`, defaults to `(16, 256, 512, 1024, 2048)`): + Output width of the residual blocks at each decoder level. + layers_per_block (`int`, defaults to `2`): + Number of residual blocks per encoder level; the decoder uses one more per level. + temporal_compression_ratio (`int`, defaults to `4`): + Temporal compression factor; `log2` of it consecutive levels also compress time. + temporal_compression_start_level (`int`, defaults to `1`): + First level that compresses time. + scaling_factor (`float`, defaults to `0.910344`): + Scale applied to the latents before they enter the diffusion transformer. + """ + + _no_split_modules = ["Kandinsky6SREncoder3D", "Kandinsky6SRDecoder3D"] + + @register_to_config + def __init__( + self, + in_channels: int = 3, + out_channels: int = 3, + latent_channels: int = 64, + encoder_block_out_channels: tuple[int, ...] = (16, 128, 256, 512, 1024), + decoder_block_out_channels: tuple[int, ...] = (16, 256, 512, 1024, 2048), + layers_per_block: int = 2, + temporal_compression_ratio: int = 4, + temporal_compression_start_level: int = 1, + scaling_factor: float = 0.910344004631042, + ) -> None: + super().__init__() + if len(encoder_block_out_channels) != len(decoder_block_out_channels): + raise ValueError("`encoder_block_out_channels` and `decoder_block_out_channels` must have the same length") + + self.encoder = Kandinsky6SREncoder3D( + in_channels=in_channels, + latent_channels=latent_channels, + block_out_channels=encoder_block_out_channels, + layers_per_block=layers_per_block, + temporal_compression_ratio=temporal_compression_ratio, + temporal_compression_start_level=temporal_compression_start_level, + ) + self.decoder = Kandinsky6SRDecoder3D( + out_channels=out_channels, + latent_channels=latent_channels, + block_out_channels=decoder_block_out_channels, + layers_per_block=layers_per_block, + temporal_compression_ratio=temporal_compression_ratio, + temporal_compression_start_level=temporal_compression_start_level, + ) + + self.spatial_compression_ratio = 2 ** (len(encoder_block_out_channels) - 1) + self.temporal_compression_ratio = temporal_compression_ratio + + @apply_forward_hook + def encode(self, x: torch.Tensor, return_dict: bool = True) -> AutoencoderKLOutput | tuple: + r""" + Encode a video into its latent distribution. + + Args: + x (`torch.Tensor` of shape `(batch_size, channels, num_frames, height, width)`): + Pixel video in `[-1, 1]`. `num_frames` should be `1 + k * temporal_compression_ratio`. + return_dict (`bool`, defaults to `True`): + Whether to return an [`~models.modeling_outputs.AutoencoderKLOutput`] instead of a plain tuple. + """ + cache = self.encoder.make_cache() + segment_lengths = [min(SEGMENT_FRAMES + 1, x.size(2))] + remaining = x.size(2) - segment_lengths[0] + while remaining > 0: + segment_lengths.append(min(SEGMENT_FRAMES, remaining)) + remaining -= SEGMENT_FRAMES + + moments = torch.cat( + [self.encoder(segment, cache) for segment in torch.split(x, segment_lengths, dim=2)], dim=2 + ) + posterior = DiagonalGaussianDistribution(moments) + if not return_dict: + return (posterior,) + return AutoencoderKLOutput(latent_dist=posterior) + + @apply_forward_hook + def decode(self, z: torch.Tensor, return_dict: bool = True) -> DecoderOutput | tuple: + r""" + Decode latents into a video. + + Args: + z (`torch.Tensor` of shape `(batch_size, latent_channels, num_latent_frames, height, width)`): + Latents, already divided by `scaling_factor`. + return_dict (`bool`, defaults to `True`): + Whether to return a [`~models.autoencoder_kl.DecoderOutput`] instead of a plain tuple. + """ + cache = self.decoder.make_cache() + latent_segment = SEGMENT_FRAMES // self.temporal_compression_ratio + num_latent_frames = z.size(2) + if num_latent_frames == 1: + segment_lengths = [1] + else: + # The leading latent frame decodes to a single pixel frame; every following latent frame decodes to + # `temporal_compression_ratio` pixel frames. + segment_lengths = [latent_segment] * ((num_latent_frames - 1) // latent_segment) + if (num_latent_frames - 1) % latent_segment: + segment_lengths.append((num_latent_frames - 1) % latent_segment) + segment_lengths[0] += 1 + + decoded = torch.cat( + [self.decoder(segment, cache) for segment in torch.split(z, segment_lengths, dim=2)], dim=2 + ) + if not return_dict: + return (decoded,) + return DecoderOutput(sample=decoded) + + def forward( + self, + sample: torch.Tensor, + sample_posterior: bool = False, + return_dict: bool = True, + generator: torch.Generator | None = None, + ) -> DecoderOutput | tuple: + r""" + Args: + sample (`torch.Tensor` of shape `(batch_size, channels, num_frames, height, width)`): + Pixel video in `[-1, 1]`. `num_frames` should be `1 + k * temporal_compression_ratio`. + sample_posterior (`bool`, *optional*, defaults to `False`): + Whether to sample from the latent posterior instead of using its mode. + return_dict (`bool`, *optional*, defaults to `True`): + Whether to return a [`~models.autoencoder_kl.DecoderOutput`] instead of a plain tuple. + generator (`torch.Generator`, *optional*): + A [`torch.Generator`](https://pytorch.org/docs/stable/generated/torch.Generator.html) to make sampling + deterministic. + + Returns: + [`~models.autoencoder_kl.DecoderOutput`] or `tuple`: + If `return_dict` is True, a [`~models.autoencoder_kl.DecoderOutput`] is returned, otherwise a plain + `tuple` is returned. Its `sample` is the reconstructed video. + """ + posterior = self.encode(sample).latent_dist + z = posterior.sample(generator=generator) if sample_posterior else posterior.mode() + decoded = self.decode(z).sample + if not return_dict: + return (decoded,) + return DecoderOutput(sample=decoded) diff --git a/src/diffusers/models/autoencoders/autoencoder_mmaudio.py b/src/diffusers/models/autoencoders/autoencoder_mmaudio.py new file mode 100644 index 000000000000..c19ad4fd3619 --- /dev/null +++ b/src/diffusers/models/autoencoders/autoencoder_mmaudio.py @@ -0,0 +1,469 @@ +# Copyright 2026 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# Adapted from the MMAudio VAE reference implementation (MIT license, Copyright (c) 2024 Sony Research Inc.): +# https://github.com/hkchengrex/MMAudio/tree/main/mmaudio/ext/autoencoder + +"""MMAudio mel-spectrogram VAE used by the Kandinsky 6 TI2VA pipeline. + +The BigVGAN vocoder that turns this VAE's decoded mel spectrograms into waveforms is a separate component, +[`MMAudioVocoder`]. +""" + +from __future__ import annotations + +import math + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ...configuration_utils import ConfigMixin, register_to_config +from ...utils.accelerate_utils import apply_forward_hook +from ..attention import AttentionModuleMixin +from ..attention_dispatch import AttentionBackendName, dispatch_attention_fn +from ..modeling_outputs import AutoencoderKLOutput +from ..modeling_utils import ModelMixin +from .vae import DecoderOutput, DiagonalGaussianDistribution + + +# Activations of the magnitude-preserving blocks are clipped to this range. +ACTIVATION_CLIP = 256.0 + + +def mel_filterbank(sample_rate: int, n_fft: int, num_mels: int, f_min: float, f_max: float) -> torch.Tensor: + """Slaney-scale mel filterbank of shape `(num_mels, n_fft // 2 + 1)` with Slaney area normalization, the + `librosa.filters.mel` default that the MMAudio front end was trained with.""" + + def hz_to_mel(freq: torch.Tensor) -> torch.Tensor: + linear_step = 200.0 / 3 + min_log_hz = 1000.0 + log_step = math.log(6.4) / 27.0 + return torch.where( + freq >= min_log_hz, min_log_hz / linear_step + torch.log(freq / min_log_hz) / log_step, freq / linear_step + ) + + def mel_to_hz(mel: torch.Tensor) -> torch.Tensor: + linear_step = 200.0 / 3 + min_log_hz = 1000.0 + log_step = math.log(6.4) / 27.0 + min_log_mel = min_log_hz / linear_step + return torch.where( + mel >= min_log_mel, min_log_hz * torch.exp(log_step * (mel - min_log_mel)), linear_step * mel + ) + + fft_freqs = torch.linspace(0, sample_rate / 2, 1 + n_fft // 2, dtype=torch.float32) + mel_limits = hz_to_mel(torch.tensor([f_min, f_max], dtype=torch.float32)) + mel_freqs = mel_to_hz(torch.linspace(mel_limits[0], mel_limits[1], num_mels + 2, dtype=torch.float32)) + freq_diff = torch.diff(mel_freqs) + ramps = mel_freqs[:, None] - fft_freqs[None, :] + lower = -ramps[:-2] / freq_diff[:-1, None] + upper = ramps[2:] / freq_diff[1:, None] + weights = torch.clamp(torch.minimum(lower, upper), min=0) + weights = weights * (2.0 / (mel_freqs[2 : num_mels + 2] - mel_freqs[:num_mels]))[:, None] + return weights.float() + + +# The magnitude-preserving building blocks below follow Karras et al., "Analyzing and Improving the Training +# Dynamics of Diffusion Models" (https://arxiv.org/abs/2312.02696): each layer keeps a unit-variance input +# unit-variance, which MMAudio's VAE relies on instead of normalization layers. + + +def normalize(x: torch.Tensor, dim: list[int] | None = None, eps: float = 1e-4) -> torch.Tensor: + """Rescale `x` to unit L2 norm over `dim` (default: every dimension but the first).""" + if dim is None: + dim = list(range(1, x.ndim)) + norm = torch.linalg.vector_norm(x, dim=dim, keepdim=True, dtype=torch.float32) + norm = eps + norm * math.sqrt(norm.numel() / x.numel()) + return x / norm.to(x.dtype) + + +def mp_silu(x: torch.Tensor) -> torch.Tensor: + """SiLU rescaled so that a unit-variance input stays unit-variance.""" + # 0.596 is the (empirically measured) RMS of SiLU(z) for z ~ N(0, 1), i.e. sqrt(E[SiLU(z)^2]) rather than its + # standard deviation (SiLU(z) has nonzero mean), matching the EDM2 magnitude-preserving convention of keeping + # E[x^2] = 1 rather than mean-subtracted variance = 1 (see Karras et al. reference above). + return F.silu(x) / 0.596 + + +def mp_sum(a: torch.Tensor, b: torch.Tensor, t: float = 0.5) -> torch.Tensor: + """Interpolate `a` and `b` and rescale so that the result stays unit-variance.""" + return a.lerp(b, t) / math.sqrt((1 - t) ** 2 + t**2) + + +class MMAudioMPConv1d(nn.Conv1d): + """Magnitude-preserving 1D convolution with an optional per-call gain. The released weights are already + normalized to unit norm per output channel and scaled by `1 / sqrt(fan_in)`, so the weight is applied directly.""" + + def __init__(self, in_channels: int, out_channels: int, kernel_size: int) -> None: + super().__init__(in_channels, out_channels, kernel_size, padding=kernel_size // 2, bias=False) + + def forward(self, x: torch.Tensor, gain: float | torch.Tensor = 1.0) -> torch.Tensor: + return F.conv1d(x, (self.weight * gain).to(x.dtype), padding=self.padding) + + +class MMAudioResnetBlock1D(nn.Module): + def __init__(self, in_channels: int, out_channels: int, kernel_size: int = 3) -> None: + super().__init__() + self.in_channels = in_channels + self.out_channels = out_channels + self.conv1 = MMAudioMPConv1d(in_channels, out_channels, kernel_size) + self.conv2 = MMAudioMPConv1d(out_channels, out_channels, kernel_size) + if in_channels != out_channels: + self.nin_shortcut = MMAudioMPConv1d(in_channels, out_channels, kernel_size=1) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + x = normalize(x, dim=1) + hidden_states = self.conv1(mp_silu(x)) + hidden_states = self.conv2(mp_silu(hidden_states)) + if self.in_channels != self.out_channels: + x = self.nin_shortcut(x) + return mp_sum(x, hidden_states, t=0.3) + + +class MMAudioAttnProcessor: + """Attention processor used by [`MMAudioAttnBlock1D`].""" + + def __call__(self, attn: "MMAudioAttnBlock1D", x: torch.Tensor) -> torch.Tensor: + batch_size, channels, length = x.shape + qkv = attn.qkv(x).reshape(batch_size, attn.num_heads, -1, 3, length) + query, key, value = normalize(qkv, dim=2).unbind(3) + # `(B, heads, D, T)` -> `(B, T, heads, D)` for the attention dispatcher. `D` is not contiguous after the + # permute (q/k/v are interleaved along the channel dim), which some attention backends (e.g. FlashAttention-3) + # require, so make the tensors contiguous here. + query, key, value = (t.permute(0, 3, 1, 2).contiguous() for t in (query, key, value)) + # This block always attends with a single head over the full channel width (like the SD-VAE `AttnBlock`), + # so `head_dim` can be in the thousands. FlashAttention-family backends cap `head_dim` at 256, so force + # the native SDPA backend here regardless of whatever backend is globally active for the rest of the + # pipeline (e.g. via `transformer.set_attention_backend(...)`). + hidden_states = dispatch_attention_fn(query, key, value, backend=AttentionBackendName.NATIVE) + hidden_states = hidden_states.permute(0, 2, 3, 1).reshape(batch_size, channels, length) + return attn.proj_out(hidden_states) + + +class MMAudioAttnBlock1D(nn.Module, AttentionModuleMixin): + _default_processor_cls = MMAudioAttnProcessor + _available_processors = [MMAudioAttnProcessor] + + def __init__(self, channels: int, num_heads: int = 1, processor: MMAudioAttnProcessor | None = None) -> None: + super().__init__() + self.num_heads = num_heads + self.qkv = MMAudioMPConv1d(channels, channels * 3, kernel_size=1) + self.proj_out = MMAudioMPConv1d(channels, channels, kernel_size=1) + self.set_processor(processor or self._default_processor_cls()) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + return mp_sum(x, self.processor(self, x), t=0.3) + + +class MMAudioUpsample1D(nn.Module): + def __init__(self, channels: int) -> None: + super().__init__() + self.conv = MMAudioMPConv1d(channels, channels, kernel_size=3) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + return self.conv(F.interpolate(x, scale_factor=2.0, mode="nearest-exact")) + + +class MMAudioDownsample1D(nn.Module): + def __init__(self, channels: int) -> None: + super().__init__() + self.conv1 = MMAudioMPConv1d(channels, channels, kernel_size=1) + self.conv2 = MMAudioMPConv1d(channels, channels, kernel_size=1) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + return self.conv2(F.avg_pool1d(self.conv1(x), kernel_size=2, stride=2)) + + +class MMAudioEncoder1D(nn.Module): + """Mel-spectrogram encoder: residual blocks over `channel_multipliers` levels, a single 2x temporal downsample + after the first level, and an attention block in the middle.""" + + def __init__( + self, + mel_bins: int, + latent_channels: int, + hidden_channels: int, + channel_multipliers: tuple[int, ...], + layers_per_block: int, + ) -> None: + super().__init__() + self.conv_in = MMAudioMPConv1d(mel_bins, hidden_channels, kernel_size=3) + + self.down = nn.ModuleList() + block_in = hidden_channels + for level, multiplier in enumerate(channel_multipliers): + block_out = hidden_channels * multiplier + blocks = nn.ModuleList() + for _ in range(layers_per_block): + blocks.append(MMAudioResnetBlock1D(block_in, block_out)) + block_in = block_out + down = nn.Module() + down.block = blocks + if level == 0: + down.downsample = MMAudioDownsample1D(block_in) + self.down.append(down) + + self.mid = nn.Module() + self.mid.block_1 = MMAudioResnetBlock1D(block_in, block_in) + self.mid.attn_1 = MMAudioAttnBlock1D(block_in) + self.mid.block_2 = MMAudioResnetBlock1D(block_in, block_in) + + self.conv_out = MMAudioMPConv1d(block_in, 2 * latent_channels, kernel_size=3) + self.learnable_gain = nn.Parameter(torch.zeros([])) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + hidden_states = self.conv_in(x) + for down in self.down: + for block in down.block: + hidden_states = block(hidden_states).clamp(-ACTIVATION_CLIP, ACTIVATION_CLIP) + if hasattr(down, "downsample"): + hidden_states = down.downsample(hidden_states) + + hidden_states = self.mid.block_1(hidden_states) + hidden_states = self.mid.attn_1(hidden_states) + hidden_states = self.mid.block_2(hidden_states).clamp(-ACTIVATION_CLIP, ACTIVATION_CLIP) + return self.conv_out(mp_silu(hidden_states), gain=self.learnable_gain + 1) + + +class MMAudioDecoder1D(nn.Module): + """Mirror of [`MMAudioEncoder1D`]: the 2x temporal upsample sits after the second-to-last level.""" + + def __init__( + self, + mel_bins: int, + latent_channels: int, + hidden_channels: int, + channel_multipliers: tuple[int, ...], + layers_per_block: int, + ) -> None: + super().__init__() + block_in = hidden_channels * channel_multipliers[-1] + self.conv_in = MMAudioMPConv1d(latent_channels, block_in, kernel_size=3) + + self.mid = nn.Module() + self.mid.block_1 = MMAudioResnetBlock1D(block_in, block_in) + self.mid.attn_1 = MMAudioAttnBlock1D(block_in) + self.mid.block_2 = MMAudioResnetBlock1D(block_in, block_in) + + self.up = nn.ModuleList() + for level in reversed(range(len(channel_multipliers))): + block_out = hidden_channels * channel_multipliers[level] + blocks = nn.ModuleList() + for _ in range(layers_per_block + 1): + blocks.append(MMAudioResnetBlock1D(block_in, block_out)) + block_in = block_out + up = nn.Module() + up.block = blocks + if level == 1: + up.upsample = MMAudioUpsample1D(block_in) + self.up.insert(0, up) + + self.conv_out = MMAudioMPConv1d(block_in, mel_bins, kernel_size=3) + self.learnable_gain = nn.Parameter(torch.zeros([])) + + def forward(self, z: torch.Tensor) -> torch.Tensor: + hidden_states = self.conv_in(z) + hidden_states = self.mid.block_1(hidden_states) + hidden_states = self.mid.attn_1(hidden_states) + hidden_states = self.mid.block_2(hidden_states).clamp(-ACTIVATION_CLIP, ACTIVATION_CLIP) + + for level in reversed(range(len(self.up))): + up = self.up[level] + for block in up.block: + hidden_states = block(hidden_states).clamp(-ACTIVATION_CLIP, ACTIVATION_CLIP) + if hasattr(up, "upsample"): + hidden_states = up.upsample(hidden_states) + return self.conv_out(mp_silu(hidden_states), gain=self.learnable_gain + 1) + + +class MMAudioAutoencoder(nn.Module): + """Encoder/decoder pair over standardized log-mel spectrograms. `data_mean` and `data_std` hold the per-bin + statistics the checkpoint was trained with.""" + + def __init__( + self, + mel_bins: int, + latent_channels: int, + hidden_channels: int, + channel_multipliers: tuple[int, ...], + layers_per_block: int, + ) -> None: + super().__init__() + self.register_buffer("data_mean", torch.zeros(1, mel_bins, 1)) + self.register_buffer("data_std", torch.ones(1, mel_bins, 1)) + self.encoder = MMAudioEncoder1D( + mel_bins, latent_channels, hidden_channels, channel_multipliers, layers_per_block + ) + self.decoder = MMAudioDecoder1D( + mel_bins, latent_channels, hidden_channels, channel_multipliers, layers_per_block + ) + + def encode(self, mel: torch.Tensor) -> torch.Tensor: + return self.encoder((mel - self.data_mean) / self.data_std) + + def decode(self, z: torch.Tensor) -> torch.Tensor: + return self.decoder(z) * self.data_std + self.data_mean + + +class MMAudioMelSpectrogram(nn.Module): + """Log-mel front end of the encoder. The filterbank and window are buffers so they follow the model's device.""" + + def __init__(self, sample_rate: int, n_fft: int, num_mels: int, hop_length: int) -> None: + super().__init__() + self.n_fft = n_fft + self.hop_length = hop_length + self.register_buffer("mel_basis", mel_filterbank(sample_rate, n_fft, num_mels, 0.0, sample_rate / 2)) + self.register_buffer("hann_window", torch.hann_window(n_fft)) + + def forward(self, waveform: torch.Tensor) -> torch.Tensor: + waveform = waveform.clamp(min=-1.0, max=1.0) + padding = (self.n_fft - self.hop_length) // 2 + waveform = F.pad(waveform.unsqueeze(1), (padding, padding), mode="reflect").squeeze(1) + spectrum = torch.stft( + waveform, + self.n_fft, + hop_length=self.hop_length, + win_length=self.n_fft, + window=self.hann_window, + center=False, + pad_mode="reflect", + normalized=False, + onesided=True, + return_complex=True, + ) + magnitude = torch.sqrt(torch.view_as_real(spectrum).pow(2).sum(-1) + 1e-9).float() + return torch.log(torch.clamp(torch.matmul(self.mel_basis, magnitude), min=1e-5)) + + +class MMAudioVAE(ModelMixin, ConfigMixin): + r""" + Audio VAE of [`Kandinsky6TI2VAPipeline`]: a magnitude-preserving autoencoder over log-mel spectrograms (MMAudio, + https://arxiv.org/abs/2412.15322). + + `encode` turns a waveform into a latent distribution; `decode` turns latents back into a mel spectrogram, which + [`MMAudioVocoder`] then turns into a waveform. One latent frame covers `hop_length * 2` samples. + + Args: + mel_bins (`int`, defaults to `128`): + Number of mel bins. + latent_channels (`int`, defaults to `40`): + Number of latent channels. + hidden_channels (`int`, defaults to `512`): + Base width of the autoencoder. + channel_multipliers (`tuple[int, ...]`, defaults to `(1, 2, 4)`): + Width multipliers of the autoencoder levels. + layers_per_block (`int`, defaults to `2`): + Residual blocks per encoder level; the decoder uses one more per level. + sample_rate (`int`, defaults to `44100`): + Waveform sample rate. + n_fft (`int`, defaults to `2048`): + FFT size of the mel front end. + hop_length (`int`, defaults to `512`): + Hop length of the mel front end. Must match the total upsampling factor of the [`MMAudioVocoder`] this VAE + is paired with. + scaling_factor (`float`, defaults to `0.417`): + Scale applied to the latents before they enter the diffusion transformer. + """ + + _no_split_modules = ["MMAudioResnetBlock1D", "MMAudioAttnBlock1D"] + + @register_to_config + def __init__( + self, + mel_bins: int = 128, + latent_channels: int = 40, + hidden_channels: int = 512, + channel_multipliers: tuple[int, ...] = (1, 2, 4), + layers_per_block: int = 2, + sample_rate: int = 44_100, + n_fft: int = 2048, + hop_length: int = 512, + scaling_factor: float = 0.417, + ) -> None: + super().__init__() + self.mel_converter = MMAudioMelSpectrogram(sample_rate, n_fft, mel_bins, hop_length) + self.vae = MMAudioAutoencoder( + mel_bins, latent_channels, hidden_channels, channel_multipliers, layers_per_block + ) + # The encoder downsamples the mel frames once by 2. + self.latent_hop_length = hop_length * 2 + + @apply_forward_hook + def encode(self, audio: torch.Tensor, return_dict: bool = True) -> AutoencoderKLOutput | tuple: + r""" + Encode a waveform into its latent distribution. + + Args: + audio (`torch.Tensor` of shape `(batch_size, num_samples)`): + Mono waveform in `[-1, 1]` at `sample_rate`. + return_dict (`bool`, defaults to `True`): + Whether to return an [`~models.modeling_outputs.AutoencoderKLOutput`] instead of a plain tuple. + """ + mel = self.mel_converter(audio).to(self.dtype) + posterior = DiagonalGaussianDistribution(self.vae.encode(mel)) + if not return_dict: + return (posterior,) + return AutoencoderKLOutput(latent_dist=posterior) + + @apply_forward_hook + def decode(self, z: torch.Tensor, return_dict: bool = True) -> DecoderOutput | tuple: + r""" + Decode latents into a mel spectrogram. + + Args: + z (`torch.Tensor` of shape `(batch_size, latent_channels, num_latent_frames)`): + Latents, already divided by `scaling_factor`. + return_dict (`bool`, defaults to `True`): + Whether to return a [`~models.autoencoder_kl.DecoderOutput`] instead of a plain tuple. + + Returns: + The mel spectrogram of shape `(batch_size, mel_bins, num_mel_frames)`, ready for [`MMAudioVocoder`]. + """ + mel = self.vae.decode(z) + if not return_dict: + return (mel,) + return DecoderOutput(sample=mel) + + def forward( + self, + sample: torch.Tensor, + sample_posterior: bool = False, + return_dict: bool = True, + generator: torch.Generator | None = None, + ) -> DecoderOutput | tuple: + r""" + Args: + sample (`torch.Tensor` of shape `(batch_size, num_samples)`): + Mono waveform in `[-1, 1]` at `sample_rate` to encode and reconstruct as a mel spectrogram. + sample_posterior (`bool`, *optional*, defaults to `False`): + Whether to sample from the latent posterior instead of using its mode. + return_dict (`bool`, *optional*, defaults to `True`): + Whether to return a [`~models.autoencoder_kl.DecoderOutput`] instead of a plain tuple. + generator (`torch.Generator`, *optional*): + A [`torch.Generator`](https://pytorch.org/docs/stable/generated/torch.Generator.html) to make sampling + deterministic. + + Returns: + [`~models.autoencoder_kl.DecoderOutput`] or `tuple`: + If `return_dict` is True, a [`~models.autoencoder_kl.DecoderOutput`] is returned, otherwise a plain + `tuple` is returned. Its `sample` is the reconstructed mel spectrogram of shape `(batch_size, mel_bins, + num_mel_frames)`. + """ + posterior = self.encode(sample).latent_dist + z = posterior.sample(generator=generator) if sample_posterior else posterior.mode() + mel = self.decode(z).sample + if not return_dict: + return (mel,) + return DecoderOutput(sample=mel) diff --git a/src/diffusers/models/autoencoders/mmaudio_vocoder.py b/src/diffusers/models/autoencoders/mmaudio_vocoder.py new file mode 100644 index 000000000000..d1f12fb5ef62 --- /dev/null +++ b/src/diffusers/models/autoencoders/mmaudio_vocoder.py @@ -0,0 +1,233 @@ +# Copyright 2026 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# Adapted from the BigVGAN-v2 vocoder MMAudio bundles at +# https://github.com/hkchengrex/MMAudio/tree/main/mmaudio/ext/bigvgan_v2, itself adapted from +# https://github.com/NVIDIA/BigVGAN (MIT license), with the anti-aliased Snake activations of +# https://github.com/junjun3518/alias-free-torch (Apache License 2.0). + +"""BigVGAN vocoder that turns the mel spectrograms decoded by [`MMAudioVAE`] into waveforms.""" + +from __future__ import annotations + +import math + +import torch +import torch.nn as nn +import torch.nn.functional as F + +from ...configuration_utils import ConfigMixin, register_to_config +from ..modeling_utils import ModelMixin +from .vae import DecoderOutput + + +def kaiser_sinc_filter1d(cutoff: float, half_width: float, kernel_size: int) -> torch.Tensor: + """Kaiser-windowed sinc low-pass filter of shape `(1, 1, kernel_size)` normalized to unit sum.""" + even = kernel_size % 2 == 0 + half_size = kernel_size // 2 + + attenuation = 2.285 * (half_size - 1) * math.pi * 4 * half_width + 7.95 + if attenuation > 50.0: + beta = 0.1102 * (attenuation - 8.7) + elif attenuation >= 21.0: + beta = 0.5842 * (attenuation - 21) ** 0.4 + 0.07886 * (attenuation - 21.0) + else: + beta = 0.0 + window = torch.kaiser_window(kernel_size, beta=beta, periodic=False) + + time = torch.arange(-half_size, half_size) + 0.5 if even else torch.arange(kernel_size) - half_size + filter = 2 * cutoff * window * torch.sinc(2 * cutoff * time) + filter = filter / filter.sum() + return filter.view(1, 1, kernel_size) + + +class MMAudioSnakeBeta(nn.Module): + """`x + 1/b * sin^2(a * x)` with per-channel log-scale frequency `a` and magnitude `b`.""" + + def __init__(self, channels: int) -> None: + super().__init__() + self.alpha = nn.Parameter(torch.zeros(channels)) + self.beta = nn.Parameter(torch.zeros(channels)) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + alpha = torch.exp(self.alpha)[None, :, None] + beta = torch.exp(self.beta)[None, :, None] + return x + (1.0 / (beta + 1e-9)) * torch.sin(x * alpha).pow(2) + + +class MMAudioLowPassFilter1d(nn.Module): + def __init__(self, cutoff: float, half_width: float, stride: int, kernel_size: int) -> None: + super().__init__() + even = kernel_size % 2 == 0 + self.pad_left = kernel_size // 2 - int(even) + self.pad_right = kernel_size // 2 + self.stride = stride + self.register_buffer("filter", kaiser_sinc_filter1d(cutoff, half_width, kernel_size)) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + channels = x.shape[1] + x = F.pad(x, (self.pad_left, self.pad_right), mode="replicate") + return F.conv1d(x, self.filter.expand(channels, -1, -1), stride=self.stride, groups=channels) + + +class MMAudioUpSample1d(nn.Module): + def __init__(self, ratio: int, kernel_size: int) -> None: + super().__init__() + self.ratio = ratio + self.stride = ratio + self.pad = kernel_size // ratio - 1 + self.pad_left = self.pad * self.stride + (kernel_size - self.stride) // 2 + self.pad_right = self.pad * self.stride + (kernel_size - self.stride + 1) // 2 + self.register_buffer("filter", kaiser_sinc_filter1d(0.5 / ratio, 0.6 / ratio, kernel_size)) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + channels = x.shape[1] + x = F.pad(x, (self.pad, self.pad), mode="replicate") + x = self.ratio * F.conv_transpose1d( + x, self.filter.expand(channels, -1, -1), stride=self.stride, groups=channels + ) + return x[..., self.pad_left : -self.pad_right] + + +class MMAudioDownSample1d(nn.Module): + def __init__(self, ratio: int, kernel_size: int) -> None: + super().__init__() + self.lowpass = MMAudioLowPassFilter1d(0.5 / ratio, 0.6 / ratio, stride=ratio, kernel_size=kernel_size) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + return self.lowpass(x) + + +class MMAudioActivation1d(nn.Module): + """Anti-aliased activation: 2x upsample, Snake-beta, 2x downsample.""" + + def __init__(self, channels: int, ratio: int = 2, kernel_size: int = 12) -> None: + super().__init__() + self.act = MMAudioSnakeBeta(channels) + self.upsample = MMAudioUpSample1d(ratio, kernel_size) + self.downsample = MMAudioDownSample1d(ratio, kernel_size) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + return self.downsample(self.act(self.upsample(x))) + + +class MMAudioAMPBlock(nn.Module): + """Anti-aliased multi-periodicity block: dilated convolutions each followed by a dilation-1 convolution.""" + + def __init__(self, channels: int, kernel_size: int, dilations: tuple[int, ...]) -> None: + super().__init__() + self.convs1 = nn.ModuleList( + [ + nn.Conv1d( + channels, + channels, + kernel_size, + dilation=dilation, + padding=(kernel_size * dilation - dilation) // 2, + ) + for dilation in dilations + ] + ) + self.convs2 = nn.ModuleList( + [nn.Conv1d(channels, channels, kernel_size, padding=(kernel_size - 1) // 2) for _ in dilations] + ) + self.activations = nn.ModuleList([MMAudioActivation1d(channels) for _ in range(2 * len(dilations))]) + + def forward(self, x: torch.Tensor) -> torch.Tensor: + activations_1, activations_2 = self.activations[::2], self.activations[1::2] + for conv1, conv2, act1, act2 in zip(self.convs1, self.convs2, activations_1, activations_2): + x = conv2(act2(conv1(act1(x)))) + x + return x + + +class MMAudioVocoder(ModelMixin, ConfigMixin): + r""" + BigVGAN-v2 vocoder (https://github.com/NVIDIA/BigVGAN, MIT license) with the anti-aliased Snake activations of + https://github.com/junjun3518/alias-free-torch (Apache 2.0), turning the mel spectrograms [`MMAudioVAE`] decodes + into waveforms for [`Kandinsky6TI2VAPipeline`]. + + Args: + num_mels (`int`, defaults to `128`): + Number of mel bins of the input spectrogram. Must match the paired [`MMAudioVAE`]'s `mel_bins`. + upsample_initial_channel (`int`, defaults to `1536`): + Width of the first layer. + upsample_rates (`tuple[int, ...]`, defaults to `(8, 4, 2, 2, 2, 2)`): + Upsampling factors of the vocoder stages. Their product is the total upsampling factor and must match the + paired [`MMAudioVAE`]'s `hop_length`. + upsample_kernel_sizes (`tuple[int, ...]`, defaults to `(16, 8, 4, 4, 4, 4)`): + Transposed-convolution kernel sizes of the vocoder stages. + resblock_kernel_sizes (`tuple[int, ...]`, defaults to `(3, 7, 11)`): + Kernel sizes of the residual blocks. + resblock_dilation_sizes (`tuple[tuple[int, ...], ...]`, defaults to `((1, 3, 5), (1, 3, 5), (1, 3, 5))`): + Dilations of the residual blocks. + """ + + _no_split_modules = ["MMAudioAMPBlock"] + + @register_to_config + def __init__( + self, + num_mels: int = 128, + upsample_initial_channel: int = 1536, + upsample_rates: tuple[int, ...] = (8, 4, 2, 2, 2, 2), + upsample_kernel_sizes: tuple[int, ...] = (16, 8, 4, 4, 4, 4), + resblock_kernel_sizes: tuple[int, ...] = (3, 7, 11), + resblock_dilation_sizes: tuple[tuple[int, ...], ...] = ((1, 3, 5), (1, 3, 5), (1, 3, 5)), + ) -> None: + super().__init__() + if len(upsample_rates) != len(upsample_kernel_sizes): + raise ValueError("`upsample_rates` and `upsample_kernel_sizes` must have the same length") + if len(resblock_kernel_sizes) != len(resblock_dilation_sizes): + raise ValueError("`resblock_kernel_sizes` and `resblock_dilation_sizes` must have the same length") + + self.num_kernels = len(resblock_kernel_sizes) + self.conv_pre = nn.Conv1d(num_mels, upsample_initial_channel, 7, padding=3) + + self.ups = nn.ModuleList() + self.resblocks = nn.ModuleList() + channels = upsample_initial_channel + for rate, kernel_size in zip(upsample_rates, upsample_kernel_sizes): + self.ups.append( + nn.ModuleList( + [nn.ConvTranspose1d(channels, channels // 2, kernel_size, rate, padding=(kernel_size - rate) // 2)] + ) + ) + channels //= 2 + for block_kernel_size, dilations in zip(resblock_kernel_sizes, resblock_dilation_sizes): + self.resblocks.append(MMAudioAMPBlock(channels, block_kernel_size, tuple(dilations))) + + self.activation_post = MMAudioActivation1d(channels) + self.conv_post = nn.Conv1d(channels, 1, 7, padding=3, bias=False) + + def forward(self, mel: torch.Tensor, return_dict: bool = True) -> DecoderOutput | tuple: + r""" + Args: + mel (`torch.Tensor` of shape `(batch_size, num_mels, num_mel_frames)`): + Mel spectrogram, as decoded by [`MMAudioVAE`]. + return_dict (`bool`, defaults to `True`): + Whether to return a [`~models.autoencoder_kl.DecoderOutput`] instead of a plain tuple. + + Returns: + The waveform of shape `(batch_size, 1, num_samples)` in `[-1, 1]`. + """ + hidden_states = self.conv_pre(mel) + for stage, up in enumerate(self.ups): + hidden_states = up[0](hidden_states) + blocks = self.resblocks[stage * self.num_kernels : (stage + 1) * self.num_kernels] + hidden_states = sum(block(hidden_states) for block in blocks) / self.num_kernels + hidden_states = self.conv_post(self.activation_post(hidden_states)) + waveform = torch.clamp(hidden_states, min=-1.0, max=1.0) + if not return_dict: + return (waveform,) + return DecoderOutput(sample=waveform) diff --git a/src/diffusers/models/latent_upscaler/__init__.py b/src/diffusers/models/latent_upscaler/__init__.py new file mode 100644 index 000000000000..1c3f83192f85 --- /dev/null +++ b/src/diffusers/models/latent_upscaler/__init__.py @@ -0,0 +1,5 @@ +from ...utils import is_torch_available + + +if is_torch_available(): + from .latent_upscaler_kandinsky6_sr import Kandinsky6SRLatentUpscalerBank diff --git a/src/diffusers/models/latent_upscaler/latent_upscaler_kandinsky6_sr.py b/src/diffusers/models/latent_upscaler/latent_upscaler_kandinsky6_sr.py new file mode 100644 index 000000000000..630c6edd488b --- /dev/null +++ b/src/diffusers/models/latent_upscaler/latent_upscaler_kandinsky6_sr.py @@ -0,0 +1,323 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""Latent upscalers used by the Kandinsky 6 video super-resolution pipeline.""" + +from __future__ import annotations + +import torch +from torch import Tensor, nn +from torch.nn import functional + +from ...configuration_utils import ConfigMixin, register_to_config +from ..autoencoders.vae import DecoderOutput +from ..modeling_utils import ModelMixin + + +class Kandinsky6SRLatentUpscalerConv3d(nn.Conv3d): + """`Conv3d` that replicates the edge frame along time and zero-pads height and width, matching the K-VAE + latents this model operates on: repeating the boundary frame avoids a zero "hole" next to frame 0, which already + encodes a single pixel frame while every later latent frame aggregates several. + """ + + def __init__(self, in_channels: int, out_channels: int, kernel_size: int) -> None: + super().__init__(in_channels, out_channels, kernel_size, padding=(0, kernel_size // 2, kernel_size // 2)) + self.temporal_pad = kernel_size // 2 + + def forward(self, hidden_states: Tensor) -> Tensor: + hidden_states = functional.pad( + hidden_states, (0, 0, 0, 0, self.temporal_pad, self.temporal_pad), mode="replicate" + ) + return super().forward(hidden_states) + + +class Kandinsky6SRLatentUpscalerRMSNorm(nn.Module): + """Channel-first RMS normalization with a learnable gain, computed in float32.""" + + def __init__(self, num_channels: int) -> None: + super().__init__() + self.scale = num_channels**0.5 + self.gamma = nn.Parameter(torch.ones(num_channels, 1, 1, 1)) + + def forward(self, hidden_states: Tensor) -> Tensor: + normalized = functional.normalize(hidden_states.float(), dim=1).to(hidden_states.dtype) + return normalized * self.scale * self.gamma + + +class Kandinsky6SRLatentUpscalerModulatedNorm(nn.Module): + """RMS norm followed by a FiLM modulation computed from the input latent `zq`, nearest-upsampled to the feature + grid so the same conditioning serves every resolution of the cascade.""" + + def __init__(self, num_channels: int, zq_channels: int) -> None: + super().__init__() + self.norm = Kandinsky6SRLatentUpscalerRMSNorm(num_channels) + self.conv_y = nn.Conv3d(zq_channels, num_channels, kernel_size=1) + self.conv_b = nn.Conv3d(zq_channels, num_channels, kernel_size=1) + + def forward(self, hidden_states: Tensor, zq: Tensor) -> Tensor: + if zq.shape[2:] != hidden_states.shape[2:]: + zq = functional.interpolate(zq, size=hidden_states.shape[2:], mode="nearest") + return self.norm(hidden_states) * self.conv_y(zq) + self.conv_b(zq) + + +class Kandinsky6SRLatentUpscalerResidualBlock(nn.Module): + """Pre-activation residual block: `norm -> SiLU -> conv3x3x3 -> norm -> SiLU -> conv3x3x3`, with a 1x1 shortcut + when the width changes.""" + + def __init__(self, in_channels: int, out_channels: int, zq_channels: int) -> None: + super().__init__() + self.norm1 = Kandinsky6SRLatentUpscalerModulatedNorm(in_channels, zq_channels) + self.conv1 = Kandinsky6SRLatentUpscalerConv3d(in_channels, out_channels, kernel_size=3) + self.norm2 = Kandinsky6SRLatentUpscalerModulatedNorm(out_channels, zq_channels) + self.conv2 = Kandinsky6SRLatentUpscalerConv3d(out_channels, out_channels, kernel_size=3) + self.shortcut = ( + nn.Identity() if in_channels == out_channels else nn.Conv3d(in_channels, out_channels, kernel_size=1) + ) + + def forward(self, hidden_states: Tensor, zq: Tensor) -> Tensor: + residual = self.conv1(functional.silu(self.norm1(hidden_states, zq))) + residual = self.conv2(functional.silu(self.norm2(residual, zq))) + return self.shortcut(hidden_states) + residual + + +class Kandinsky6SRLatentUpscalerUpsample(nn.Module): + """Spatial 2x: nearest upsample plus a per-frame convolutional residual, mixed by a pointwise convolution.""" + + def __init__(self, channels: int) -> None: + super().__init__() + self.spatial_conv = nn.Conv3d(channels, channels, kernel_size=(1, 3, 3), padding=(0, 1, 1)) + self.linear = nn.Conv3d(channels, channels, kernel_size=1) + + def forward(self, hidden_states: Tensor) -> Tensor: + hidden_states = functional.interpolate(hidden_states, scale_factor=(1, 2, 2), mode="nearest") + return self.linear(hidden_states + self.spatial_conv(hidden_states)) + + +class Kandinsky6SRLatentUpscalerOutputHead(nn.Module): + """`modulated norm -> SiLU -> conv3x3x3` projection back to the latent channels, threading `zq` into the norm.""" + + def __init__(self, in_channels: int, out_channels: int, zq_channels: int) -> None: + super().__init__() + self.norm = Kandinsky6SRLatentUpscalerModulatedNorm(in_channels, zq_channels) + self.activation = nn.SiLU() + self.conv = Kandinsky6SRLatentUpscalerConv3d(in_channels, out_channels, kernel_size=3) + + def forward(self, hidden_states: Tensor, zq: Tensor) -> Tensor: + return self.conv(self.activation(self.norm(hidden_states, zq))) + + +class Kandinsky6SRLatentUpscalerX2Branch(nn.Module): + """The x2 upscaler tail: adapter blocks and a finisher on the input grid, then one 2x stage.""" + + def __init__( + self, + in_channels: int, + stage_channels: tuple[int, int, int], + num_adapter_blocks: int, + num_mid_blocks: int, + num_post_blocks: int, + ) -> None: + super().__init__() + width_1, width_2, width_3 = stage_channels + self.adapter = nn.ModuleList( + [Kandinsky6SRLatentUpscalerResidualBlock(width_1, width_1, in_channels) for _ in range(num_adapter_blocks)] + ) + self.finisher = nn.Module() + self.finisher.spatial_conv = nn.Conv3d(width_1, width_1, kernel_size=(1, 3, 3), padding=(0, 1, 1)) + self.finisher.linear = nn.Conv3d(width_1, width_1, kernel_size=1) + mid_widths = [width_1] + [width_2] * num_mid_blocks + self.mid_blocks = nn.ModuleList( + [ + Kandinsky6SRLatentUpscalerResidualBlock(mid_widths[index], mid_widths[index + 1], in_channels) + for index in range(num_mid_blocks) + ] + ) + self.upsample = Kandinsky6SRLatentUpscalerUpsample(width_2) + post_widths = [width_2] + [width_3] * num_post_blocks + self.blocks = nn.ModuleList( + [ + Kandinsky6SRLatentUpscalerResidualBlock(post_widths[index], post_widths[index + 1], in_channels) + for index in range(num_post_blocks) + ] + ) + self.output_proj = Kandinsky6SRLatentUpscalerOutputHead(width_3, in_channels, in_channels) + + def forward(self, hidden_states: Tensor, zq: Tensor) -> Tensor: + for block in self.adapter: + hidden_states = block(hidden_states, zq) + hidden_states = self.finisher.linear(hidden_states + self.finisher.spatial_conv(hidden_states)) + for block in self.mid_blocks: + hidden_states = block(hidden_states, zq) + hidden_states = self.upsample(hidden_states) + for block in self.blocks: + hidden_states = block(hidden_states, zq) + return self.output_proj(hidden_states, zq) + + +class Kandinsky6SRLatentUpscaler(nn.Module): + """One latent upscaler of the bank: a two-stage 2x+2x cascade for `scale=4`, or its single-stage x2 variant. + + Both share the same widths and the same `input_proj -> pre_blocks -> upsample_1 -> mid_blocks -> upsample_2 -> + post_blocks -> output_proj` backbone (plus an auxiliary `mid_output_head`, a deep-supervision head the checkpoint + trains with zero loss weight -- see below). The x2 model additionally runs the + [`Kandinsky6SRLatentUpscalerX2Branch`] tail; the x4 model's `forward` is just its backbone. + + Released checkpoints train the x2 entry's backbone jointly with its [`Kandinsky6SRLatentUpscalerX2Branch`] tail + (the `x2_adapter_sources` config field names which backbone activations the tail's `adapter` reads from), but + `forward` here only runs the tail, matching this class's behavior before the backbone was known to exist: the + backbone and `mid_output_head` are declared so their trained weights load from the checkpoint instead of raising + "unused weights"/leaving parameters meta/randomly-initialized, but neither is wired into `forward`, so numerically + this is unchanged from before. Wiring the backbone into the x2 tail's forward pass needs the original training code + to confirm the exact tap points first -- guessing would risk silently wrong output. + """ + + def __init__( + self, + scale: int, + in_channels: int, + stage_channels: tuple[int, int, int], + num_pre_blocks: int, + num_mid_blocks: int, + num_post_blocks: int, + num_x2_adapter_blocks: int, + ) -> None: + super().__init__() + if scale not in (2, 4): + raise ValueError(f"`scale` must be 2 or 4, got {scale}") + self.scale = scale + width_1, width_2, width_3 = stage_channels + + self.input_proj = nn.Sequential(Kandinsky6SRLatentUpscalerConv3d(in_channels, width_1, kernel_size=3)) + self.pre_blocks = nn.ModuleList( + [Kandinsky6SRLatentUpscalerResidualBlock(width_1, width_1, in_channels) for _ in range(num_pre_blocks)] + ) + self.upsample_1 = Kandinsky6SRLatentUpscalerUpsample(width_1) + mid_widths = [width_1] + [width_2] * num_mid_blocks + self.mid_blocks = nn.ModuleList( + [ + Kandinsky6SRLatentUpscalerResidualBlock(mid_widths[index], mid_widths[index + 1], in_channels) + for index in range(num_mid_blocks) + ] + ) + self.mid_output_head = nn.Sequential( + Kandinsky6SRLatentUpscalerRMSNorm(width_2), + nn.SiLU(), + Kandinsky6SRLatentUpscalerConv3d(width_2, in_channels, kernel_size=3), + ) + self.upsample_2 = Kandinsky6SRLatentUpscalerUpsample(width_2) + post_widths = [width_2] + [width_3] * num_post_blocks + self.post_blocks = nn.ModuleList( + [ + Kandinsky6SRLatentUpscalerResidualBlock(post_widths[index], post_widths[index + 1], in_channels) + for index in range(num_post_blocks) + ] + ) + self.output_proj = Kandinsky6SRLatentUpscalerOutputHead(width_3, in_channels, in_channels) + + if scale == 2: + self.mid_input_proj = nn.Sequential(Kandinsky6SRLatentUpscalerConv3d(in_channels, width_1, kernel_size=3)) + self.x2_branch = Kandinsky6SRLatentUpscalerX2Branch( + in_channels, stage_channels, num_x2_adapter_blocks, num_mid_blocks, num_post_blocks + ) + + def forward(self, latents: Tensor) -> Tensor: + zq = latents + if self.scale == 2: + return self.x2_branch(self.mid_input_proj(latents), zq) + + hidden_states = self.input_proj(latents) + for block in self.pre_blocks: + hidden_states = block(hidden_states, zq) + hidden_states = self.upsample_1(hidden_states) + for block in self.mid_blocks: + hidden_states = block(hidden_states, zq) + hidden_states = self.upsample_2(hidden_states) + for block in self.post_blocks: + hidden_states = block(hidden_states, zq) + return self.output_proj(hidden_states, zq) + + +class Kandinsky6SRLatentUpscalerBank(ModelMixin, ConfigMixin): + r""" + Bank of latent upscalers used by [`Kandinsky6SRPipeline`]: one [`Kandinsky6SRLatentUpscaler`] per supported spatial + scale, operating on K-VAE latents. + + Args: + in_channels (`int`, defaults to `64`): + Number of latent channels. + stage_channels (`tuple[int, int, int]`, defaults to `(2048, 1024, 512)`): + Feature widths of the three stages of the cascade. + num_pre_blocks (`int`, defaults to `5`): + Residual blocks before the first upsample of the x4 model. + num_mid_blocks (`int`, defaults to `3`): + Residual blocks between the two upsamples. + num_post_blocks (`int`, defaults to `3`): + Residual blocks after the last upsample. + num_x2_adapter_blocks (`int`, defaults to `2`): + Residual blocks of the x2 model's adapter. + scales (`tuple[int, ...]`, defaults to `(2, 4)`): + Spatial scales the bank provides an upscaler for. + scaling_factor (`float`, defaults to `0.910344`): + Scale the input latents are expected to carry (the K-VAE `scaling_factor`). + """ + + _no_split_modules = ["Kandinsky6SRLatentUpscaler"] + + @register_to_config + def __init__( + self, + in_channels: int = 64, + stage_channels: tuple[int, int, int] = (2048, 1024, 512), + num_pre_blocks: int = 5, + num_mid_blocks: int = 3, + num_post_blocks: int = 3, + num_x2_adapter_blocks: int = 2, + scales: tuple[int, ...] = (2, 4), + scaling_factor: float = 0.910344004631042, + ) -> None: + super().__init__() + self._models = nn.ModuleList( + [ + Kandinsky6SRLatentUpscaler( + scale=scale, + in_channels=in_channels, + stage_channels=stage_channels, + num_pre_blocks=num_pre_blocks, + num_mid_blocks=num_mid_blocks, + num_post_blocks=num_post_blocks, + num_x2_adapter_blocks=num_x2_adapter_blocks, + ) + for scale in scales + ] + ) + + def forward(self, latents: Tensor, scale: int, return_dict: bool = True) -> DecoderOutput | tuple[Tensor]: + r""" + Args: + latents (`torch.Tensor` of shape `(batch_size, in_channels, num_frames, height, width)`): + K-VAE latents scaled by `scaling_factor`. + scale (`int`): + Spatial upscale factor; one of `scales`. + return_dict (`bool`, defaults to `True`): + Whether to return a [`~models.autoencoder_kl.DecoderOutput`] instead of a plain tuple. + + Returns: + The upscaled latents of shape `(batch_size, in_channels, num_frames, height * scale, width * scale)`. + """ + if scale not in self.config.scales: + raise ValueError(f"No latent upscaler for scale {scale}; available scales: {list(self.config.scales)}") + upscaled = self._models[self.config.scales.index(scale)](latents) + if not return_dict: + return (upscaled,) + return DecoderOutput(sample=upscaled) diff --git a/src/diffusers/models/transformers/__init__.py b/src/diffusers/models/transformers/__init__.py index ffb0cbc0318b..d29d49d16857 100755 --- a/src/diffusers/models/transformers/__init__.py +++ b/src/diffusers/models/transformers/__init__.py @@ -45,6 +45,8 @@ from .transformer_joyimage import JoyImageEditTransformer3DModel from .transformer_joyimage_edit_plus import JoyImageEditPlusTransformer3DModel from .transformer_kandinsky import Kandinsky5Transformer3DModel + from .transformer_kandinsky6 import Kandinsky6Transformer3DModel + from .transformer_kandinsky6_sr import Kandinsky6SRTransformer3DModel from .transformer_krea2 import Krea2Transformer2DModel from .transformer_longcat_audio_dit import LongCatAudioDiTTransformer from .transformer_longcat_image import LongCatImageTransformer2DModel diff --git a/src/diffusers/models/transformers/transformer_kandinsky6.py b/src/diffusers/models/transformers/transformer_kandinsky6.py new file mode 100644 index 000000000000..3acfd8afe484 --- /dev/null +++ b/src/diffusers/models/transformers/transformer_kandinsky6.py @@ -0,0 +1,844 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""Kandinsky 6 Diffusers transformer.""" + +from __future__ import annotations + +import math +from dataclasses import dataclass +from typing import Any + +import torch +from torch import Tensor, nn + +from ...configuration_utils import ConfigMixin, register_to_config +from ...loaders import PeftAdapterMixin +from ...utils import BaseOutput +from ..attention import AttentionMixin, AttentionModuleMixin, FeedForward +from ..attention_dispatch import dispatch_attention_fn +from ..cache_utils import CacheMixin +from ..embeddings import TimestepEmbedding, Timesteps +from ..modeling_utils import ModelMixin, get_parameter_dtype + + +@dataclass +class Kandinsky6TransformerOutput(BaseOutput): + r""" + The output of [`Kandinsky6Transformer3DModel`]. + + Args: + sample (`torch.Tensor` of shape `(batch_size, num_frames, height, width, out_visual_dim)`): + The predicted video velocity. + audio_sample (`torch.Tensor` of shape `(batch_size, audio_length, out_audio_dim)`, *optional*): + The predicted audio velocity, `None` when the model was called without `audio_hidden_states`. + """ + + sample: torch.Tensor + audio_sample: torch.Tensor | None = None + + +def get_freqs(dim: int, max_period: float = 10000.0) -> Tensor: + """Return inverse frequencies for rotary position embeddings. + + Args: + dim (`int`): Number of frequency values to generate. + max_period (`float`, *optional*, defaults to 10000.0): Maximum period + used by the frequency schedule. + + Returns: + `torch.Tensor`: Frequency values in float32. + """ + return torch.exp(-math.log(max_period) * torch.arange(start=0, end=dim, dtype=torch.float32) / dim) + + +def apply_scale_shift(normed: Tensor, x: Tensor, scale: Tensor, shift: Tensor) -> Tensor: + """Apply an AdaLN-style scale/shift affine to an already-normalized tensor, in fp32, cast back to ``x.dtype``. + + Callers compute ``normed`` themselves (e.g. ``self.some_norm(x.float())``) so the norm-layer call stays visible in + `forward` instead of being hidden inside this helper. + """ + if x.ndim > 2 and scale.ndim == 2: + shape = (scale.shape[0],) + (1,) * (x.ndim - 2) + (scale.shape[-1],) + scale, shift = scale.reshape(shape), shift.reshape(shape) + return (normed * (scale.float() + 1.0) + shift.float()).to(dtype=x.dtype) + + +def apply_gate_sum(x: Tensor, out: Tensor, gate: Tensor) -> Tensor: + """Residual gate in fp32, cast back to ``x.dtype``.""" + if x.ndim > 2 and gate.ndim == 2: + gate = gate.reshape((gate.shape[0],) + (1,) * (x.ndim - 2) + (gate.shape[-1],)) + return (x.float() + gate.float() * out.float()).to(dtype=x.dtype) + + +def apply_rotary(x: Tensor, rope: Tensor) -> Tensor: + """RoPE apply in fp32 (rope tables are fp32), cast back to ``x.dtype``.""" + x_ = x.reshape(*x.shape[:-1], -1, 1, 2).float() + return (rope.float() * x_).sum(dim=-1).reshape(*x.shape).to(dtype=x.dtype) + + +class Kandinsky6RoPE1D(nn.Module): + """1-D Rotary Position Embedding — used for text and audio sequences.""" + + def __init__( + self, + dim: int, + max_pos: int = 2048, + max_period: float = 10000.0, + freqs_scaling: float = 1.0, + ): + super().__init__() + self.dim = dim + self.max_pos = max_pos + self.max_period = max_period + self.freqs_scaling = freqs_scaling + freq = get_freqs(dim // 2, max_period) * freqs_scaling + self.register_buffer("angles", torch.outer(torch.arange(max_pos, dtype=freq.dtype), freq), persistent=False) + + def forward(self, pos: Tensor) -> Tensor: + # RoPE tables are fp32; keep trig in fp32. + angles = self.angles[pos] # (seq_len, dim//2) + rope = torch.stack([torch.cos(angles), -torch.sin(angles), torch.sin(angles), torch.cos(angles)], dim=-1) + return rope.view(*rope.shape[:-1], 2, 2).unsqueeze(-4) + + +class Kandinsky6RoPE3D(nn.Module): + """3-D Rotary Position Embedding — used for video spatial-temporal tokens (T, H, W).""" + + def __init__( + self, + axes_dims: tuple[int, int, int], + max_pos: tuple[int, int, int] = (128, 128, 128), + max_period: float = 10000.0, + ): + super().__init__() + self.axes_dims = axes_dims + self.max_pos = max_pos + self.max_period = max_period + for i, (d, mp) in enumerate(zip(axes_dims, max_pos)): + freq = get_freqs(d // 2, max_period) + self.register_buffer( + f"angles_{i}", torch.outer(torch.arange(mp, dtype=freq.dtype), freq), persistent=False + ) + + def forward( + self, + pos: tuple[Tensor, Tensor, Tensor], + scale_factor: tuple[float, float, float] = (1.0, 1.0, 1.0), + ) -> Tensor: + # `pos` holds one index tensor per axis; the grid size is implied by their lengths. + num_frames, height, width = (int(axis_pos.shape[0]) for axis_pos in pos) + angles_t = self.angles_0[pos[0]] / scale_factor[0] # (T, d//2) + angles_h = self.angles_1[pos[1]] / scale_factor[1] # (H, d//2) + angles_w = self.angles_2[pos[2]] / scale_factor[2] # (W, d//2) + + angles = torch.cat( + [ + angles_t.view(num_frames, 1, 1, -1).expand(num_frames, height, width, -1), + angles_h.view(1, height, 1, -1).expand(num_frames, height, width, -1), + angles_w.view(1, 1, width, -1).expand(num_frames, height, width, -1), + ], + dim=-1, + ) + cos, sin = torch.cos(angles), torch.sin(angles) + rope = torch.stack([cos, -sin, sin, cos], dim=-1) # (T, H, W, total_dim, 4) + rope = rope.view(*rope.shape[:-1], 2, 2) # (T, H, W, total_dim, 2, 2) + return rope.unsqueeze(-4) # (T, H, W, 1, total_dim, 2, 2) + + +class Kandinsky6AttnProcessor: + """Diffusers attention processor used by the TI2VA transformer.""" + + _attention_backend = None + _parallel_config = None + + def __init__(self, attention_backend=None, parallel_config=None): + self._attention_backend = attention_backend + self._parallel_config = parallel_config + + def __call__( + self, + attn: Any, + hidden_states: Tensor, + encoder_hidden_states: Tensor | None = None, + rotary_emb: Tensor | None = None, + rotary_emb_kv: Tensor | None = None, + attn_mask: Tensor | None = None, + ) -> Tensor: + query = attn.to_query(hidden_states) + if encoder_hidden_states is None: + key = attn.to_key(hidden_states) + value = attn.to_value(hidden_states) + else: + key = attn.to_key(encoder_hidden_states) + value = attn.to_value(encoder_hidden_states) + + query = query.reshape(*query.shape[:-1], attn.num_heads, -1) + key = key.reshape(*key.shape[:-1], attn.num_heads, -1) + value = value.reshape(*value.shape[:-1], attn.num_heads, -1) + query = attn.query_norm(query) + key = attn.key_norm(key) + + if rotary_emb is not None: + query = apply_rotary(query, rotary_emb).to(dtype=query.dtype) + if rotary_emb_kv is not None: + key = apply_rotary(key, rotary_emb_kv).to(dtype=key.dtype) + + output = dispatch_attention_fn( + query, + key, + value, + attn_mask=attn_mask, + backend=self._attention_backend, + parallel_config=self._parallel_config, + ) + + return attn.out_layer(output.flatten(-2, -1)) + + +class Kandinsky6TimeEmbeddings(nn.Module): + """Sinusoidal timestep embedding with a K6-compatible parameter layout.""" + + def __init__(self, model_dim: int, time_dim: int): + super().__init__() + if model_dim % 2: + raise ValueError("model_dim must be even") + self.time_proj = Timesteps(model_dim, flip_sin_to_cos=True, downscale_freq_shift=0) + self.timestep_embedder = TimestepEmbedding(model_dim, time_dim, act_fn="silu") + + def forward(self, timestep: Tensor) -> Tensor: + # The sinusoidal embedding is float32; `_keep_in_fp32_modules` keeps these layers float32 under + # `from_pretrained(torch_dtype=...)`, and the cast aligns the input with whatever dtype they hold. + embed = self.time_proj(timestep) + embed = embed.to(get_parameter_dtype(self.timestep_embedder)) + return self.timestep_embedder(embed) + + +class Kandinsky6TextEmbeddings(nn.Module): + """Text projection and normalization used by K6 text branches.""" + + def __init__(self, text_dim: int, model_dim: int): + super().__init__() + self.in_layer = nn.Linear(text_dim, model_dim) + self.norm = nn.LayerNorm(model_dim, elementwise_affine=True) + + def forward(self, x: Tensor) -> Tensor: + return self.norm(self.in_layer(x)) + + +class Kandinsky6VisualEmbeddings(nn.Module): + """Patch projection for ``[B,T,H,W,C]`` visual tokens.""" + + def __init__(self, visual_dim: int, model_dim: int, patch_size: tuple[int, int, int]): + super().__init__() + self.patch_size = patch_size + self.in_layer = nn.Linear(math.prod(patch_size) * visual_dim, model_dim) + + def forward(self, x: Tensor) -> Tensor: + batch, duration, height, width, channels = x.shape + p_t, p_h, p_w = self.patch_size + x = ( + x.view(batch, duration // p_t, p_t, height // p_h, p_h, width // p_w, p_w, channels) + .permute(0, 1, 3, 5, 2, 4, 6, 7) + .flatten(4, 7) + ) + return self.in_layer(x) + + +class Kandinsky6Modulation(nn.Module): + """AdaLN modulation projection.""" + + def __init__(self, time_dim: int, model_dim: int, num_params: int): + super().__init__() + self.activation = nn.SiLU() + self.out_layer = nn.Linear(time_dim, num_params * model_dim) + + def forward(self, x: Tensor) -> Tensor: + return self.out_layer(self.activation(x.to(get_parameter_dtype(self.out_layer)))) + + +class Kandinsky6Attention(nn.Module, AttentionModuleMixin): + """K6 attention with the Diffusers ``set_processor`` contract.""" + + _default_processor_cls = Kandinsky6AttnProcessor + _available_processors = [Kandinsky6AttnProcessor] + + def __init__( + self, + num_channels: int, + head_dim: int, + kv_dim: int | None = None, + processor: Kandinsky6AttnProcessor | None = None, + ): + super().__init__() + if num_channels % head_dim: + raise ValueError("num_channels must be divisible by head_dim") + kv_dim = kv_dim or num_channels + self.num_heads = num_channels // head_dim + self.to_query = nn.Linear(num_channels, num_channels) + self.to_key = nn.Linear(kv_dim, num_channels) + self.to_value = nn.Linear(kv_dim, num_channels) + self.query_norm = nn.RMSNorm(head_dim) + self.key_norm = nn.RMSNorm(head_dim) + self.out_layer = nn.Linear(num_channels, num_channels) + self.set_processor(processor or self._default_processor_cls()) + + def forward( + self, + hidden_states: Tensor, + encoder_hidden_states: Tensor | None = None, + attn_mask: Tensor | None = None, + rotary_emb: Tensor | None = None, + rope_q: Tensor | None = None, + rope_kv: Tensor | None = None, + ) -> Tensor: + # Native K6 blocks pass ``(hidden, rope, mask)`` for self-attention. Keep that call shape while exposing + # Diffusers' encoder_hidden_states/rotary_emb keyword boundary. + rotary_emb = rope_q if rope_q is not None else rotary_emb + rotary_emb_kv = rope_kv if rope_kv is not None else rotary_emb + return self.processor( + self, + hidden_states, + encoder_hidden_states=encoder_hidden_states, + rotary_emb=rotary_emb, + rotary_emb_kv=rotary_emb_kv, + attn_mask=attn_mask, + ) + + +class Kandinsky6OutLayer(nn.Module): + """Projects visual hidden states back to packed latent patches.""" + + def __init__(self, model_dim: int, time_dim: int, visual_dim: int, patch_size: tuple[int, int, int]): + super().__init__() + self.patch_size = patch_size + self.modulation = Kandinsky6Modulation(time_dim, model_dim, 2) + self.norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.out_layer = nn.Linear(model_dim, math.prod(patch_size) * visual_dim) + + def forward(self, visual_embed: Tensor, time_embed: Tensor) -> Tensor: + shift, scale = torch.chunk(self.modulation(time_embed), 2, dim=-1) + condition_shape = (scale.shape[0],) + (1,) * (visual_embed.ndim - 2) + (scale.shape[-1],) + x = apply_scale_shift( + self.norm(visual_embed.float()), + visual_embed, + scale.reshape(condition_shape), + shift.reshape(condition_shape), + ) + x = self.out_layer(x) + + batch, duration, height, width = x.shape[:4] + p_t, p_h, p_w = self.patch_size + return ( + x.view(batch, duration, height, width, -1, p_t, p_h, p_w) + .permute(0, 1, 5, 2, 6, 3, 7, 4) + .flatten(1, 2) + .flatten(2, 3) + .flatten(3, 4) + ) + + +class Kandinsky6OutLayerAudio(nn.Module): + """Projects audio hidden states back to audio latent channels.""" + + def __init__(self, model_dim: int, time_dim: int, audio_dim: int): + super().__init__() + self.modulation = Kandinsky6Modulation(time_dim, model_dim, 2) + self.norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.out_layer = nn.Linear(model_dim, audio_dim) + + def forward(self, audio_embed: Tensor, time_embed: Tensor) -> Tensor: + shift, scale = torch.chunk(self.modulation(time_embed), 2, dim=-1) + x = apply_scale_shift(self.norm(audio_embed.float()), audio_embed, scale, shift) + # The reference audio head normalizes a second time after the AdaLN affine; the released weights were + # trained this way, so the double norm is kept for parity even though the video head has none. + x = self.norm(x) + return self.out_layer(x) + + +class Kandinsky6TransformerEncoderBlock(nn.Module): + """Text self-attention + feed-forward block in Diffusers style.""" + + def __init__( + self, + model_dim: int, + time_dim: int, + ff_dim: int, + head_dim: int, + ): + super().__init__() + self.text_modulation = Kandinsky6Modulation(time_dim, model_dim, 6) + self.attn_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.attn = Kandinsky6Attention(model_dim, head_dim) + self.feed_forward_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.feed_forward = FeedForward(model_dim, inner_dim=ff_dim, activation_fn="gelu", bias=False) + + def forward(self, x: Tensor, time_embed: Tensor, rope: Tensor, attn_mask: Tensor | None = None) -> Tensor: + sa_params, ff_params = torch.chunk(self.text_modulation(time_embed), 2, dim=-1) + shift, scale, gate = torch.chunk(sa_params, 3, dim=-1) + x = apply_gate_sum( + x, + self.attn( + apply_scale_shift(self.attn_norm(x.float()), x, scale, shift), + rotary_emb=rope, + attn_mask=attn_mask, + ), + gate, + ) + shift, scale, gate = torch.chunk(ff_params, 3, dim=-1) + return apply_gate_sum( + x, self.feed_forward(apply_scale_shift(self.feed_forward_norm(x.float()), x, scale, shift)), gate + ) + + +class Kandinsky6TransformerDecoderBlock(nn.Module): + """Visual self-attention, text cross-attention, and feed-forward submodules. + + `Kandinsky6FusedTransformerDecoderBlock` uses this class only as a named submodule container + (`self_attention`/`cross_attention`/`feed_forward` and their norms/modulation), calling those submodules directly + rather than this class's own `forward`. + """ + + def __init__( + self, + model_dim: int, + time_dim: int, + ff_dim: int, + head_dim: int, + ): + super().__init__() + self.visual_modulation = Kandinsky6Modulation(time_dim, model_dim, 9) + self.self_attention_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.self_attention = Kandinsky6Attention(model_dim, head_dim) + self.cross_attention_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.cross_attention = Kandinsky6Attention( + model_dim, + head_dim, + kv_dim=model_dim, + ) + self.feed_forward_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.feed_forward = FeedForward(model_dim, inner_dim=ff_dim, activation_fn="gelu", bias=False) + + +class Kandinsky6FusedTransformerDecoderBlock(nn.Module): + """Fused K6 video/audio block with cross-modal attention.""" + + def __init__( + self, + model_dim: int, + time_dim: int, + ff_dim: int, + head_dim: int, + model_dim_a: int, + time_dim_a: int, + ff_dim_a: int, + head_dim_a: int, + ca_rope: bool = False, + cross_gates: bool = False, + fix_modulation: bool = False, + ): + super().__init__() + self.video_dec_block = Kandinsky6TransformerDecoderBlock(model_dim, time_dim, ff_dim, head_dim) + self.audio_dec_block = Kandinsky6TransformerDecoderBlock(model_dim_a, time_dim_a, ff_dim_a, head_dim_a) + self.va_cross_attention = Kandinsky6Attention( + model_dim, + head_dim, + kv_dim=model_dim_a, + ) + self.av_cross_attention = Kandinsky6Attention( + model_dim_a, + head_dim_a, + kv_dim=model_dim, + ) + self.va_modulation = Kandinsky6Modulation( + time_dim, + model_dim if not cross_gates else model_dim * 2 + model_dim_a, + 1 if cross_gates else 3, + ) + self.av_modulation = Kandinsky6Modulation( + time_dim_a, + model_dim_a if not cross_gates else model_dim_a * 2 + model_dim, + 1 if cross_gates else 3, + ) + self.va_normalization = nn.LayerNorm(model_dim, elementwise_affine=False) + self.av_normalization = nn.LayerNorm(model_dim_a, elementwise_affine=False) + self.ca_rope = ca_rope + self.cross_gates = cross_gates + self.fix_modulation = fix_modulation + self.model_dim = model_dim + self.model_dim_a = model_dim_a + + def forward( + self, + vis: Tensor | None, + aud: Tensor | None, + text_v: Tensor, + text_a: Tensor, + time_embed: tuple[Tensor, Tensor], + vis_rope: Tensor | None, + aud_rope: Tensor | None, + attn_mask=None, + ) -> tuple[Tensor | None, Tensor | None]: + t_v, t_a = time_embed + if vis is not None: + sa_p, ca_p, ff_p = torch.chunk(self.video_dec_block.visual_modulation(t_v), 3, dim=-1) + shift, scale, gate = torch.chunk(sa_p, 3, dim=-1) + vis = apply_gate_sum( + vis, + self.video_dec_block.self_attention( + apply_scale_shift(self.video_dec_block.self_attention_norm(vis.float()), vis, scale, shift), + rotary_emb=vis_rope, + ), + gate, + ).type_as(vis) + shift, scale, gate_v = torch.chunk(ca_p, 3, dim=-1) + vis_pre_ca = apply_scale_shift(self.video_dec_block.cross_attention_norm(vis.float()), vis, scale, shift) + vis_out_t = self.video_dec_block.cross_attention( + vis_pre_ca, + encoder_hidden_states=text_v, + attn_mask=attn_mask, + ) + + if aud is not None: + sa_p, ca_p, ff_p_a = torch.chunk(self.audio_dec_block.visual_modulation(t_a), 3, dim=-1) + shift, scale, gate = torch.chunk(sa_p, 3, dim=-1) + aud = apply_gate_sum( + aud, + self.audio_dec_block.self_attention( + apply_scale_shift(self.audio_dec_block.self_attention_norm(aud.float()), aud, scale, shift), + rotary_emb=aud_rope, + ), + gate, + ).type_as(aud) + shift, scale, gate_a = torch.chunk(ca_p, 3, dim=-1) + aud_pre_ca = apply_scale_shift(self.audio_dec_block.cross_attention_norm(aud.float()), aud, scale, shift) + aud_out_t = self.audio_dec_block.cross_attention( + aud_pre_ca, + encoder_hidden_states=text_a, + attn_mask=attn_mask, + ) + aud = apply_gate_sum(aud, aud_out_t, gate_a).type_as(aud) + + if vis is not None: + t_va_mod = t_a if not self.fix_modulation else t_v + t_av_mod = t_v if not self.fix_modulation else t_a + va_params = self.va_modulation(t_va_mod) + av_params = self.av_modulation(t_av_mod) + if self.cross_gates: + va_shift, va_scale, va_gate = torch.split( + va_params, [self.model_dim, self.model_dim, self.model_dim_a], dim=-1 + ) + av_shift, av_scale, av_gate = torch.split( + av_params, [self.model_dim_a, self.model_dim_a, self.model_dim], dim=-1 + ) + else: + va_shift, va_scale, va_gate = torch.chunk(va_params, 3, dim=-1) + av_shift, av_scale, av_gate = torch.chunk(av_params, 3, dim=-1) + vis = apply_gate_sum(vis, vis_out_t, gate_v).type_as(vis) + vis_for_va = apply_scale_shift(self.va_normalization(vis.float()), vis, va_scale, va_shift) + aud_for_av = apply_scale_shift(self.av_normalization(aud.float()), aud, av_scale, av_shift) + rq_v = vis_rope if self.ca_rope else None + rk_a = aud_rope if self.ca_rope else None + vis_from_aud = self.va_cross_attention( + vis_for_va, + encoder_hidden_states=aud_pre_ca, + rope_q=rq_v, + rope_kv=rk_a, + ) + aud_from_vis = self.av_cross_attention( + aud_for_av, + encoder_hidden_states=vis_pre_ca, + rope_q=rk_a, + rope_kv=rq_v, + ) + vis = apply_gate_sum(vis, vis_from_aud, va_gate if not self.cross_gates else av_gate).type_as(vis) + aud = apply_gate_sum(aud, aud_from_vis, av_gate if not self.cross_gates else va_gate).type_as(aud) + elif vis is not None: + vis = apply_gate_sum(vis, vis_out_t, gate_v).type_as(vis) + + if vis is not None: + shift, scale, gate = torch.chunk(ff_p, 3, dim=-1) + vis = apply_gate_sum( + vis, + self.video_dec_block.feed_forward( + apply_scale_shift(self.video_dec_block.feed_forward_norm(vis.float()), vis, scale, shift) + ), + gate, + ).type_as(vis) + if aud is not None: + shift, scale, gate = torch.chunk(ff_p_a, 3, dim=-1) + aud = apply_gate_sum( + aud, + self.audio_dec_block.feed_forward( + apply_scale_shift(self.audio_dec_block.feed_forward_norm(aud.float()), aud, scale, shift) + ), + gate, + ).type_as(aud) + return vis, aud + + +class Kandinsky6Transformer3DModel( + ModelMixin, + ConfigMixin, + PeftAdapterMixin, + CacheMixin, + AttentionMixin, +): + """Kandinsky 6 multimodal transformer for text/image-to-video-and-audio generation. + + Video and audio are denoised together through fused, cross-modal transformer blocks, each conditioned on its own + text branch (Qwen2.5-VL tokens + CLIP pooled embedding). Passing no `audio_hidden_states` denoises video alone + while still running the fused block's video self-attention, cross-attention, and feed-forward stages. Rotary + embeddings are computed inside `forward` from the token grid. + + Args: + in_visual_dim (`int`, *optional*, defaults to 16): Number of input video latent channels. + out_visual_dim (`int`, *optional*, defaults to 16): Number of output video latent channels. + in_text_dim (`int`, *optional*, defaults to 3584): Text token embedding dimension. + in_text_dim2 (`int`, *optional*, defaults to 768): Pooled text embedding dimension. + time_dim (`int`, *optional*, defaults to 1024): Time embedding dimension. + patch_size (`tuple[int, int, int]`, *optional*, defaults to ``(1, 2, 2)``): Video patch size. + model_dim (`int`, *optional*, defaults to 4096): Video transformer hidden dimension. + ff_dim (`int`, *optional*, defaults to 16384): Video feed-forward hidden dimension. + num_text_blocks (`int`, *optional*, defaults to 4): Number of text blocks per modality. + num_visual_blocks (`int`, *optional*, defaults to 60): Number of fused video/audio blocks. + axes_dims (`tuple[int, int, int]`, *optional*, defaults to ``(32, 48, 48)``): RoPE dimensions for video. + visual_cond (`bool`, *optional*, defaults to True): Whether video conditioning channels are present. + in_audio_dim (`int`, *optional*, defaults to 20): Number of input audio latent channels. + out_audio_dim (`int`, *optional*, defaults to 20): Number of output audio latent channels. + model_dim_a (`int`, *optional*): Audio transformer hidden dimension. Defaults to `model_dim`. + time_dim_a (`int`, *optional*): Audio time embedding dimension. Defaults to `time_dim`. + ff_dim_a (`int`, *optional*): Audio feed-forward hidden dimension. Defaults to `ff_dim`. + axes_dims_a (`tuple[int, int, int]`, *optional*): Audio RoPE dimensions. Defaults to `axes_dims`. + audio_freqs_scaling (`float`, *optional*, defaults to 1.0): Audio RoPE frequency scaling. + scale_factor (`tuple[float, float, float]`, *optional*, defaults to `(1.0, 2.0, 2.0)`): Per-axis + `(t, h, w)` RoPE frequency scaling applied to the video positions. + text_token_padding (`bool`, *optional*, defaults to False): Checkpoint metadata recording whether the + reference model's text sequences are padded. `forward` always accepts an optional `encoder_attention_mask` + regardless of this flag; whether one is actually passed is entirely up to the caller. + ca_rope (`bool`, *optional*, defaults to False): Whether to use cross-modal audio RoPE. + cross_gates (`bool`, *optional*, defaults to False): Whether to use cross-modal residual gates. + fix_modulation (`bool`, *optional*, defaults to False): Whether to use the fixed modulation variant. + visual_token_type_num_embeddings (`int`, *optional*, defaults to 0): Number of visual token type embeddings. + + Released checkpoints set `text_token_padding`, `ca_rope`, `cross_gates`, and `fix_modulation` to `True` (see each + checkpoint's `transformer/config.json`); the `False` defaults only describe an architecture variant this repo does + not ship weights for. + """ + + _repeated_blocks = [ + "Kandinsky6TransformerEncoderBlock", + "Kandinsky6FusedTransformerDecoderBlock", + ] + _no_split_modules = _repeated_blocks + _skip_layerwise_casting_patterns = ["norm"] + # Timestep embeddings and every AdaLN modulation projection (`*_modulation`, `out_layer.modulation`) are + # precision-sensitive and stay float32 under `from_pretrained(torch_dtype=...)`. + _keep_in_fp32_modules = ["time_embeddings", "modulation"] + _supports_gradient_checkpointing = True + + @register_to_config + def __init__( + self, + in_visual_dim: int = 16, + out_visual_dim: int = 16, + in_text_dim: int = 3584, + in_text_dim2: int = 768, + time_dim: int = 1024, + patch_size: tuple = (1, 2, 2), + model_dim: int = 4096, + ff_dim: int = 16384, + num_text_blocks: int = 4, + num_visual_blocks: int = 60, + axes_dims: tuple = (32, 48, 48), + visual_cond: bool = True, + in_audio_dim: int = 20, + out_audio_dim: int = 20, + model_dim_a: int | None = None, + time_dim_a: int | None = None, + ff_dim_a: int | None = None, + axes_dims_a: tuple | None = None, + audio_freqs_scaling: float = 1.0, + scale_factor: tuple | list[float] = (1.0, 2.0, 2.0), + text_token_padding: bool = False, + ca_rope: bool = False, + cross_gates: bool = False, + fix_modulation: bool = False, + visual_token_type_num_embeddings: int = 0, + ) -> None: + super().__init__() + self.patch_size = patch_size + self.visual_cond = visual_cond + self.in_visual_dim = in_visual_dim + self.in_audio_dim = in_audio_dim + self.text_token_padding = text_token_padding + self.scale_factor = tuple(float(value) for value in scale_factor) + self.visual_token_type_num_embeddings = int(visual_token_type_num_embeddings or 0) + head_dim = sum(axes_dims) + model_dim_a = model_dim_a or model_dim + time_dim_a = time_dim_a or time_dim + ff_dim_a = ff_dim_a or ff_dim + axes_dims_a = axes_dims_a or axes_dims + head_dim_a = sum(axes_dims_a) + + vis_in_dim = (2 * in_visual_dim + 1) if visual_cond else in_visual_dim + self.visual_embeddings = Kandinsky6VisualEmbeddings(vis_in_dim, model_dim, patch_size) + if self.visual_token_type_num_embeddings > 0: + self.visual_token_type_embeddings = nn.Embedding(self.visual_token_type_num_embeddings, model_dim) + self.visual_rope_embeddings = Kandinsky6RoPE3D(axes_dims) + self.out_layer = Kandinsky6OutLayer(model_dim, time_dim, out_visual_dim, patch_size) + + self.audio_embeddings = Kandinsky6TextEmbeddings(in_audio_dim, model_dim_a) + self.audio_rope_embeddings = Kandinsky6RoPE1D(head_dim_a, freqs_scaling=audio_freqs_scaling) + self.audio_out_layer = Kandinsky6OutLayerAudio(model_dim_a, time_dim_a, out_audio_dim) + for prefix, md, td, fd, hd in ( + ("video", model_dim, time_dim, ff_dim, head_dim), + ("audio", model_dim_a, time_dim_a, ff_dim_a, head_dim_a), + ): + setattr(self, f"{prefix}_time_embeddings", Kandinsky6TimeEmbeddings(md, td)) + setattr(self, f"{prefix}_text_embeddings", Kandinsky6TextEmbeddings(in_text_dim, md)) + setattr(self, f"{prefix}_pooled_text_embeddings", Kandinsky6TextEmbeddings(in_text_dim2, td)) + setattr(self, f"{prefix}_text_rope_embeddings", Kandinsky6RoPE1D(hd)) + setattr( + self, + f"{prefix}_text_transformer_blocks", + nn.ModuleList([Kandinsky6TransformerEncoderBlock(md, td, fd, hd) for _ in range(num_text_blocks)]), + ) + self.visual_transformer_blocks = nn.ModuleList( + [ + Kandinsky6FusedTransformerDecoderBlock( + model_dim, + time_dim, + ff_dim, + head_dim, + model_dim_a, + time_dim_a, + ff_dim_a, + head_dim_a, + ca_rope, + cross_gates, + fix_modulation, + ) + for _ in range(num_visual_blocks) + ] + ) + + self.gradient_checkpointing = False + + def forward( + self, + hidden_states: Tensor, + encoder_hidden_states: Tensor, + pooled_projections: Tensor, + timestep: Tensor, + audio_hidden_states: Tensor | None = None, + visual_rope_pos: tuple[Tensor, Tensor, Tensor] | None = None, + encoder_attention_mask: Tensor | None = None, + visual_token_type_ids: Tensor | None = None, + return_dict: bool = True, + ) -> Kandinsky6TransformerOutput | tuple[Tensor, ...]: + r""" + Args: + hidden_states (`torch.Tensor` of shape `(batch_size, num_frames, height, width, in_channels)`): + Video latents in the `(B, T, H, W, C)` layout. With `visual_cond=True`, `in_channels` is `2 * + in_visual_dim + 1`: the noisy latent, the conditioning latent and a conditioning mask. + encoder_hidden_states (`torch.Tensor` of shape `(batch_size, sequence_length, in_text_dim)`): + Text token embeddings, shared by the video and audio text branches. + pooled_projections (`torch.Tensor` of shape `(batch_size, in_text_dim2)`): + Pooled text embedding added to the timestep embedding of both branches. + timestep (`torch.Tensor` of shape `(batch_size,)`): + Diffusion timestep on the `[0, num_train_timesteps]` scale, shared by both modalities. + audio_hidden_states (`torch.Tensor` of shape `(batch_size, audio_length, in_audio_dim)`, *optional*): + Audio latents. When omitted the fused blocks run their video path only. + visual_rope_pos (`tuple[torch.Tensor, torch.Tensor, torch.Tensor]`, *optional*): + Per-axis `(t, h, w)` rotary position indices of the patchified video tokens. Defaults to `arange` over + each axis. The pipeline passes an explicit temporal index when it appends a reference frame that reuses + position `0`. + encoder_attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*): + Boolean padding mask for `encoder_hidden_states`. Pass `None` when no prompt is padded. + visual_token_type_ids (`torch.Tensor` of shape `(batch_size, num_frames)`, *optional*): + Per-frame token type ids, embedded through `visual_token_type_embeddings`. Requires + `visual_token_type_num_embeddings > 0`. + return_dict (`bool`, defaults to `True`): + Whether to return a [`Kandinsky6TransformerOutput`] instead of a plain tuple. + + Returns: + [`Kandinsky6TransformerOutput`] or `tuple`: + The predicted video velocity in the `(B, T, H, W, out_visual_dim)` layout and, when + `audio_hidden_states` was given, the predicted audio velocity of shape `(B, audio_length, + out_audio_dim)`. + """ + if visual_token_type_ids is not None and self.visual_token_type_num_embeddings == 0: + raise ValueError("`visual_token_type_ids` requires `visual_token_type_num_embeddings > 0`") + checkpoint = torch.is_grad_enabled() and self.gradient_checkpointing + device = hidden_states.device + + # 1. Rotary embeddings for the two text branches + text_pos = torch.arange(encoder_hidden_states.shape[1], device=device) + video_text_rope = self.video_text_rope_embeddings(text_pos) + audio_text_rope = self.audio_text_rope_embeddings(text_pos) + + # 2. Encode the text tokens through the video and audio text branches + video_text_embed = self.video_text_embeddings(encoder_hidden_states) + video_temb = self.video_time_embeddings(timestep) + self.video_pooled_text_embeddings(pooled_projections) + for block in self.video_text_transformer_blocks: + args = (video_text_embed, video_temb, video_text_rope, encoder_attention_mask) + video_text_embed = self._gradient_checkpointing_func(block, *args) if checkpoint else block(*args) + + audio_text_embed = self.audio_text_embeddings(encoder_hidden_states) + audio_temb = self.audio_time_embeddings(timestep) + self.audio_pooled_text_embeddings(pooled_projections) + for block in self.audio_text_transformer_blocks: + args = (audio_text_embed, audio_temb, audio_text_rope, encoder_attention_mask) + audio_text_embed = self._gradient_checkpointing_func(block, *args) if checkpoint else block(*args) + + # 3. Patchify the video latents and build their rotary embeddings + visual_embed = self.visual_embeddings(hidden_states) + if visual_token_type_ids is not None: + token_types = self.visual_token_type_embeddings(visual_token_type_ids) + visual_embed = visual_embed + token_types[:, :, None, None, :] + visual_shape = visual_embed.shape[1:4] + if visual_rope_pos is None: + visual_rope_pos = tuple(torch.arange(size, device=device) for size in visual_shape) + visual_rope = self.visual_rope_embeddings(visual_rope_pos, self.scale_factor) + visual_embed = visual_embed.flatten(1, 3) + visual_rope = visual_rope.flatten(0, 2) + + # 4. Embed the audio latents and build their rotary embeddings + audio_embed = audio_rope = None + if audio_hidden_states is not None: + audio_embed = self.audio_embeddings(audio_hidden_states) + audio_rope = self.audio_rope_embeddings(torch.arange(audio_hidden_states.shape[1], device=device)) + + # 5. Run the fused video/audio transformer blocks (a block skips the audio path when it is absent) + for block in self.visual_transformer_blocks: + args = ( + visual_embed, + audio_embed, + video_text_embed, + audio_text_embed, + (video_temb, audio_temb), + visual_rope, + audio_rope, + encoder_attention_mask, + ) + visual_embed, audio_embed = self._gradient_checkpointing_func(block, *args) if checkpoint else block(*args) + + # 6. Project back to the latent space + visual_embed = visual_embed.reshape(-1, *visual_shape, visual_embed.shape[-1]) + video_out = self.out_layer(visual_embed, video_temb) + audio_out = self.audio_out_layer(audio_embed, audio_temb) if audio_embed is not None else None + + if not return_dict: + return (video_out,) if audio_out is None else (video_out, audio_out) + return Kandinsky6TransformerOutput(sample=video_out, audio_sample=audio_out) diff --git a/src/diffusers/models/transformers/transformer_kandinsky6_sr.py b/src/diffusers/models/transformers/transformer_kandinsky6_sr.py new file mode 100644 index 000000000000..b11bba2af7a3 --- /dev/null +++ b/src/diffusers/models/transformers/transformer_kandinsky6_sr.py @@ -0,0 +1,559 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +"""Kandinsky 6 video super-resolution transformer.""" + +from __future__ import annotations + +import functools +import math +from typing import TYPE_CHECKING, Any + +import torch +from torch import Tensor, nn + +from ...configuration_utils import ConfigMixin, register_to_config +from ...loaders import PeftAdapterMixin +from ...utils import logging +from ..attention import AttentionMixin, AttentionModuleMixin, FeedForward +from ..attention_dispatch import _CAN_USE_FLEX_ATTN, AttentionBackendName, dispatch_attention_fn +from ..embeddings import TimestepEmbedding, Timesteps +from ..modeling_outputs import Transformer2DModelOutput +from ..modeling_utils import ModelMixin, get_parameter_dtype + + +if TYPE_CHECKING: + from torch.nn.attention.flex_attention import BlockMask + + +logger = logging.get_logger(__name__) + + +# Side of the local token block that NABLA sparse attention groups into one 64-token attention block. +FRACTAL_BLOCK_SIZE = 8 + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.get_freqs +def get_freqs(dim: int, max_period: float = 10000.0) -> Tensor: + """Return inverse frequencies for rotary position embeddings. + + Args: + dim (`int`): Number of frequency values to generate. + max_period (`float`, *optional*, defaults to 10000.0): Maximum period + used by the frequency schedule. + + Returns: + `torch.Tensor`: Frequency values in float32. + """ + return torch.exp(-math.log(max_period) * torch.arange(start=0, end=dim, dtype=torch.float32) / dim) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.apply_scale_shift +def apply_scale_shift(normed: Tensor, x: Tensor, scale: Tensor, shift: Tensor) -> Tensor: + """Apply an AdaLN-style scale/shift affine to an already-normalized tensor, in fp32, cast back to ``x.dtype``. + + Callers compute ``normed`` themselves (e.g. ``self.some_norm(x.float())``) so the norm-layer call stays visible in + `forward` instead of being hidden inside this helper. + """ + if x.ndim > 2 and scale.ndim == 2: + shape = (scale.shape[0],) + (1,) * (x.ndim - 2) + (scale.shape[-1],) + scale, shift = scale.reshape(shape), shift.reshape(shape) + return (normed * (scale.float() + 1.0) + shift.float()).to(dtype=x.dtype) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.apply_gate_sum +def apply_gate_sum(x: Tensor, out: Tensor, gate: Tensor) -> Tensor: + """Residual gate in fp32, cast back to ``x.dtype``.""" + if x.ndim > 2 and gate.ndim == 2: + gate = gate.reshape((gate.shape[0],) + (1,) * (x.ndim - 2) + (gate.shape[-1],)) + return (x.float() + gate.float() * out.float()).to(dtype=x.dtype) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.apply_rotary +def apply_rotary(x: Tensor, rope: Tensor) -> Tensor: + """RoPE apply in fp32 (rope tables are fp32), cast back to ``x.dtype``.""" + x_ = x.reshape(*x.shape[:-1], -1, 1, 2).float() + return (rope.float() * x_).sum(dim=-1).reshape(*x.shape).to(dtype=x.dtype) + + +def _local_patch(x: Tensor, shape: tuple, group_size: tuple, dim: int = 0) -> Tensor: + T, H, W = shape + g1, g2, g3 = group_size + x = x.reshape(*x.shape[:dim], T // g1, g1, H // g2, g2, W // g3, g3, *x.shape[dim + 3 :]) + d = len(x.shape[:dim]) + x = x.permute(*range(d), d, d + 2, d + 4, d + 1, d + 3, d + 5, *range(d + 6, len(x.shape))) + return x.flatten(dim, dim + 2).flatten(dim + 1, dim + 3) + + +def _local_merge(x: Tensor, shape: tuple, group_size: tuple, dim: int = 0) -> Tensor: + T, H, W = shape + g1, g2, g3 = group_size + x = x.reshape(*x.shape[:dim], T // g1, H // g2, W // g3, g1, g2, g3, *x.shape[dim + 2 :]) + d = len(x.shape[:dim]) + x = x.permute(*range(d), d, d + 3, d + 1, d + 4, d + 2, d + 5, *range(d + 6, len(x.shape))) + return x.flatten(dim, dim + 1).flatten(dim + 1, dim + 2).flatten(dim + 2, dim + 3) + + +def nabla_block_mask( + q: Tensor, + k: Tensor, + sta: Tensor, + thr: float = 0.9, + block_size: int = 64, +) -> BlockMask: + """Build a dynamic NABLA block mask from query/key statistics and an STA (Sliding-Tile Attention, see + https://huggingface.co/papers/2502.04507) prior.""" + from torch.nn.attention.flex_attention import BlockMask + + B, h, S, D = q.shape + s1 = S // block_size + qa = q.reshape(B, h, s1, block_size, D).mean(-2) + ka = k.reshape(B, h, s1, block_size, D).mean(-2).transpose(-2, -1) + attn_map = torch.softmax((qa @ ka) / math.sqrt(D), dim=-1) + + vals, inds = attn_map.sort(-1) + mask = (vals.cumsum_(-1) >= 1 - thr).int().gather(-1, inds.argsort(-1)) + mask = torch.logical_or(mask, sta) + + kv_nb = mask.sum(-1).to(torch.int32) + kv_inds = mask.argsort(dim=-1, descending=True).to(torch.int32) + return BlockMask.from_kv_blocks( + torch.zeros_like(kv_nb), + kv_inds, + kv_nb, + kv_inds, + BLOCK_SIZE=block_size, + mask_mod=None, + ) + + +def sliding_tile_mask( + num_frames: int, height: int, width: int, window: tuple[int, int, int], device: torch.device +) -> Tensor: + """Build the static sliding-tile-attention prior over the `(t, h, w)` grid of 8x8 token blocks. + + Every block attends to the blocks within `window` (odd `(t, h, w)` extents) of itself. Returned as a boolean + `(num_frames * height * width, num_frames * height * width)` matrix in the flattened block order. + """ + window_t, window_h, window_w = window + positions = torch.arange(max(num_frames, height, width), device=device) + distance = (positions[:, None] - positions[None, :]).abs() + near_t = (distance[:num_frames, :num_frames] <= window_t // 2).flatten() + near_h = (distance[:height, :height] <= window_h // 2).flatten() + near_w = (distance[:width, :width] <= window_w // 2).flatten() + near_hw = (near_h[:, None] & near_w[None, :]).reshape(height, height, width, width).transpose(1, 2).flatten() + near = (near_t[:, None] & near_hw[None, :]).reshape(num_frames, num_frames, height * width, height * width) + return near.transpose(1, 2).reshape(num_frames * height * width, num_frames * height * width) + + +@functools.lru_cache(maxsize=None) +def _warn_uncompiled_flex_attention() -> None: + logger.warning( + "Kandinsky 6 SR attention runs PyTorch's flex attention eagerly, which materializes the full attention " + "matrix and does not fit in memory at video resolutions. Compile the transformer, e.g. with " + "`transformer.compile_repeated_blocks()`." + ) + + +class Kandinsky6SRAttnProcessor: + """Self-attention processor of the SR transformer: NABLA sparse attention over the `sparse_params` block pattern. + + Always dispatches on the `flex` backend: NABLA's sparsity is expressed as a `BlockMask`, which only `flex` can + consume. That backend also needs to run under `torch.compile` (e.g. `transformer.compile_repeated_blocks()`): + uncompiled, PyTorch's flex attention falls back to an eager implementation that materializes the full attention + matrix, which does not fit in memory at video resolutions. + """ + + _parallel_config = None + + def __call__( + self, + attn: "Kandinsky6SRAttention", + hidden_states: Tensor, + rotary_emb: Tensor, + sparse_params: dict[str, Any], + ) -> Tensor: + query = attn.to_query(hidden_states).unflatten(-1, (attn.num_heads, -1)) + key = attn.to_key(hidden_states).unflatten(-1, (attn.num_heads, -1)) + value = attn.to_value(hidden_states).unflatten(-1, (attn.num_heads, -1)) + query = attn.query_norm(query.float()).type_as(query) + key = attn.key_norm(key.float()).type_as(key) + query = apply_rotary(query, rotary_emb) + key = apply_rotary(key, rotary_emb) + + if not torch.compiler.is_compiling(): + _warn_uncompiled_flex_attention() + # The block statistics are computed from the `(B, heads, S, D)` layout the mask builder expects. + attn_mask = nabla_block_mask( + query.transpose(1, 2), + key.transpose(1, 2), + sparse_params["sta_mask"], + thr=sparse_params["threshold"], + ) + hidden_states = dispatch_attention_fn( + query, + key, + value, + attn_mask=attn_mask, + backend=AttentionBackendName.FLEX, + parallel_config=self._parallel_config, + ) + return attn.out_layer(hidden_states.flatten(2, 3)) + + +class Kandinsky6SRAttention(nn.Module, AttentionModuleMixin): + """SR self-attention with the Diffusers `set_processor` contract.""" + + _default_processor_cls = Kandinsky6SRAttnProcessor + _available_processors = [Kandinsky6SRAttnProcessor] + + def __init__(self, num_channels: int, head_dim: int, processor: Kandinsky6SRAttnProcessor | None = None): + super().__init__() + if num_channels % head_dim: + raise ValueError("num_channels must be divisible by head_dim") + self.num_heads = num_channels // head_dim + self.to_query = nn.Linear(num_channels, num_channels) + self.to_key = nn.Linear(num_channels, num_channels) + self.to_value = nn.Linear(num_channels, num_channels) + self.query_norm = nn.RMSNorm(head_dim) + self.key_norm = nn.RMSNorm(head_dim) + self.out_layer = nn.Linear(num_channels, num_channels) + self.set_processor(processor or self._default_processor_cls()) + + def forward( + self, + hidden_states: Tensor, + rotary_emb: Tensor, + sparse_params: dict[str, Any], + ) -> Tensor: + return self.processor(self, hidden_states, rotary_emb, sparse_params) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.Kandinsky6TimeEmbeddings with Kandinsky6->Kandinsky6SR +class Kandinsky6SRTimeEmbeddings(nn.Module): + """Sinusoidal timestep embedding with a K6-compatible parameter layout.""" + + def __init__(self, model_dim: int, time_dim: int): + super().__init__() + if model_dim % 2: + raise ValueError("model_dim must be even") + self.time_proj = Timesteps(model_dim, flip_sin_to_cos=True, downscale_freq_shift=0) + self.timestep_embedder = TimestepEmbedding(model_dim, time_dim, act_fn="silu") + + def forward(self, timestep: Tensor) -> Tensor: + # The sinusoidal embedding is float32; `_keep_in_fp32_modules` keeps these layers float32 under + # `from_pretrained(torch_dtype=...)`, and the cast aligns the input with whatever dtype they hold. + embed = self.time_proj(timestep) + embed = embed.to(get_parameter_dtype(self.timestep_embedder)) + return self.timestep_embedder(embed) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.Kandinsky6VisualEmbeddings with Kandinsky6->Kandinsky6SR +class Kandinsky6SRVisualEmbeddings(nn.Module): + """Patch projection for ``[B,T,H,W,C]`` visual tokens.""" + + def __init__(self, visual_dim: int, model_dim: int, patch_size: tuple[int, int, int]): + super().__init__() + self.patch_size = patch_size + self.in_layer = nn.Linear(math.prod(patch_size) * visual_dim, model_dim) + + def forward(self, x: Tensor) -> Tensor: + batch, duration, height, width, channels = x.shape + p_t, p_h, p_w = self.patch_size + x = ( + x.view(batch, duration // p_t, p_t, height // p_h, p_h, width // p_w, p_w, channels) + .permute(0, 1, 3, 5, 2, 4, 6, 7) + .flatten(4, 7) + ) + return self.in_layer(x) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.Kandinsky6Modulation with Kandinsky6->Kandinsky6SR +class Kandinsky6SRModulation(nn.Module): + """AdaLN modulation projection.""" + + def __init__(self, time_dim: int, model_dim: int, num_params: int): + super().__init__() + self.activation = nn.SiLU() + self.out_layer = nn.Linear(time_dim, num_params * model_dim) + + def forward(self, x: Tensor) -> Tensor: + return self.out_layer(self.activation(x.to(get_parameter_dtype(self.out_layer)))) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.Kandinsky6OutLayer with Kandinsky6->Kandinsky6SR +class Kandinsky6SROutLayer(nn.Module): + """Projects visual hidden states back to packed latent patches.""" + + def __init__(self, model_dim: int, time_dim: int, visual_dim: int, patch_size: tuple[int, int, int]): + super().__init__() + self.patch_size = patch_size + self.modulation = Kandinsky6SRModulation(time_dim, model_dim, 2) + self.norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.out_layer = nn.Linear(model_dim, math.prod(patch_size) * visual_dim) + + def forward(self, visual_embed: Tensor, time_embed: Tensor) -> Tensor: + shift, scale = torch.chunk(self.modulation(time_embed), 2, dim=-1) + condition_shape = (scale.shape[0],) + (1,) * (visual_embed.ndim - 2) + (scale.shape[-1],) + x = apply_scale_shift( + self.norm(visual_embed.float()), + visual_embed, + scale.reshape(condition_shape), + shift.reshape(condition_shape), + ) + x = self.out_layer(x) + + batch, duration, height, width = x.shape[:4] + p_t, p_h, p_w = self.patch_size + return ( + x.view(batch, duration, height, width, -1, p_t, p_h, p_w) + .permute(0, 1, 5, 2, 6, 3, 7, 4) + .flatten(1, 2) + .flatten(2, 3) + .flatten(3, 4) + ) + + +# Copied from diffusers.models.transformers.transformer_kandinsky6.Kandinsky6RoPE3D with Kandinsky6RoPE3D->Kandinsky6SRRoPE3D +class Kandinsky6SRRoPE3D(nn.Module): + """3-D Rotary Position Embedding — used for video spatial-temporal tokens (T, H, W).""" + + def __init__( + self, + axes_dims: tuple[int, int, int], + max_pos: tuple[int, int, int] = (128, 128, 128), + max_period: float = 10000.0, + ): + super().__init__() + self.axes_dims = axes_dims + self.max_pos = max_pos + self.max_period = max_period + for i, (d, mp) in enumerate(zip(axes_dims, max_pos)): + freq = get_freqs(d // 2, max_period) + self.register_buffer( + f"angles_{i}", torch.outer(torch.arange(mp, dtype=freq.dtype), freq), persistent=False + ) + + def forward( + self, + pos: tuple[Tensor, Tensor, Tensor], + scale_factor: tuple[float, float, float] = (1.0, 1.0, 1.0), + ) -> Tensor: + # `pos` holds one index tensor per axis; the grid size is implied by their lengths. + num_frames, height, width = (int(axis_pos.shape[0]) for axis_pos in pos) + angles_t = self.angles_0[pos[0]] / scale_factor[0] # (T, d//2) + angles_h = self.angles_1[pos[1]] / scale_factor[1] # (H, d//2) + angles_w = self.angles_2[pos[2]] / scale_factor[2] # (W, d//2) + + angles = torch.cat( + [ + angles_t.view(num_frames, 1, 1, -1).expand(num_frames, height, width, -1), + angles_h.view(1, height, 1, -1).expand(num_frames, height, width, -1), + angles_w.view(1, 1, width, -1).expand(num_frames, height, width, -1), + ], + dim=-1, + ) + cos, sin = torch.cos(angles), torch.sin(angles) + rope = torch.stack([cos, -sin, sin, cos], dim=-1) # (T, H, W, total_dim, 4) + rope = rope.view(*rope.shape[:-1], 2, 2) # (T, H, W, total_dim, 2, 2) + return rope.unsqueeze(-4) # (T, H, W, 1, total_dim, 2, 2) + + +class Kandinsky6SRTransformerBlock(nn.Module): + """AdaLN-modulated self-attention + feed-forward block of the SR transformer.""" + + def __init__(self, model_dim: int, time_dim: int, ff_dim: int, head_dim: int): + super().__init__() + self.visual_modulation = Kandinsky6SRModulation(time_dim, model_dim, 6) + self.self_attention_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.self_attention = Kandinsky6SRAttention(model_dim, head_dim) + self.feed_forward_norm = nn.LayerNorm(model_dim, elementwise_affine=False) + self.feed_forward = FeedForward(model_dim, inner_dim=ff_dim, activation_fn="gelu", bias=False) + + def forward( + self, + hidden_states: Tensor, + temb: Tensor, + rotary_emb: Tensor, + sparse_params: dict[str, Any], + ) -> Tensor: + self_attention_params, feed_forward_params = torch.chunk(self.visual_modulation(temb), 2, dim=-1) + shift, scale, gate = torch.chunk(self_attention_params, 3, dim=-1) + hidden_states = apply_gate_sum( + hidden_states, + self.self_attention( + apply_scale_shift(self.self_attention_norm(hidden_states.float()), hidden_states, scale, shift), + rotary_emb, + sparse_params, + ), + gate, + ) + shift, scale, gate = torch.chunk(feed_forward_params, 3, dim=-1) + return apply_gate_sum( + hidden_states, + self.feed_forward( + apply_scale_shift(self.feed_forward_norm(hidden_states.float()), hidden_states, scale, shift) + ), + gate, + ) + + +class Kandinsky6SRTransformer3DModel(ModelMixin, ConfigMixin, PeftAdapterMixin, AttentionMixin): + r""" + Text-free diffusion transformer for Kandinsky 6 video super-resolution. + + The model denoises tiles of the K-VAE latent video. Its input concatenates the noisy latent with the anchor latent + and the anchor mask that condition the super-resolution (`2 * in_visual_dim + 1` channels), and its output holds + `out_visual_dim` channels: `in_visual_dim` for a plain velocity checkpoint, or a widened `n_grid * in_visual_dim` + for the [`PiflowScheduler`] distilled checkpoints. Video self-attention runs through the NABLA sparse block pattern + on the `flex` attention backend, which needs the token grid (`height` and `width` after `patch_size`) to be + divisible by 8. + + Args: + in_visual_dim (`int`, defaults to `64`): + Number of latent channels of the K-VAE. + out_visual_dim (`int`, defaults to `640`): + Number of output channels. + time_dim (`int`, defaults to `512`): + Dimension of the timestep embedding. + patch_size (`tuple[int, int, int]`, defaults to `(1, 1, 1)`): + Patch size as `(temporal, height, width)`. + model_dim (`int`, defaults to `1792`): + Hidden dimension of the transformer. + ff_dim (`int`, defaults to `7168`): + Inner dimension of the feed-forward networks. + num_visual_blocks (`int`, defaults to `32`): + Number of transformer blocks. + axes_dims (`tuple[int, int, int]`, defaults to `(16, 24, 24)`): + RoPE dimensions per `(t, h, w)` axis; their sum is the attention head dimension. + scale_factor (`tuple[float, float, float]`, defaults to `(1.0, 2.0, 2.0)`): + Per-axis RoPE frequency scaling applied to the token positions. + nabla_threshold (`float`, defaults to `0.8`): + Cumulative-attention threshold of the NABLA block selection. + nabla_window (`tuple[int, int, int]`, defaults to `(11, 7, 7)`): + Odd `(t, h, w)` extents of the sliding-tile prior that every 8x8 token block always attends to. + tile_sizes (`tuple[tuple[int, int], ...]`, defaults to `((512, 512), (512, 768), (768, 512))`): + Pixel `(height, width)` sizes of the video tiles the model was trained on. [`Kandinsky6SRPipeline`] refines + every tile at the size whose aspect ratio is closest to the input video's. + """ + + _supports_gradient_checkpointing = True + _no_split_modules = ["Kandinsky6SRTransformerBlock"] + _repeated_blocks = ["Kandinsky6SRTransformerBlock"] + _skip_layerwise_casting_patterns = ["norm"] + # Timestep embeddings, the pooled-text bias they add to, and every AdaLN modulation projection stay float32 + # under `from_pretrained(torch_dtype=...)`. + _keep_in_fp32_modules = ["time_embeddings", "pooled_bias", "modulation"] + + @register_to_config + def __init__( + self, + in_visual_dim: int = 64, + out_visual_dim: int = 640, + time_dim: int = 512, + patch_size: tuple[int, int, int] = (1, 1, 1), + model_dim: int = 1792, + ff_dim: int = 7168, + num_visual_blocks: int = 32, + axes_dims: tuple[int, int, int] = (16, 24, 24), + scale_factor: tuple[float, float, float] = (1.0, 2.0, 2.0), + nabla_threshold: float = 0.8, + nabla_window: tuple[int, int, int] = (11, 7, 7), + tile_sizes: tuple[tuple[int, int], ...] = ((512, 512), (512, 768), (768, 512)), + ) -> None: + super().__init__() + if not _CAN_USE_FLEX_ATTN: + raise ImportError( + "Kandinsky6SRTransformer3DModel requires PyTorch>=2.5.0 with `torch.nn.attention.flex_attention`" + " for its NABLA sparse attention." + ) + head_dim = sum(axes_dims) + + self.time_embeddings = Kandinsky6SRTimeEmbeddings(model_dim, time_dim) + # The SR checkpoints were trained with an empty caption: the pooled-text projection of that caption is a + # constant, folded into this bias by the checkpoint conversion. + self.pooled_bias = nn.Parameter(torch.zeros(time_dim)) + self.visual_embeddings = Kandinsky6SRVisualEmbeddings(2 * in_visual_dim + 1, model_dim, patch_size) + self.visual_rope_embeddings = Kandinsky6SRRoPE3D(axes_dims) + self.visual_transformer_blocks = nn.ModuleList( + [Kandinsky6SRTransformerBlock(model_dim, time_dim, ff_dim, head_dim) for _ in range(num_visual_blocks)] + ) + self.out_layer = Kandinsky6SROutLayer(model_dim, time_dim, out_visual_dim, patch_size) + + self.gradient_checkpointing = False + + def forward( + self, + hidden_states: Tensor, + timestep: Tensor, + return_dict: bool = True, + ) -> Transformer2DModelOutput | tuple[Tensor]: + r""" + Args: + hidden_states (`torch.Tensor` of shape `(batch_size, num_frames, height, width, 2 * in_visual_dim + 1)`): + Latent tiles in the `(B, T, H, W, C)` layout: the noisy latent, the anchor latent and the anchor mask + concatenated along the channel axis. + timestep (`torch.Tensor` of shape `(batch_size,)`): + Diffusion timestep on the `[0, num_train_timesteps]` scale. + return_dict (`bool`, defaults to `True`): + Whether to return a [`~models.modeling_outputs.Transformer2DModelOutput`] instead of a plain tuple. + + Returns: + [`~models.modeling_outputs.Transformer2DModelOutput`] or `tuple`: + The prediction of shape `(batch_size, num_frames, height, width, out_visual_dim)`. + """ + checkpoint = torch.is_grad_enabled() and self.gradient_checkpointing + device = hidden_states.device + + temb = self.time_embeddings(timestep) + self.pooled_bias + + # 1. Patchify the latents and build the rotary embeddings of the token grid + visual_embed = self.visual_embeddings(hidden_states) + visual_shape = visual_embed.shape[1:4] + visual_rope_pos = tuple(torch.arange(size, device=device) for size in visual_shape) + visual_rope = self.visual_rope_embeddings(visual_rope_pos, self.config.scale_factor) + + # 2. Flatten the grid into a token sequence; NABLA groups 8x8 spatial neighbourhoods into attention blocks + num_frames, height, width = visual_shape + if height % FRACTAL_BLOCK_SIZE or width % FRACTAL_BLOCK_SIZE: + raise ValueError( + f"NABLA attention needs the token grid {(height, width)} to be divisible by {FRACTAL_BLOCK_SIZE}" + ) + group_size = (1, FRACTAL_BLOCK_SIZE, FRACTAL_BLOCK_SIZE) + visual_embed = _local_patch(visual_embed, visual_shape, group_size, dim=1).flatten(1, 2) + visual_rope = _local_patch(visual_rope, visual_shape, group_size, dim=0).flatten(0, 1) + sta_mask = sliding_tile_mask( + num_frames, height // FRACTAL_BLOCK_SIZE, width // FRACTAL_BLOCK_SIZE, self.config.nabla_window, device + ) + sparse_params = {"sta_mask": sta_mask, "threshold": self.config.nabla_threshold} + + # 3. Transformer blocks + for block in self.visual_transformer_blocks: + if checkpoint: + visual_embed = self._gradient_checkpointing_func(block, visual_embed, temb, visual_rope, sparse_params) + else: + visual_embed = block(visual_embed, temb, visual_rope, sparse_params) + + # 4. Restore the grid and project back to the latent space + visual_embed = _local_merge( + visual_embed.reshape(visual_embed.shape[0], -1, FRACTAL_BLOCK_SIZE**2, visual_embed.shape[-1]), + visual_shape, + group_size, + dim=1, + ) + output = self.out_layer(visual_embed, temb) + + if not return_dict: + return (output,) + return Transformer2DModelOutput(sample=output) diff --git a/src/diffusers/pipelines/__init__.py b/src/diffusers/pipelines/__init__.py index 96d10a709d94..b8cb626d8283 100644 --- a/src/diffusers/pipelines/__init__.py +++ b/src/diffusers/pipelines/__init__.py @@ -451,6 +451,12 @@ "Kandinsky5T2IPipeline", "Kandinsky5I2IPipeline", ] + _import_structure["kandinsky6"] = [ + "Kandinsky6SRPipeline", + "Kandinsky6SRPipelineOutput", + "Kandinsky6TI2VAPipeline", + "Kandinsky6TI2VAPipelineOutput", + ] _import_structure["z_image"] = [ "ZImageControlNetInpaintPipeline", "ZImageControlNetPipeline", @@ -781,6 +787,12 @@ Kandinsky5T2IPipeline, Kandinsky5T2VPipeline, ) + from .kandinsky6 import ( + Kandinsky6SRPipeline, + Kandinsky6SRPipelineOutput, + Kandinsky6TI2VAPipeline, + Kandinsky6TI2VAPipelineOutput, + ) from .krea2 import Krea2Pipeline from .latent_consistency_models import ( LatentConsistencyModelImg2ImgPipeline, diff --git a/src/diffusers/pipelines/kandinsky6/__init__.py b/src/diffusers/pipelines/kandinsky6/__init__.py new file mode 100644 index 000000000000..23a2c473afd0 --- /dev/null +++ b/src/diffusers/pipelines/kandinsky6/__init__.py @@ -0,0 +1,49 @@ +from typing import TYPE_CHECKING + +from ...utils import ( + DIFFUSERS_SLOW_IMPORT, + OptionalDependencyNotAvailable, + _LazyModule, + get_objects_from_module, + is_torch_available, + is_transformers_available, +) + + +_dummy_objects = {} +_import_structure = {} + +try: + if not (is_transformers_available() and is_torch_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ...utils import dummy_torch_and_transformers_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_objects)) +else: + _import_structure["pipeline_kandinsky6_sr"] = ["Kandinsky6SRPipeline"] + _import_structure["pipeline_kandinsky6_ti2va"] = ["Kandinsky6TI2VAPipeline"] + _import_structure["pipeline_output"] = ["Kandinsky6SRPipelineOutput", "Kandinsky6TI2VAPipelineOutput"] + +if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT: + try: + if not (is_transformers_available() and is_torch_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ...utils.dummy_torch_and_transformers_objects import * + else: + from .pipeline_kandinsky6_sr import Kandinsky6SRPipeline + from .pipeline_kandinsky6_ti2va import Kandinsky6TI2VAPipeline + from .pipeline_output import Kandinsky6SRPipelineOutput, Kandinsky6TI2VAPipelineOutput +else: + import sys + + sys.modules[__name__] = _LazyModule( + __name__, + globals()["__file__"], + _import_structure, + module_spec=__spec__, + ) + + for name, value in _dummy_objects.items(): + setattr(sys.modules[__name__], name, value) diff --git a/src/diffusers/pipelines/kandinsky6/pipeline_kandinsky6_sr.py b/src/diffusers/pipelines/kandinsky6/pipeline_kandinsky6_sr.py new file mode 100644 index 000000000000..12d33d62abb4 --- /dev/null +++ b/src/diffusers/pipelines/kandinsky6/pipeline_kandinsky6_sr.py @@ -0,0 +1,397 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import inspect +import math + +import numpy as np +import PIL.Image +import torch +import torch.nn.functional as F + +from ...models import Kandinsky6SRLatentUpscalerBank, Kandinsky6SRTransformer3DModel, Kandinsky6SRVAE +from ...schedulers import FlowMatchEulerDiscreteScheduler, PiflowScheduler +from ...utils import replace_example_docstring +from ...utils.torch_utils import randn_tensor +from ...video_processor import VideoProcessor +from ..pipeline_utils import DiffusionPipeline +from .pipeline_output import Kandinsky6SRPipelineOutput + + +EXAMPLE_DOC_STRING = """ + Examples: + ```python + >>> import torch + >>> from diffusers import Kandinsky6SRPipeline, Kandinsky6TI2VAPipeline + >>> from diffusers.utils import export_to_video + + >>> pipe = Kandinsky6TI2VAPipeline.from_pretrained( + ... "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers", torch_dtype=torch.bfloat16 + ... ) + >>> pipe.enable_model_cpu_offload() + >>> video = pipe( + ... prompt="A cat and a dog baking a cake together in a kitchen.", + ... height=480, + ... width=864, + ... num_inference_steps=16, + ... guidance_scale=1.0, + ... sample_audio=False, + ... ).frames[0] + + >>> sr_pipe = Kandinsky6SRPipeline.from_pretrained( + ... "kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers", torch_dtype=torch.bfloat16 + ... ) + >>> # The transformer always runs attention through the `flex` backend; compiling avoids the eager + >>> # fallback's much higher memory use at video resolutions. + >>> sr_pipe.transformer.compile_repeated_blocks(fullgraph=True) + >>> sr_pipe.enable_model_cpu_offload() + >>> output = sr_pipe(video=video, resolution_scale=2.25, num_inference_steps=2) + >>> export_to_video(output.frames[0], "output_sr.mp4", fps=24) + ``` +""" + + +# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps +def retrieve_timesteps( + scheduler, + num_inference_steps: int | None = None, + device: str | torch.device | None = None, + timesteps: list[int] | None = None, + sigmas: list[float] | None = None, + **kwargs, +): + r""" + Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles + custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`. + + Args: + scheduler (`SchedulerMixin`): + The scheduler to get timesteps from. + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps` + must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`list[int]`, *optional*): + Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed, + `num_inference_steps` and `sigmas` must be `None`. + sigmas (`list[float]`, *optional*): + Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed, + `num_inference_steps` and `timesteps` must be `None`. + + Returns: + `tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the + second element is the number of inference steps. + """ + if timesteps is not None and sigmas is not None: + raise ValueError("Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values") + if timesteps is not None: + accepts_timesteps = "timesteps" in set(inspect.signature(scheduler.set_timesteps).parameters.keys()) + if not accepts_timesteps: + raise ValueError( + f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom" + f" timestep schedules. Please check whether you are using the correct scheduler." + ) + scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs) + timesteps = scheduler.timesteps + num_inference_steps = len(timesteps) + elif sigmas is not None: + accept_sigmas = "sigmas" in set(inspect.signature(scheduler.set_timesteps).parameters.keys()) + if not accept_sigmas: + raise ValueError( + f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom" + f" sigmas schedules. Please check whether you are using the correct scheduler." + ) + scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs) + timesteps = scheduler.timesteps + num_inference_steps = len(timesteps) + else: + scheduler.set_timesteps(num_inference_steps, device=device, **kwargs) + timesteps = scheduler.timesteps + return timesteps, num_inference_steps + + +def _tile_positions(length: int, tile: int, min_overlap: float, snap: int) -> list[int]: + """Evenly spread, `snap`-aligned tile start positions covering `[0, length - tile]` with at least `min_overlap` + (a fraction of `tile`) shared between neighbours.""" + if tile >= length: + return [0] + span = (length - tile) // snap + max_stride = max(1, math.floor(tile * (1.0 - min_overlap) / snap)) + count = math.ceil(span / max_stride) + 1 + return [round(index * span / (count - 1)) * snap for index in range(count)] + + +def _hann_window_2d(height: int, width: int, device: torch.device) -> torch.Tensor: + """2D Hann window with non-zero borders, so a region covered by a single tile keeps a positive weight.""" + window_y = torch.hann_window(height + 2, device=device)[1:-1] + window_x = torch.hann_window(width + 2, device=device)[1:-1] + return window_y[:, None] * window_x[None, :] + + +class Kandinsky6SRPipeline(DiffusionPipeline): + r""" + Pipeline for video super-resolution with Kandinsky 6. + + The video is split into overlapping spatial tiles, every tile is refined by the SR transformer at one of the tile + sizes the model was trained on (`transformer.config.tile_sizes`), and the refined tiles are blended back with Hann + windows. When the pipeline has a `latent_upscaler`, the tiles are cut from the K-VAE latents of the whole video and + upscaled in latent space; otherwise the pixel tiles are bilinearly upscaled and encoded. + + This model inherits from [`DiffusionPipeline`]. Check the superclass documentation for the generic methods + implemented for all pipelines (downloading, saving, running on a particular device, etc.). + + Args: + transformer ([`Kandinsky6SRTransformer3DModel`]): + Transformer that refines the latent tiles. + vae ([`Kandinsky6SRVAE`]): + Causal video K-VAE used to encode the input video and decode the refined tiles. + scheduler ([`FlowMatchEulerDiscreteScheduler`] or [`PiflowScheduler`]): + Scheduler used with `transformer` to denoise the tiles. Distilled checkpoints ship with a + [`PiflowScheduler`]. + latent_upscaler ([`Kandinsky6SRLatentUpscalerBank`], *optional*): + Latent upscalers for the supported scales. + """ + + model_cpu_offload_seq = "latent_upscaler->transformer->vae" + _optional_components = ["latent_upscaler"] + + def __init__( + self, + transformer: Kandinsky6SRTransformer3DModel, + vae: Kandinsky6SRVAE, + scheduler: FlowMatchEulerDiscreteScheduler | PiflowScheduler, + latent_upscaler: Kandinsky6SRLatentUpscalerBank | None = None, + ) -> None: + super().__init__() + self.register_modules(transformer=transformer, vae=vae, scheduler=scheduler, latent_upscaler=latent_upscaler) + + self.vae_scale_factor_spatial = ( + self.vae.spatial_compression_ratio if getattr(self, "vae", None) is not None else 16 + ) + self.vae_scale_factor_temporal = ( + self.vae.temporal_compression_ratio if getattr(self, "vae", None) is not None else 4 + ) + self.transformer_tile_sizes = ( + tuple(tuple(size) for size in self.transformer.config.tile_sizes) + if getattr(self, "transformer", None) is not None + else ((512, 512), (512, 768), (768, 512)) + ) + self.video_processor = VideoProcessor(vae_scale_factor=self.vae_scale_factor_spatial) + + def check_inputs( + self, video, resolution_scale, num_inference_steps, lq_noise_scale, min_overlap, tiles_batch_size + ): + if resolution_scale not in (2, 2.25, 4): + raise ValueError(f"`resolution_scale` must be 2, 2.25 or 4 but is {resolution_scale}.") + if num_inference_steps < 1: + raise ValueError(f"`num_inference_steps` has to be positive but is {num_inference_steps}.") + if not 0.0 < lq_noise_scale <= 1.0: + raise ValueError(f"`lq_noise_scale` has to be in (0, 1] but is {lq_noise_scale}.") + if not 0.0 <= min_overlap < 1.0: + raise ValueError(f"`min_overlap` has to be in [0, 1) but is {min_overlap}.") + if tiles_batch_size < 1: + raise ValueError(f"`tiles_batch_size` has to be positive but is {tiles_batch_size}.") + + num_frames = video.shape[2] + if (num_frames - 1) % self.vae_scale_factor_temporal != 0: + raise ValueError( + f"`video` must have `1 + k * {self.vae_scale_factor_temporal}` frames but has {num_frames}." + ) + + def encode_video(self, video: torch.Tensor) -> torch.Tensor: + r""" + Encodes a `(batch_size, channels, num_frames, height, width)` video in `[-1, 1]` into K-VAE latents scaled by + the VAE `scaling_factor`. + """ + # The K-VAE was trained on `pixels / 128 - 1` rather than the `pixels / 127.5 - 1` of `VideoProcessor`. + video = (video.to(self.vae.dtype) + 1) * (127.5 / 128) - 1 + latents = self.vae.encode(video, return_dict=False)[0].mode() + return latents * self.vae.config.scaling_factor + + def decode_latents(self, latents: torch.Tensor) -> torch.Tensor: + r"""Decodes scaled K-VAE latents into a `(batch_size, channels, num_frames, height, width)` video in `[-1, 1]`.""" + video = self.vae.decode(latents.to(self.vae.dtype) / self.vae.config.scaling_factor, return_dict=False)[0] + return ((video.float() + 1) * (128 / 127.5) - 1).clamp(-1, 1) + + @torch.no_grad() + @replace_example_docstring(EXAMPLE_DOC_STRING) + def __call__( + self, + video: list[PIL.Image.Image] | list[list[PIL.Image.Image]] | np.ndarray | torch.Tensor, + resolution_scale: float = 2.25, + num_inference_steps: int = 4, + timesteps: list[int] | None = None, + sigmas: list[float] | None = None, + lq_noise_scale: float = 0.7, + min_overlap: float = 0.2, + tiles_batch_size: int = 1, + generator: torch.Generator | list[torch.Generator] | None = None, + output_type: str = "pil", + return_dict: bool = True, + ) -> Kandinsky6SRPipelineOutput | tuple: + r""" + The call function to the pipeline for super-resolution. + + Args: + video (`list[PIL.Image.Image]`, `np.ndarray` or `torch.Tensor`): + The low-resolution video(s), in any format [`~video_processor.VideoProcessor.preprocess_video`] + accepts, with `1 + k * 4` frames. Sizes are rounded down to a multiple of the VAE spatial factor. + resolution_scale (`float`, defaults to `2.25`): + Total spatial upscale: `2`, `4`, or `2.25` (a 1.125x bilinear pre-upscale followed by the 2x path). + num_inference_steps (`int`, defaults to `4`): + The number of denoising steps per tile. Use `2` with the distilled checkpoints. + timesteps (`list[int]`, *optional*): + Custom timesteps for schedulers that support them. + sigmas (`list[float]`, *optional*): + Custom sigmas for schedulers that support them. + lq_noise_scale (`float`, defaults to `0.7`): + Amount of Gaussian noise mixed into the low-resolution latents (variance preserving) before denoising. + min_overlap (`float`, defaults to `0.2`): + Minimum overlap between neighbouring tiles as a fraction of the tile size. + tiles_batch_size (`int`, defaults to `1`): + Number of tiles denoised per transformer call. + generator (`torch.Generator` or `list[torch.Generator]`, *optional*): + Generator(s) used for the noise mixed into the tiles. + output_type (`str`, defaults to `"pil"`): + The output format of the generated video: `"pil"`, `"np"` or `"pt"`. + return_dict (`bool`, defaults to `True`): + Whether or not to return a [`Kandinsky6SRPipelineOutput`] instead of a plain tuple. + + Examples: + + Returns: + [`Kandinsky6SRPipelineOutput`] or `tuple`: + The super-resolved video; a one-element tuple when `return_dict=False`. + """ + device = self._execution_device + dtype = self.transformer.dtype + + # 1. Preprocess the video and check inputs + video = self.video_processor.preprocess_video(video).to(device) + self.check_inputs(video, resolution_scale, num_inference_steps, lq_noise_scale, min_overlap, tiles_batch_size) + + # 2. The 2.25x route bilinearly pre-upscales the pixels by 1.125x before the 2x path + tiling_scale, pre_upscale = (2, 1.125) if resolution_scale == 2.25 else (int(resolution_scale), 1.0) + if pre_upscale != 1.0: + batch_size, channels, num_frames, height, width = video.shape + snap = self.vae_scale_factor_spatial + target = (round(height * pre_upscale / snap) * snap, round(width * pre_upscale / snap) * snap) + frames = video.permute(0, 2, 1, 3, 4).flatten(0, 1) + frames = F.interpolate(frames, size=target, mode="bilinear", align_corners=False) + video = frames.unflatten(0, (batch_size, num_frames)).permute(0, 2, 1, 3, 4) + batch_size, _, num_frames, height, width = video.shape + + if isinstance(generator, list) and len(generator) != batch_size: + raise ValueError( + f"You have passed a list of generators of length {len(generator)}, but requested an effective batch" + f" size of {batch_size}. Make sure the batch size matches the length of the generators." + ) + + # 3. Tile grid at the input resolution; every tile is refined at the closest trained tile resolution + base_height, base_width = min(self.transformer_tile_sizes, key=lambda hw: abs(hw[1] / hw[0] - width / height)) + snap = self.vae_scale_factor_spatial + if base_height % (snap * tiling_scale) or base_width % (snap * tiling_scale): + raise ValueError( + f"The tile size {(base_height, base_width)} must be divisible by the VAE spatial factor times the" + f" upscale factor ({snap * tiling_scale}) so that tiles align with the latent grid." + ) + tile_height, tile_width = base_height // tiling_scale, base_width // tiling_scale + if height < tile_height or width < tile_width: + raise ValueError( + f"`video` must be at least {tile_height}x{tile_width} pixels for `resolution_scale={resolution_scale}`," + f" got {height}x{width}." + ) + tops = _tile_positions(height, tile_height, min_overlap, snap) + lefts = _tile_positions(width, tile_width, min_overlap, snap) + tile_grid = [(top, left) for top in tops for left in lefts] + + # 4. Low-resolution latent tiles at the trained tile resolution + use_latent_upscaler = self.latent_upscaler is not None and tiling_scale in self.latent_upscaler.config.scales + if use_latent_upscaler: + latents = self.encode_video(video) + lq_tiles = [ + self.latent_upscaler( + latents[ + :, :, :, top // snap : (top + tile_height) // snap, left // snap : (left + tile_width) // snap + ], + scale=tiling_scale, + return_dict=False, + )[0] + for top, left in tile_grid + ] + else: + lq_tiles = [] + for top, left in tile_grid: + pixel_tile = video[:, :, :, top : top + tile_height, left : left + tile_width] + frames = pixel_tile.permute(0, 2, 1, 3, 4).flatten(0, 1) + frames = F.interpolate(frames, size=(base_height, base_width), mode="bilinear", align_corners=False) + pixel_tile = frames.unflatten(0, (batch_size, num_frames)).permute(0, 2, 1, 3, 4) + lq_tiles.append(self.encode_video(pixel_tile)) + lq_tiles = torch.stack(lq_tiles, dim=1).to(dtype) # (batch_size, num_tiles, channels, frames, height, width) + + # 5. Denoise the tiles and blend the decoded tiles into the output canvas + output_height, output_width = height * tiling_scale, width * tiling_scale + video_acc = torch.zeros((batch_size, 3, num_frames, output_height, output_width), device=device) + window = _hann_window_2d(base_height, base_width, device) + weight_acc = torch.zeros((1, 1, 1, output_height, output_width), device=device) + for top, left in tile_grid: + top, left = top * tiling_scale, left * tiling_scale + weight_acc[..., top : top + base_height, left : left + base_width] += window + num_chunks = math.ceil(len(tile_grid) / tiles_batch_size) + + with self.progress_bar(total=batch_size * num_chunks * num_inference_steps) as progress_bar: + for sample_index in range(batch_size): + sample_generator = generator[sample_index] if isinstance(generator, list) else generator + for start in range(0, len(tile_grid), tiles_batch_size): + tile_indices = range(start, min(start + tiles_batch_size, len(tile_grid))) + # The transformer works on `(batch, frames, height, width, channels)` tiles + lq_latents = lq_tiles[sample_index, list(tile_indices)].permute(0, 2, 3, 4, 1) + + # Variance-preserving noise mixed into the low-resolution latents is the starting point + noise = randn_tensor(lq_latents.shape, generator=sample_generator, device=device, dtype=dtype) + latents = math.sqrt(1 - lq_noise_scale**2) * lq_latents + lq_noise_scale * noise + + timesteps_, _ = retrieve_timesteps(self.scheduler, num_inference_steps, device, timesteps, sigmas) + for t in timesteps_: + # The SR transformer takes `[latent | anchor latent | anchor mask]`; the released checkpoints + # are anchor-free, so the anchor channels are zeros. + anchor = torch.zeros_like(latents) + anchor_mask = torch.zeros((*latents.shape[:-1], 1), dtype=dtype, device=device) + latent_model_input = torch.cat([latents, anchor, anchor_mask], dim=-1) + noise_pred = self.transformer( + hidden_states=latent_model_input, + timestep=t.expand(latents.shape[0]), + return_dict=False, + )[0] + latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0] + progress_bar.update() + + decoded = self.decode_latents(latents.permute(0, 4, 1, 2, 3)) + for tile, tile_index in zip(decoded, tile_indices): + top, left = tile_grid[tile_index] + top, left = top * tiling_scale, left * tiling_scale + video_acc[sample_index, :, :, top : top + base_height, left : left + base_width] += ( + tile * window + ) + + video = (video_acc / weight_acc).clamp(-1, 1) + video = self.video_processor.postprocess_video(video, output_type=output_type) + + # Offload all models + self.maybe_free_model_hooks() + + if not return_dict: + return (video,) + return Kandinsky6SRPipelineOutput(frames=video) diff --git a/src/diffusers/pipelines/kandinsky6/pipeline_kandinsky6_ti2va.py b/src/diffusers/pipelines/kandinsky6/pipeline_kandinsky6_ti2va.py new file mode 100644 index 000000000000..656f2077c47c --- /dev/null +++ b/src/diffusers/pipelines/kandinsky6/pipeline_kandinsky6_ti2va.py @@ -0,0 +1,962 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import copy +import inspect +import math +from collections.abc import Callable + +import PIL.Image +import torch +from transformers import CLIPTextModel, CLIPTokenizer, Qwen2_5_VLForConditionalGeneration, Qwen2_5_VLProcessor + +from ...image_processor import PipelineImageInput +from ...models import AutoencoderKLHunyuanVideo, Kandinsky6Transformer3DModel, MMAudioVAE, MMAudioVocoder +from ...schedulers import FlowMatchEulerDiscreteScheduler, PiflowScheduler +from ...utils import logging, replace_example_docstring +from ...utils.torch_utils import randn_tensor +from ...video_processor import VideoProcessor +from ..pipeline_utils import DiffusionPipeline +from .pipeline_output import Kandinsky6TI2VAPipelineOutput + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + +EXAMPLE_DOC_STRING = """ + Examples: + ```python + >>> import torch + >>> from diffusers import Kandinsky6TI2VAPipeline + >>> from diffusers.utils import encode_video + + >>> pipe = Kandinsky6TI2VAPipeline.from_pretrained( + ... "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers", torch_dtype=torch.bfloat16 + ... ) + >>> pipe.enable_model_cpu_offload() + + >>> output = pipe( + ... prompt="A cat and a dog baking a cake together in a kitchen.", + ... height=480, + ... width=864, + ... num_frames=121, + ... num_inference_steps=16, + ... guidance_scale=1.0, + ... ) + >>> encode_video( + ... output.frames[0], + ... fps=24, + ... output_path="output.mp4", + ... audio=output.audio[0][None], + ... audio_sample_rate=pipe.audio_sample_rate, + ... ) + ``` +""" + +_PROMPT_TEMPLATE = "\n".join( + [ + "<|im_start|>system\nYou are a promt engineer. Describe the video in detail.", + "Describe how the camera moves or shakes, describe the zoom and view angle, whether it follows the objects.", + "Describe the location of the video, main characters or objects and their action.", + "Describe the dynamism of the video and presented actions.", + "Name the visual style of the video: whether it is a professional footage, user generated content, " + "some kind of animation, video game or scren content.", + "Describe the visual effects, postprocessing and transitions if they are presented in the video.", + "Pay attention to the order of key actions shown in the scene.<|im_end|>", + "<|im_start|>user\n{}<|im_end|>", + ] +) +# Number of template tokens preceding the user prompt in the Qwen sequence. +_QWEN_CROP_START = 129 +_CLIP_MAX_LENGTH = 77 +_T2VA_EXPANSION_INSTRUCTION = ( + "You are a prompt beautifier that transforms short user video+audio descriptions into rich, detailed English " + "prompts specifically optimized for video+audio generation models. Preserve any direct speech between " + "and exactly as written. If the prompt asks for speech without exact words, add suitable direct speech " + "between those tags. Put general audio descriptions between and . Describe the scene, " + "actions, camera motion, visual style, and audio in detail. Make the prompt dynamic. Answer only with the " + "expanded prompt.\n\n" + "Rewrite Prompt: {}" +) +_I2VA_EXPANSION_INSTRUCTION = ( + "You are a prompt beautifier that transforms a short user video+audio description and a provided reference " + "image into a rich, detailed English prompt optimized for video+audio generation. The reference image is the " + "ground truth for the initial scene. Keep every visible fact that you mention consistent with it. Do not mainly " + "describe the image: focus on the requested actions, motion, interactions, camera changes, speech, and audio, " + "explaining the changes relative to the initial image. Add only details compatible with the reference image; " + "never invent conflicting objects, identities, colors, locations, or actions. Preserve direct speech between " + " and exactly. Put general audio descriptions between and . Make the prompt dynamic " + "and describe how the scene evolves from the provided image. Answer only with the expanded prompt.\n\n" + "Rewrite Prompt: {}" +) + + +# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps +def retrieve_timesteps( + scheduler, + num_inference_steps: int | None = None, + device: str | torch.device | None = None, + timesteps: list[int] | None = None, + sigmas: list[float] | None = None, + **kwargs, +): + r""" + Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles + custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`. + + Args: + scheduler (`SchedulerMixin`): + The scheduler to get timesteps from. + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps` + must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`list[int]`, *optional*): + Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed, + `num_inference_steps` and `sigmas` must be `None`. + sigmas (`list[float]`, *optional*): + Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed, + `num_inference_steps` and `timesteps` must be `None`. + + Returns: + `tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the + second element is the number of inference steps. + """ + if timesteps is not None and sigmas is not None: + raise ValueError("Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values") + if timesteps is not None: + accepts_timesteps = "timesteps" in set(inspect.signature(scheduler.set_timesteps).parameters.keys()) + if not accepts_timesteps: + raise ValueError( + f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom" + f" timestep schedules. Please check whether you are using the correct scheduler." + ) + scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs) + timesteps = scheduler.timesteps + num_inference_steps = len(timesteps) + elif sigmas is not None: + accept_sigmas = "sigmas" in set(inspect.signature(scheduler.set_timesteps).parameters.keys()) + if not accept_sigmas: + raise ValueError( + f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom" + f" sigmas schedules. Please check whether you are using the correct scheduler." + ) + scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs) + timesteps = scheduler.timesteps + num_inference_steps = len(timesteps) + else: + scheduler.set_timesteps(num_inference_steps, device=device, **kwargs) + timesteps = scheduler.timesteps + return timesteps, num_inference_steps + + +# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img.retrieve_latents +def retrieve_latents( + encoder_output: torch.Tensor, generator: torch.Generator | None = None, sample_mode: str = "sample" +): + if hasattr(encoder_output, "latent_dist") and sample_mode == "sample": + return encoder_output.latent_dist.sample(generator) + elif hasattr(encoder_output, "latent_dist") and sample_mode == "argmax": + return encoder_output.latent_dist.mode() + elif hasattr(encoder_output, "latents"): + return encoder_output.latents + else: + raise AttributeError("Could not access latents of provided encoder_output") + + +class Kandinsky6TI2VAPipeline(DiffusionPipeline): + r""" + Pipeline for text/image-to-video-and-audio generation with Kandinsky 6. + + Video and audio latents are denoised together by a single multimodal transformer, conditioned on Qwen2.5-VL text + tokens and a CLIP pooled embedding. An optional reference image conditions the first frame. + + This model inherits from [`DiffusionPipeline`]. Check the superclass documentation for the generic methods + implemented for all pipelines (downloading, saving, running on a particular device, etc.). + + Args: + transformer ([`Kandinsky6Transformer3DModel`]): + Multimodal transformer that denoises the video and audio latents. + vae ([`AutoencoderKLHunyuanVideo`]): + Video VAE used to encode the reference image and decode the generated video. + text_encoder ([`~transformers.Qwen2_5_VLForConditionalGeneration`]): + Qwen2.5-VL model providing the token-level text embeddings and, optionally, prompt expansion. + tokenizer ([`~transformers.Qwen2_5_VLProcessor`]): + Processor of `text_encoder`. + text_encoder_2 ([`~transformers.CLIPTextModel`]): + CLIP text encoder providing the pooled text embedding. + tokenizer_2 ([`~transformers.CLIPTokenizer`]): + Tokenizer of `text_encoder_2`. + scheduler ([`FlowMatchEulerDiscreteScheduler`] or [`PiflowScheduler`]): + Scheduler used with `transformer` to denoise the latents. Distilled checkpoints ship with a + [`PiflowScheduler`] and must be run with `guidance_scale=1.0`. + audio_vae ([`MMAudioVAE`], *optional*): + Audio VAE used to decode the generated audio latents into a mel spectrogram. Only needed when + `sample_audio=True`. + vocoder ([`MMAudioVocoder`], *optional*): + Vocoder used to turn the mel spectrogram `audio_vae` decodes into a waveform. Only needed when + `sample_audio=True`. + """ + + model_cpu_offload_seq = "text_encoder->text_encoder_2->transformer->vae->audio_vae->vocoder" + _optional_components = ["audio_vae", "vocoder"] + _callback_tensor_inputs = ["latents", "audio_latents", "prompt_embeds", "negative_prompt_embeds"] + _DEFAULT_NEGATIVE_PROMPT = ( + "Static, 2D cartoon, cartoon, 2d animation, paintings, images, " + "worst quality, low quality, ugly, deformed, walking backwards" + ) + + def __init__( + self, + transformer: Kandinsky6Transformer3DModel, + vae: AutoencoderKLHunyuanVideo, + text_encoder: Qwen2_5_VLForConditionalGeneration, + tokenizer: Qwen2_5_VLProcessor, + text_encoder_2: CLIPTextModel, + tokenizer_2: CLIPTokenizer, + scheduler: FlowMatchEulerDiscreteScheduler | PiflowScheduler, + audio_vae: MMAudioVAE | None = None, + vocoder: MMAudioVocoder | None = None, + ) -> None: + super().__init__() + self.register_modules( + transformer=transformer, + vae=vae, + text_encoder=text_encoder, + tokenizer=tokenizer, + text_encoder_2=text_encoder_2, + tokenizer_2=tokenizer_2, + scheduler=scheduler, + audio_vae=audio_vae, + vocoder=vocoder, + ) + + self.vae_scale_factor_spatial = ( + self.vae.config.spatial_compression_ratio if getattr(self, "vae", None) is not None else 8 + ) + self.vae_scale_factor_temporal = ( + self.vae.config.temporal_compression_ratio if getattr(self, "vae", None) is not None else 4 + ) + self.transformer_patch_size = ( + tuple(self.transformer.config.patch_size) if getattr(self, "transformer", None) is not None else (1, 2, 2) + ) + self.audio_sample_rate = ( + self.audio_vae.config.sample_rate if getattr(self, "audio_vae", None) is not None else 44_100 + ) + self.audio_latent_hop_length = ( + self.audio_vae.latent_hop_length if getattr(self, "audio_vae", None) is not None else 1024 + ) + self.video_processor = VideoProcessor(vae_scale_factor=self.vae_scale_factor_spatial) + + @staticmethod + def _get_prompt_embeds( + prompt: list[str], + tokenizer, + text_encoder, + tokenizer_2, + text_encoder_2, + max_sequence_length: int, + device: torch.device, + ) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor | None]: + """Encode prompts with Qwen2.5-VL (token embeddings) and CLIP (pooled embedding). + + Returns the token embeddings, the pooled embeddings and a boolean padding mask, which is `None` when no prompt + in the batch is padded (a mask without padding carries no information, and dropping it keeps every attention + backend available). + """ + inputs = tokenizer( + text=[_PROMPT_TEMPLATE.format(item) for item in prompt], + images=None, + videos=None, + max_length=max_sequence_length + _QWEN_CROP_START, + truncation=True, + return_tensors="pt", + padding="max_length", + ).to(device) + qwen_output = text_encoder( + input_ids=inputs["input_ids"], + attention_mask=inputs["attention_mask"], + return_dict=True, + output_hidden_states=True, + ) + prompt_embeds = qwen_output["hidden_states"][-1][:, _QWEN_CROP_START:] + prompt_attention_mask = inputs["attention_mask"][:, _QWEN_CROP_START:].to(dtype=torch.bool) + if prompt_attention_mask.all(): + prompt_attention_mask = None + + clip_inputs = tokenizer_2( + prompt, + max_length=_CLIP_MAX_LENGTH, + truncation=True, + add_special_tokens=True, + padding="max_length", + return_tensors="pt", + ).to(device) + pooled_prompt_embeds = text_encoder_2(**clip_inputs)["pooler_output"] + return prompt_embeds, pooled_prompt_embeds, prompt_attention_mask + + def encode_prompt( + self, + prompt: str | list[str], + negative_prompt: str | list[str] | None = None, + do_classifier_free_guidance: bool = True, + num_videos_per_prompt: int = 1, + prompt_embeds: torch.Tensor | None = None, + pooled_prompt_embeds: torch.Tensor | None = None, + prompt_attention_mask: torch.Tensor | None = None, + negative_prompt_embeds: torch.Tensor | None = None, + negative_pooled_prompt_embeds: torch.Tensor | None = None, + negative_prompt_attention_mask: torch.Tensor | None = None, + max_sequence_length: int = 1024, + device: torch.device | None = None, + dtype: torch.dtype | None = None, + ) -> tuple[torch.Tensor, ...]: + r""" + Encodes the prompt into text encoder hidden states. + + Args: + prompt (`str` or `list[str]`): + Prompt to be encoded. + negative_prompt (`str` or `list[str]`, *optional*): + The prompt not to guide the generation. Ignored when `do_classifier_free_guidance` is `False`. + do_classifier_free_guidance (`bool`, defaults to `True`): + Whether to also encode the negative prompt. + num_videos_per_prompt (`int`, defaults to `1`): + Number of videos generated per prompt; the embeddings are repeated accordingly. + prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated Qwen2.5-VL text embeddings. Skips encoding `prompt`. + pooled_prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated CLIP pooled text embeddings. Must be given together with `prompt_embeds`. + prompt_attention_mask (`torch.Tensor`, *optional*): + Boolean padding mask of `prompt_embeds`. + negative_prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated negative Qwen2.5-VL text embeddings. + negative_pooled_prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated negative CLIP pooled text embeddings. + negative_prompt_attention_mask (`torch.Tensor`, *optional*): + Boolean padding mask of `negative_prompt_embeds`. + max_sequence_length (`int`, defaults to `1024`): + Maximum number of prompt tokens after the chat template. + device (`torch.device`, *optional*): + Device to run the text encoders on. + dtype (`torch.dtype`, *optional*): + Dtype of the returned embeddings. + """ + device = device or self._execution_device + prompt = [prompt] if isinstance(prompt, str) else prompt + + if prompt_embeds is None: + prompt_embeds, pooled_prompt_embeds, prompt_attention_mask = self._get_prompt_embeds( + prompt, + self.tokenizer, + self.text_encoder, + self.tokenizer_2, + self.text_encoder_2, + max_sequence_length, + device, + ) + if do_classifier_free_guidance and negative_prompt_embeds is None: + negative_prompt = negative_prompt or self._DEFAULT_NEGATIVE_PROMPT + negative_prompt = [negative_prompt] if isinstance(negative_prompt, str) else negative_prompt + negative_prompt = negative_prompt * len(prompt) if len(negative_prompt) == 1 else negative_prompt + negative_prompt_embeds, negative_pooled_prompt_embeds, negative_prompt_attention_mask = ( + self._get_prompt_embeds( + negative_prompt, + self.tokenizer, + self.text_encoder, + self.tokenizer_2, + self.text_encoder_2, + max_sequence_length, + device, + ) + ) + + prompt_embeds = prompt_embeds.to(device=device, dtype=dtype).repeat_interleave(num_videos_per_prompt, dim=0) + pooled_prompt_embeds = pooled_prompt_embeds.to(device=device, dtype=dtype).repeat_interleave( + num_videos_per_prompt, dim=0 + ) + if prompt_attention_mask is not None: + prompt_attention_mask = prompt_attention_mask.to(device).repeat_interleave(num_videos_per_prompt, dim=0) + if do_classifier_free_guidance: + negative_prompt_embeds = negative_prompt_embeds.to(device=device, dtype=dtype).repeat_interleave( + num_videos_per_prompt, dim=0 + ) + negative_pooled_prompt_embeds = negative_pooled_prompt_embeds.to( + device=device, dtype=dtype + ).repeat_interleave(num_videos_per_prompt, dim=0) + if negative_prompt_attention_mask is not None: + negative_prompt_attention_mask = negative_prompt_attention_mask.to(device).repeat_interleave( + num_videos_per_prompt, dim=0 + ) + + return ( + prompt_embeds, + pooled_prompt_embeds, + prompt_attention_mask, + negative_prompt_embeds, + negative_pooled_prompt_embeds, + negative_prompt_attention_mask, + ) + + @staticmethod + def expand_prompts( + prompt: str | list[str], + tokenizer, + text_encoder, + device: torch.device, + image: PIL.Image.Image | list[PIL.Image.Image] | None = None, + max_sequence_length: int = 1024, + generator: torch.Generator | list[torch.Generator] | None = None, + ) -> str | list[str]: + r""" + Rewrites short prompts into detailed video+audio prompts with the Qwen2.5-VL text encoder, grounding them on + the reference image when one is given. A `staticmethod` so it can be used standalone, before running the + pipeline. + + Args: + prompt (`str` or `list[str]`): + Prompt or prompts to expand. + tokenizer: + The Qwen2.5-VL processor, e.g. `pipe.tokenizer`. + text_encoder: + The Qwen2.5-VL model, e.g. `pipe.text_encoder`. + device (`torch.device`): + Device to run the text encoder on. + image (`PIL.Image.Image` or `list[PIL.Image.Image]`, *optional*): + Reference image(s) of an image-to-video call. + max_sequence_length (`int`, defaults to `1024`): + Maximum number of generated tokens per prompt. + generator (`torch.Generator` or `list[torch.Generator]`, *optional*): + Seeds the sampled expansion; a list must match `prompt`'s length, one generator per item. `generate` + draws from the global RNG, so the global RNG is seeded from this generator's seed; later `randn_tensor` + calls keep using `generator` directly. + + Returns: + `str` or `list[str]`: The expanded prompt(s). + """ + if isinstance(prompt, list): + images = image if isinstance(image, list) else [image] * len(prompt) + generators = generator if isinstance(generator, list) else [generator] * len(prompt) + return [ + Kandinsky6TI2VAPipeline.expand_prompts( + item, + tokenizer, + text_encoder, + device, + image=item_image, + max_sequence_length=max_sequence_length, + generator=item_generator, + ) + for item, item_image, item_generator in zip(prompt, images, generators, strict=True) + ] + if image is not None and not isinstance(image, PIL.Image.Image): + raise ValueError("`expand_prompts` expects `image` as a `PIL.Image.Image`") + + instruction = (_I2VA_EXPANSION_INSTRUCTION if image is not None else _T2VA_EXPANSION_INSTRUCTION).format( + prompt + ) + content = [{"type": "image", "image": image}] if image is not None else [] + content.append({"type": "text", "text": instruction}) + text = tokenizer.apply_chat_template( + [{"role": "user", "content": content}], tokenize=False, add_generation_prompt=True + ) + inputs = tokenizer( + text=[text], + images=[image] if image is not None else None, + videos=None, + padding=True, + return_tensors="pt", + ).to(device) + if generator is not None: + torch.manual_seed(generator.initial_seed()) + generated = text_encoder.generate(**inputs, max_new_tokens=max_sequence_length) + generated = generated[:, inputs["input_ids"].shape[1] :] + return tokenizer.batch_decode(generated, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0] + + def check_inputs( + self, + prompt, + negative_prompt, + height, + width, + num_frames, + image, + sample_audio, + expand_prompts, + prompt_embeds=None, + pooled_prompt_embeds=None, + negative_prompt_embeds=None, + negative_pooled_prompt_embeds=None, + callback_on_step_end_tensor_inputs=None, + ): + spatial_multiple = self.vae_scale_factor_spatial * max(self.transformer_patch_size[1:]) + if height % spatial_multiple != 0 or width % spatial_multiple != 0: + raise ValueError( + f"`height` and `width` have to be divisible by {spatial_multiple} but are {height} and {width}." + ) + if num_frames < 1: + raise ValueError(f"`num_frames` has to be positive but is {num_frames}.") + + if callback_on_step_end_tensor_inputs is not None and not all( + k in self._callback_tensor_inputs for k in callback_on_step_end_tensor_inputs + ): + raise ValueError( + f"`callback_on_step_end_tensor_inputs` has to be in {self._callback_tensor_inputs}, but found {[k for k in callback_on_step_end_tensor_inputs if k not in self._callback_tensor_inputs]}" + ) + + if prompt is not None and prompt_embeds is not None: + raise ValueError( + f"Cannot forward both `prompt`: {prompt} and `prompt_embeds`: {prompt_embeds}. Please make sure to" + " only forward one of the two." + ) + elif prompt is None and prompt_embeds is None: + raise ValueError( + "Provide either `prompt` or `prompt_embeds`. Cannot leave both `prompt` and `prompt_embeds` undefined." + ) + elif prompt is not None and (not isinstance(prompt, str) and not isinstance(prompt, list)): + raise ValueError(f"`prompt` has to be of type `str` or `list` but is {type(prompt)}") + if expand_prompts and prompt_embeds is not None: + raise ValueError("`expand_prompts=True` requires `prompt`; it cannot be used with `prompt_embeds`.") + if negative_prompt is not None and negative_prompt_embeds is not None: + raise ValueError( + f"Cannot forward both `negative_prompt`: {negative_prompt} and `negative_prompt_embeds`:" + f" {negative_prompt_embeds}. Please make sure to only forward one of the two." + ) + if (prompt_embeds is None) != (pooled_prompt_embeds is None): + raise ValueError("`prompt_embeds` and `pooled_prompt_embeds` must be provided together.") + if (negative_prompt_embeds is None) != (negative_pooled_prompt_embeds is None): + raise ValueError("`negative_prompt_embeds` and `negative_pooled_prompt_embeds` must be provided together.") + + if sample_audio and (getattr(self, "audio_vae", None) is None or getattr(self, "vocoder", None) is None): + raise ValueError("`sample_audio=True` requires an `audio_vae` and a `vocoder`.") + if image is not None: + if not self.transformer.config.visual_cond: + raise ValueError("Image conditioning requires a transformer with `visual_cond=True`.") + if self.transformer.config.visual_token_type_num_embeddings < 2: + raise ValueError( + "Image conditioning requires a transformer with `visual_token_type_num_embeddings >= 2`." + ) + + def encode_image( + self, + image: PipelineImageInput, + height: int, + width: int, + device: torch.device, + dtype: torch.dtype, + num_videos_per_prompt: int = 1, + generator: torch.Generator | None = None, + ) -> torch.Tensor: + r""" + Encodes the reference image(s) into first-frame latents of shape `(batch_size, latent_height, latent_width, + latent_channels)`, scaled by the VAE `scaling_factor`. PIL images are resized and center-cropped to `height x + width`; tensors and arrays must already have that size. The latents are repeated `num_videos_per_prompt` times + along the batch dimension. + """ + is_pil = isinstance(image, PIL.Image.Image) or ( + isinstance(image, list) and isinstance(image[0], PIL.Image.Image) + ) + image = self.video_processor.preprocess( + image, height=height, width=width, resize_mode="crop" if is_pil else "default" + ) + image = image.to(device=device, dtype=self.vae.dtype).unsqueeze(2) + latents = retrieve_latents(self.vae.encode(image), generator=generator) * self.vae.config.scaling_factor + latents = latents[:, :, 0].permute(0, 2, 3, 1).to(dtype) + return latents.repeat_interleave(num_videos_per_prompt, dim=0) + + def prepare_latents( + self, + batch_size: int, + num_channels_latents: int, + height: int, + width: int, + num_frames: int, + dtype: torch.dtype, + device: torch.device, + generator: torch.Generator | list[torch.Generator] | None, + latents: torch.Tensor | None = None, + ) -> torch.Tensor: + r"""Returns video latents in the transformer's `(batch_size, num_frames, height, width, channels)` layout. + A user-provided `latents` tensor is expected in the `(batch_size, channels, num_frames, height, width)` layout. + """ + num_latent_frames = (num_frames - 1) // self.vae_scale_factor_temporal + 1 + latent_height = height // self.vae_scale_factor_spatial + latent_width = width // self.vae_scale_factor_spatial + if latents is not None: + return latents.to(device=device, dtype=dtype).permute(0, 2, 3, 4, 1) + + if isinstance(generator, list) and len(generator) != batch_size: + raise ValueError( + f"You have passed a list of generators of length {len(generator)}, but requested an effective batch" + f" size of {batch_size}. Make sure the batch size matches the length of the generators." + ) + shape = (batch_size, num_latent_frames, latent_height, latent_width, num_channels_latents) + return randn_tensor(shape, generator=generator, device=device, dtype=dtype) + + def prepare_audio_latents( + self, + batch_size: int, + num_channels_latents: int, + audio_length: int, + dtype: torch.dtype, + device: torch.device, + generator: torch.Generator | list[torch.Generator] | None, + audio_latents: torch.Tensor | None = None, + ) -> torch.Tensor: + r"""Returns audio latents in the transformer's `(batch_size, audio_length, channels)` layout. A user-provided + `audio_latents` tensor is expected in the `(batch_size, channels, audio_length)` layout.""" + if audio_latents is not None: + return audio_latents.to(device=device, dtype=dtype).permute(0, 2, 1) + shape = (batch_size, audio_length, num_channels_latents) + return randn_tensor(shape, generator=generator, device=device, dtype=dtype) + + @property + def guidance_scale(self): + return self._guidance_scale + + @property + def do_classifier_free_guidance(self): + return self._guidance_scale > 1.0 + + @property + def num_timesteps(self): + return self._num_timesteps + + @property + def current_timestep(self): + return self._current_timestep + + @property + def interrupt(self): + return self._interrupt + + @torch.no_grad() + @replace_example_docstring(EXAMPLE_DOC_STRING) + def __call__( + self, + prompt: str | list[str] | None = None, + image: PipelineImageInput | None = None, + negative_prompt: str | list[str] | None = None, + height: int = 512, + width: int = 768, + num_frames: int = 121, + frame_rate: float = 24.0, + num_inference_steps: int = 50, + timesteps: list[int] | None = None, + sigmas: list[float] | None = None, + guidance_scale: float = 5.0, + num_videos_per_prompt: int = 1, + generator: torch.Generator | list[torch.Generator] | None = None, + latents: torch.Tensor | None = None, + audio_latents: torch.Tensor | None = None, + prompt_embeds: torch.Tensor | None = None, + pooled_prompt_embeds: torch.Tensor | None = None, + negative_prompt_embeds: torch.Tensor | None = None, + negative_pooled_prompt_embeds: torch.Tensor | None = None, + sample_audio: bool = True, + expand_prompts: bool = False, + max_sequence_length: int = 1024, + output_type: str = "pil", + return_dict: bool = True, + callback_on_step_end: Callable[[int, int, dict], None] | None = None, + callback_on_step_end_tensor_inputs: list[str] = ["latents"], + ) -> Kandinsky6TI2VAPipelineOutput | tuple: + r""" + The call function to the pipeline for generation. + + Args: + prompt (`str` or `list[str]`, *optional*): + The prompt or prompts to guide the generation. Required unless `prompt_embeds` is given. + image (`PipelineImageInput`, *optional*): + Reference image(s) conditioning the first frame (image-to-video-and-audio). + negative_prompt (`str` or `list[str]`, *optional*): + The prompt or prompts not to guide the generation. Defaults to the Kandinsky 6 negative prompt. + height (`int`, defaults to `512`): + Height of the generated video in pixels. + width (`int`, defaults to `768`): + Width of the generated video in pixels. + num_frames (`int`, defaults to `121`): + Number of generated frames. + frame_rate (`float`, defaults to `24.0`): + Frame rate the video is generated at; sets the length of the synchronized audio. + num_inference_steps (`int`, defaults to `50`): + The number of denoising steps. Use `16` with the distilled checkpoints. + timesteps (`list[int]`, *optional*): + Custom timesteps for schedulers that support them. + sigmas (`list[float]`, *optional*): + Custom sigmas for schedulers that support them. + guidance_scale (`float`, defaults to `5.0`): + Classifier-free guidance scale. Must be `1.0` with a [`PiflowScheduler`]. + num_videos_per_prompt (`int`, defaults to `1`): + The number of videos to generate per prompt. + generator (`torch.Generator` or `list[torch.Generator]`, *optional*): + Generator(s) used for the initial noise and the reference image encoding. + latents (`torch.Tensor`, *optional*): + Pre-generated video latents of shape `(batch_size, channels, num_latent_frames, latent_height, + latent_width)`. + audio_latents (`torch.Tensor`, *optional*): + Pre-generated audio latents of shape `(batch_size, channels, audio_length)`. + prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated Qwen2.5-VL text embeddings. + pooled_prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated CLIP pooled text embeddings. + negative_prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated negative Qwen2.5-VL text embeddings. + negative_pooled_prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated negative CLIP pooled text embeddings. + sample_audio (`bool`, defaults to `True`): + Whether to generate synchronized audio. Requires the pipeline to have an `audio_vae` and a `vocoder`. + expand_prompts (`bool`, defaults to `False`): + Whether to rewrite the prompts with [`~Kandinsky6TI2VAPipeline.expand_prompts`] before encoding. + max_sequence_length (`int`, defaults to `1024`): + Maximum number of prompt tokens after the chat template. + output_type (`str`, defaults to `"pil"`): + The output format of the generated video: `"pil"`, `"np"`, `"pt"` or `"latent"`. + return_dict (`bool`, defaults to `True`): + Whether or not to return a [`Kandinsky6TI2VAPipelineOutput`] instead of a plain tuple. + callback_on_step_end (`Callable`, *optional*): + A function called at the end of each denoising step with `callback_on_step_end(self, step, timestep, + callback_kwargs)`. It may return a dict overriding the listed tensors. + callback_on_step_end_tensor_inputs (`list[str]`, defaults to `["latents"]`): + Tensor inputs passed to `callback_on_step_end`; a subset of `_callback_tensor_inputs`. + + Examples: + + Returns: + [`Kandinsky6TI2VAPipelineOutput`] or `tuple`: + The generated video and audio; a `(frames, audio)` tuple when `return_dict=False`. + """ + # 1. Check inputs. Raise error if not correct + self.check_inputs( + prompt=prompt, + negative_prompt=negative_prompt, + height=height, + width=width, + num_frames=num_frames, + image=image, + sample_audio=sample_audio, + expand_prompts=expand_prompts, + prompt_embeds=prompt_embeds, + pooled_prompt_embeds=pooled_prompt_embeds, + negative_prompt_embeds=negative_prompt_embeds, + negative_pooled_prompt_embeds=negative_pooled_prompt_embeds, + callback_on_step_end_tensor_inputs=callback_on_step_end_tensor_inputs, + ) + if num_frames % self.vae_scale_factor_temporal != 1: + logger.warning( + f"`num_frames - 1` has to be divisible by {self.vae_scale_factor_temporal}. Rounding to the nearest number." + ) + num_frames = num_frames // self.vae_scale_factor_temporal * self.vae_scale_factor_temporal + 1 + num_frames = max(num_frames, 1) + + self._guidance_scale = guidance_scale + self._current_timestep = None + self._interrupt = False + + # 2. Define call parameters + if prompt is not None and isinstance(prompt, str): + prompt = [prompt] + batch_size = len(prompt) if prompt is not None else prompt_embeds.shape[0] + device = self._execution_device + dtype = self.transformer.dtype + + # 3. Encode input prompt + if expand_prompts: + prompt = self.expand_prompts( + prompt, + self.tokenizer, + self.text_encoder, + device, + image=image, + max_sequence_length=max_sequence_length, + generator=generator, + ) + ( + prompt_embeds, + pooled_prompt_embeds, + prompt_attention_mask, + negative_prompt_embeds, + negative_pooled_prompt_embeds, + negative_prompt_attention_mask, + ) = self.encode_prompt( + prompt=prompt, + negative_prompt=negative_prompt, + do_classifier_free_guidance=self.do_classifier_free_guidance, + num_videos_per_prompt=num_videos_per_prompt, + prompt_embeds=prompt_embeds, + pooled_prompt_embeds=pooled_prompt_embeds, + negative_prompt_embeds=negative_prompt_embeds, + negative_pooled_prompt_embeds=negative_pooled_prompt_embeds, + max_sequence_length=max_sequence_length, + device=device, + dtype=dtype, + ) + + # 4. Encode the reference image + first_frame_latents = None + if image is not None: + first_frame_latents = self.encode_image( + image, height, width, device, dtype, num_videos_per_prompt, generator + ) + + # 5. Prepare timesteps. Audio uses a second scheduler instance so that both modalities keep their own step + # counter. + timesteps, num_inference_steps = retrieve_timesteps( + self.scheduler, num_inference_steps, device, timesteps, sigmas + ) + audio_scheduler = copy.deepcopy(self.scheduler) if sample_audio else None + self._num_timesteps = len(timesteps) + + # 6. Prepare latent variables + batch_size = batch_size * num_videos_per_prompt + latents = self.prepare_latents( + batch_size, + self.transformer.config.in_visual_dim, + height, + width, + num_frames, + dtype, + device, + generator, + latents, + ) + num_latent_frames = latents.shape[1] + if sample_audio: + audio_length = math.ceil( + ((num_latent_frames - 1) * self.vae_scale_factor_temporal + 1) + / frame_rate + * self.audio_sample_rate + / self.audio_latent_hop_length + ) + audio_latents = self.prepare_audio_latents( + batch_size, self.transformer.config.in_audio_dim, audio_length, dtype, device, generator, audio_latents + ) + else: + audio_latents = None + + # Image conditioning appends the clean reference frame as an extra, masked frame that reuses the first + # frame's rotary position and carries token type `1`. + tail_cond = image is not None + visual_token_type_ids = None + visual_rope_pos = None + if tail_cond: + latents = torch.cat([latents, first_frame_latents[:, None]], dim=1) + visual_token_type_ids = torch.zeros((batch_size, num_latent_frames + 1), dtype=torch.long, device=device) + visual_token_type_ids[:, -1] = 1 + patch_t, patch_h, patch_w = self.transformer_patch_size + visual_rope_pos = ( + torch.cat( + [ + torch.arange(num_latent_frames // patch_t, device=device), + torch.zeros(1, dtype=torch.long, device=device), + ] + ), + torch.arange(latents.shape[2] // patch_h, device=device), + torch.arange(latents.shape[3] // patch_w, device=device), + ) + + # 7. Denoising loop + with self.progress_bar(total=num_inference_steps) as progress_bar: + for i, t in enumerate(timesteps): + if self.interrupt: + continue + self._current_timestep = t + timestep = t.expand(batch_size) + + # Visual conditioning channels: [latent | conditioning latent | mask]. The conditioning-latent + # channel is unused (always zero) and only kept to match the transformer's fixed input width; the + # reference frame itself is appended as an extra, masked tail frame (see `tail_cond` above). + latent_model_input = latents + if self.transformer.config.visual_cond: + cond_latents = torch.zeros_like(latents) + cond_mask = torch.zeros((*latents.shape[:-1], 1), dtype=latents.dtype, device=device) + if first_frame_latents is not None: + latents[:, -1] = first_frame_latents + cond_mask[:, -1] = 1 + latent_model_input = torch.cat([latents, cond_latents, cond_mask], dim=-1) + + with self.transformer.cache_context("cond"): + noise_pred = self.transformer( + hidden_states=latent_model_input, + audio_hidden_states=audio_latents, + encoder_hidden_states=prompt_embeds, + pooled_projections=pooled_prompt_embeds, + timestep=timestep, + visual_rope_pos=visual_rope_pos, + encoder_attention_mask=prompt_attention_mask, + visual_token_type_ids=visual_token_type_ids, + return_dict=False, + ) + if self.do_classifier_free_guidance: + with self.transformer.cache_context("uncond"): + noise_pred_uncond = self.transformer( + hidden_states=latent_model_input, + audio_hidden_states=audio_latents, + encoder_hidden_states=negative_prompt_embeds, + pooled_projections=negative_pooled_prompt_embeds, + timestep=timestep, + visual_rope_pos=visual_rope_pos, + encoder_attention_mask=negative_prompt_attention_mask, + visual_token_type_ids=visual_token_type_ids, + return_dict=False, + ) + noise_pred = tuple( + uncond + self.guidance_scale * (cond - uncond) + for cond, uncond in zip(noise_pred, noise_pred_uncond) + ) + + latents = self.scheduler.step(noise_pred[0], t, latents, return_dict=False)[0] + if sample_audio: + audio_latents = audio_scheduler.step(noise_pred[1], t, audio_latents, return_dict=False)[0] + + if callback_on_step_end is not None: + callback_kwargs = {} + for k in callback_on_step_end_tensor_inputs: + callback_kwargs[k] = locals()[k] + callback_outputs = callback_on_step_end(self, i, t, callback_kwargs) + latents = callback_outputs.pop("latents", latents) + audio_latents = callback_outputs.pop("audio_latents", audio_latents) + prompt_embeds = callback_outputs.pop("prompt_embeds", prompt_embeds) + negative_prompt_embeds = callback_outputs.pop("negative_prompt_embeds", negative_prompt_embeds) + + progress_bar.update() + + self._current_timestep = None + + # 8. Drop the appended tail frame used for reference-image conditioning + if tail_cond: + latents = latents[:, :-1] + + # 9. Decode + latents = latents.permute(0, 4, 1, 2, 3) + audio_latents = audio_latents.permute(0, 2, 1) if sample_audio else None + if output_type == "latent": + video, audio = latents, audio_latents + else: + video = self.vae.decode(latents.to(self.vae.dtype) / self.vae.config.scaling_factor, return_dict=False)[0] + video = self.video_processor.postprocess_video(video, output_type=output_type) + audio = None + if sample_audio: + audio_latents = audio_latents.to(self.audio_vae.dtype) / self.audio_vae.config.scaling_factor + mel = self.audio_vae.decode(audio_latents, return_dict=False)[0] + audio = self.vocoder(mel.to(self.vocoder.dtype), return_dict=False)[0][:, 0].float() + if output_type == "np": + audio = audio.cpu().numpy() + + # Offload all models + self.maybe_free_model_hooks() + + if not return_dict: + return (video, audio) + return Kandinsky6TI2VAPipelineOutput(frames=video, audio=audio) diff --git a/src/diffusers/pipelines/kandinsky6/pipeline_output.py b/src/diffusers/pipelines/kandinsky6/pipeline_output.py new file mode 100644 index 000000000000..e626995ed257 --- /dev/null +++ b/src/diffusers/pipelines/kandinsky6/pipeline_output.py @@ -0,0 +1,57 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from dataclasses import dataclass + +import numpy as np +import PIL.Image +import torch + +from ...utils import BaseOutput + + +@dataclass +class Kandinsky6TI2VAPipelineOutput(BaseOutput): + r""" + Output class for [`Kandinsky6TI2VAPipeline`]. + + Args: + frames (`torch.Tensor`, `np.ndarray`, or `list[list[PIL.Image.Image]]`): + The generated video. A nested list of length `batch_size` holding `num_frames` PIL images each, or a NumPy + array or torch tensor of shape `(batch_size, num_frames, height, width, channels)` / `(batch_size, + num_frames, channels, height, width)`. With `output_type="latent"`, the video latents of shape + `(batch_size, channels, num_latent_frames, latent_height, latent_width)`. + audio (`torch.Tensor` or `np.ndarray`, *optional*): + The generated waveforms of shape `(batch_size, num_samples)` in `[-1, 1]` at the audio VAE's sample rate, + or `None` when audio was not sampled. With `output_type="latent"`, the audio latents of shape `(batch_size, + channels, audio_length)`. + """ + + frames: torch.Tensor | np.ndarray | list[list[PIL.Image.Image]] + audio: torch.Tensor | np.ndarray | None = None + + +@dataclass +class Kandinsky6SRPipelineOutput(BaseOutput): + r""" + Output class for [`Kandinsky6SRPipeline`]. + + Args: + frames (`torch.Tensor`, `np.ndarray`, or `list[list[PIL.Image.Image]]`): + The super-resolved video. A nested list of length `batch_size` holding `num_frames` PIL images each, or a + NumPy array or torch tensor of shape `(batch_size, num_frames, height, width, channels)` / `(batch_size, + num_frames, channels, height, width)`. + """ + + frames: torch.Tensor | np.ndarray | list[list[PIL.Image.Image]] diff --git a/src/diffusers/schedulers/__init__.py b/src/diffusers/schedulers/__init__.py index c0e46ef445df..47f4a0857090 100644 --- a/src/diffusers/schedulers/__init__.py +++ b/src/diffusers/schedulers/__init__.py @@ -73,6 +73,7 @@ _import_structure["scheduling_lcm"] = ["LCMScheduler"] _import_structure["scheduling_ltx_euler_ancestral_rf"] = ["LTXEulerAncestralRFScheduler"] _import_structure["scheduling_minimax_h3"] = ["MiniMaxH3Scheduler"] + _import_structure["scheduling_piflow"] = ["PiflowScheduler"] _import_structure["scheduling_pndm"] = ["PNDMScheduler"] _import_structure["scheduling_repaint"] = ["RePaintScheduler"] _import_structure["scheduling_sasolver"] = ["SASolverScheduler"] @@ -157,6 +158,7 @@ from .scheduling_lcm import LCMScheduler from .scheduling_ltx_euler_ancestral_rf import LTXEulerAncestralRFScheduler from .scheduling_minimax_h3 import MiniMaxH3Scheduler + from .scheduling_piflow import PiflowScheduler from .scheduling_pndm import PNDMScheduler from .scheduling_repaint import RePaintScheduler from .scheduling_sasolver import SASolverScheduler diff --git a/src/diffusers/schedulers/scheduling_piflow.py b/src/diffusers/schedulers/scheduling_piflow.py new file mode 100644 index 000000000000..d858b425a9fd --- /dev/null +++ b/src/diffusers/schedulers/scheduling_piflow.py @@ -0,0 +1,358 @@ +# Copyright 2026 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by the π-Flow reference implementation at +# https://github.com/Lakonik/LakonLab (https://huggingface.co/papers/2510.14974) + +"""Diffusers scheduler for distilled Kandinsky 6 PiFlow checkpoints.""" + +from dataclasses import dataclass + +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from .scheduling_utils import SchedulerMixin + + +@dataclass +class PiflowSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor`): + Computed sample at the next PiFlow grid point. Should be used as the next denoising input. + """ + + prev_sample: torch.Tensor + + +class DXPolicy: + """Network-free DX policy over one flow-matching segment.""" + + def __init__( + self, + denoising_output: torch.Tensor, + x_t_src: torch.Tensor, + sigma_t_src: torch.Tensor, + segment_size: float | torch.Tensor = 1.0, + shift: float = 1.0, + mode: str = "grid", + eps: float = 1e-4, + ) -> None: + self.ndim = x_t_src.dim() + self.shift = shift + self.eps = eps + if mode not in ("grid", "polynomial"): + raise ValueError(f"Unknown mode: {mode}") + self.mode = mode + + sigma_t_src = sigma_t_src.reshape(*sigma_t_src.size(), *((self.ndim - sigma_t_src.dim()) * [1])) + self.raw_t_src = self._unwarp_t(sigma_t_src) + segment = segment_size + if isinstance(segment, torch.Tensor) and segment.dim() < self.raw_t_src.dim(): + segment = segment.reshape(*segment.size(), *((self.raw_t_src.dim() - segment.dim()) * [1])) + self.raw_t_dst = (self.raw_t_src - segment).clamp(min=0) + self.segment_size = (self.raw_t_src - self.raw_t_dst).clamp(min=eps) + self.denoising_output_x_0 = x_t_src.unsqueeze(1) - sigma_t_src.unsqueeze(1) * denoising_output + + @staticmethod + def _interpolate(x: torch.Tensor, t: torch.Tensor) -> torch.Tensor: + n = x.size(1) + if n < 2: + return x.squeeze(1) + t = t.clamp(min=0, max=1) * (n - 1) + t0 = t.floor().to(torch.long).clamp(min=0, max=n - 2) + t1 = t0 + 1 + indices = torch.stack([t0, t1], dim=1) + values = torch.gather(x, dim=1, index=indices.expand(-1, -1, *x.shape[2:])) + return (t1 - t) * values[:, 0] + (t - t0) * values[:, 1] + + def _unwarp_t(self, sigma_t: torch.Tensor) -> torch.Tensor: + return sigma_t / (self.shift + (1 - self.shift) * sigma_t) + + def pi(self, x_t: torch.Tensor, sigma_t: torch.Tensor) -> torch.Tensor: + sigma_t = sigma_t.reshape(*sigma_t.size(), *((self.ndim - sigma_t.dim()) * [1])) + raw_t = self._unwarp_t(sigma_t) + if self.mode == "grid": + x_0 = self._interpolate( + self.denoising_output_x_0, + (raw_t - self.raw_t_dst) / self.segment_size, + ) + else: + p_order = self.denoising_output_x_0.size(1) + diff_t = self.raw_t_src - raw_t + basis = torch.stack([diff_t**i for i in range(p_order)], dim=1) + x_0 = torch.sum(basis * self.denoising_output_x_0, dim=1) + return (x_t - x_0) / sigma_t.clamp(min=self.eps) + + +def shift_timesteps(t: torch.Tensor, shift: float) -> torch.Tensor: + """Map raw flow-matching time to the shifted DiT time.""" + return shift * t / (1 + (shift - 1) * t) + + +def policy_rollout_fm( + x_t_start: torch.Tensor, + sigma_t_start: torch.Tensor, + raw_t_start: torch.Tensor, + raw_t_end: torch.Tensor, + total_substeps: int, + policy: DXPolicy, +) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]: + """Integrate ``policy.pi`` from ``raw_t_start`` to ``raw_t_end``.""" + num_batches = x_t_start.size(0) + ndim = x_t_start.dim() + shape = (num_batches, *((ndim - 1) * [1])) + raw_t_start = raw_t_start.reshape(shape) + raw_t_end = raw_t_end.reshape(shape) + sigma_t = sigma_t_start.reshape(shape) + + delta_raw_t = raw_t_start - raw_t_end + num_substeps = (delta_raw_t * total_substeps).round().to(torch.long).clamp(min=1) + substep_size = delta_raw_t / num_substeps + max_num_substeps = num_substeps.max() + + raw_t = raw_t_start + x_t = x_t_start + for substep_id in range(max_num_substeps.item()): + velocity = policy.pi(x_t, sigma_t) + raw_t_minus = (raw_t - substep_size).clamp(min=0) + sigma_t_minus = shift_timesteps(raw_t_minus, policy.shift) + x_t_minus = x_t + velocity * (sigma_t_minus - sigma_t) + + active_mask = num_substeps > substep_id + x_t = torch.where(active_mask, x_t_minus, x_t) + sigma_t = torch.where(active_mask, sigma_t_minus, sigma_t) + raw_t = torch.where(active_mask, raw_t_minus, raw_t) + + return x_t, sigma_t, sigma_t.flatten() * 1_000 + + +class PiflowScheduler(SchedulerMixin, ConfigMixin): + """Few-step PiFlow scheduler for widened-output diffusion transformers. + + PiFlow evaluates the denoising model at a small number of grid points and integrates a network-free policy between + those evaluations. The scheduler is intended for distilled Kandinsky 6 checkpoints, including the main video/audio + model and the video super-resolution model. Their model output contains `n_grid` predictions per sample channel. + + This scheduler inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the + generic methods implemented for all schedulers (loading, saving, etc.). + + Args: + num_train_timesteps (`int`, *optional*, defaults to 1000): Number of + training diffusion steps. + shift (`float`, *optional*, defaults to 5.0): Flow-matching timestep shift. + n_grid (`int`, *optional*, defaults to 10): Number of predictions in the + widened model output. + eps (`float`, *optional*, defaults to 1e-6): Minimum timestep and policy denominator. + final_step_size_scale (`float`, *optional*, defaults to 0.5): Relative + size of the final raw-timestep segment. + num_policy_substeps (`int`, *optional*, defaults to 128): Maximum policy + integration substeps per raw-timestep unit. + """ + + _compatibles = [] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + shift: float = 5.0, + n_grid: int = 10, + eps: float = 1e-6, + final_step_size_scale: float = 0.5, + num_policy_substeps: int = 128, + ) -> None: + if n_grid < 2: + raise ValueError(f"PiflowScheduler requires n_grid >= 2, got {n_grid}") + if eps <= 0: + raise ValueError(f"PiflowScheduler requires eps > 0, got {eps}") + if not 0 < final_step_size_scale <= 1: + raise ValueError("PiflowScheduler requires 0 < final_step_size_scale <= 1") + if num_policy_substeps < 1: + raise ValueError("PiflowScheduler requires num_policy_substeps >= 1") + + self._step_index = None + self._begin_index = None + self.timesteps = torch.empty(0) + self.sigmas = torch.empty(0) + self.n_grid = int(n_grid) + self.eps = float(eps) + self.final_step_size_scale = float(final_step_size_scale) + self.num_policy_substeps = int(num_policy_substeps) + self._piflow_raw_timesteps = torch.empty(0) + + @property + def step_index(self): + """The index counter for the current timestep. It increases by 1 after each scheduler step.""" + return self._step_index + + @property + def begin_index(self): + """The index for the first timestep. It should be set from the pipeline with `set_begin_index`.""" + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0) -> None: + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`, defaults to `0`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def __len__(self) -> int: + return self.config.num_train_timesteps + + def set_timesteps( + self, + num_inference_steps: int | None = None, + device: str | torch.device | None = None, + sigmas: list[float] | None = None, + mu: float | None = None, + timesteps: list[float] | None = None, + ) -> None: + """Set the distilled PiFlow timestep schedule. + + Args: + num_inference_steps (`int`): Number of model evaluations. + device (`str` or `torch.device`, *optional*): Device for the schedule. + sigmas (`list[float]`, *optional*): Unsupported custom sigma schedule. + mu (`float`, *optional*): Unsupported dynamic-shift parameter. + timesteps (`list[float]`, *optional*): Unsupported custom timestep schedule. + """ + if sigmas is not None or mu is not None or timesteps is not None: + raise ValueError("PiflowScheduler only supports its configured distilled timestep schedule") + if num_inference_steps is None or num_inference_steps < 1: + raise ValueError(f"num_inference_steps must be positive, got {num_inference_steps}") + one_minus_final = 1.0 - self.final_step_size_scale + segment = 1.0 / (num_inference_steps - one_minus_final) + raw = 1.0 - torch.arange(num_inference_steps, dtype=torch.float32, device=device) * segment + sigmas = shift_timesteps(raw, float(self.config.shift)) + self.num_inference_steps = int(num_inference_steps) + self._piflow_raw_timesteps = raw + self.timesteps = sigmas * self.config.num_train_timesteps + self.sigmas = torch.cat([sigmas, sigmas.new_zeros(1)]) + self._step_index = None + self._begin_index = None + + def _to_grid(self, model_output: torch.Tensor, sample: torch.Tensor) -> torch.Tensor: + if model_output.ndim != sample.ndim or model_output.shape[:-1] != sample.shape[:-1]: + raise ValueError( + "Piflow model output must match sample shape except for the output channels: " + f"got {tuple(model_output.shape)} for sample {tuple(sample.shape)}" + ) + if model_output.shape[-1] % self.n_grid != 0: + raise ValueError( + f"Piflow model output channels {model_output.shape[-1]} are not divisible by n_grid={self.n_grid}" + ) + output_dim = model_output.shape[-1] // self.n_grid + if output_dim != sample.shape[-1]: + raise ValueError( + "Piflow model output channels do not match the sample: " + f"expected {sample.shape[-1] * self.n_grid}, got {model_output.shape[-1]}" + ) + return model_output.reshape(*model_output.shape[:-1], self.n_grid, output_dim).movedim(-2, 1) + + def _policy_step(self, model_output: torch.Tensor, sample: torch.Tensor, step_index: int) -> torch.Tensor: + model_output = self._to_grid(model_output, sample) + raw_src = self._piflow_raw_timesteps[step_index].to(device=sample.device) + raw_dst = ( + self._piflow_raw_timesteps[step_index + 1] + if step_index + 1 < self._piflow_raw_timesteps.numel() + else self._piflow_raw_timesteps.new_full((), self.eps) + ).to(device=sample.device) + sigma_src = self.sigmas[step_index].to(device=sample.device) + token_shape = (sample.shape[0], *((sample.ndim - 1) * [1])) + sigma = sigma_src.expand(sample.shape[0]).reshape(token_shape) + segment = (raw_src - raw_dst).expand(sample.shape[0]) + policy = DXPolicy( + model_output, + sample, + sigma, + segment, + shift=float(self.config.shift), + mode="grid", + eps=self.eps, + ) + updated, _, _ = policy_rollout_fm( + sample, + sigma, + raw_src.expand(sample.shape[0]), + raw_dst.expand(sample.shape[0]), + self.num_policy_substeps, + policy, + ) + return updated + + def _step_index_for(self, timestep: torch.Tensor | float) -> int: + if self.step_index is None: + if self.begin_index is not None: + self._step_index = self.begin_index + else: + schedule_timesteps = self.timesteps + timestep = torch.as_tensor( + timestep, + device=schedule_timesteps.device, + dtype=schedule_timesteps.dtype, + ) + indices = torch.nonzero(schedule_timesteps == timestep).flatten() + if not indices.numel(): + raise ValueError(f"timestep {timestep.item()} is not in the Piflow schedule") + position = 1 if indices.numel() > 1 else 0 + self._step_index = int(indices[position].item()) + if self.step_index is None or self.step_index >= self.num_inference_steps: + raise RuntimeError("PiflowScheduler.step called after the schedule was exhausted") + return int(self.step_index) + + def step( + self, + model_output: torch.FloatTensor, + timestep: float | torch.FloatTensor, + sample: torch.FloatTensor, + return_dict: bool = True, + ) -> PiflowSchedulerOutput | tuple: + """Advance one step by integrating the PiFlow policy. + + Args: + model_output (`torch.FloatTensor`): Widened model output containing + ``n_grid`` predictions per sample channel. + timestep (`float` or `torch.FloatTensor`): Current scheduler timestep. + sample (`torch.FloatTensor`): Current noisy sample. + return_dict (`bool`, *optional*, defaults to True): Whether to return + a [`PiflowSchedulerOutput`]. + + Returns: + [`PiflowSchedulerOutput`] or `tuple`: Updated sample. + """ + if isinstance(timestep, int) or isinstance(timestep, (torch.IntTensor, torch.LongTensor)): + raise ValueError( + "Passing integer indices as timesteps to PiflowScheduler.step() is not supported; " + "pass a value from scheduler.timesteps instead" + ) + step_index = self._step_index_for(timestep) + # PiFlow's policy rollout performs its update in float32, matching the + # native sampler; cast back to the input dtype before returning, like + # the base Euler scheduler does. + updated = self._policy_step(model_output, sample.to(torch.float32), step_index) + updated = updated.to(dtype=sample.dtype) + self._step_index += 1 + if return_dict: + return PiflowSchedulerOutput(prev_sample=updated) + return (updated,) diff --git a/src/diffusers/utils/dummy_pt_objects.py b/src/diffusers/utils/dummy_pt_objects.py index 3434c6416cce..2d89f6f955aa 100644 --- a/src/diffusers/utils/dummy_pt_objects.py +++ b/src/diffusers/utils/dummy_pt_objects.py @@ -1639,6 +1639,66 @@ def from_pretrained(cls, *args, **kwargs): requires_backends(cls, ["torch"]) +class Kandinsky6SRLatentUpscalerBank(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class Kandinsky6SRTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class Kandinsky6SRVAE(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class Kandinsky6Transformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + class Krea2Transformer2DModel(metaclass=DummyObject): _backends = ["torch"] @@ -1864,6 +1924,36 @@ def from_pretrained(cls, *args, **kwargs): requires_backends(cls, ["torch"]) +class MMAudioVAE(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class MMAudioVocoder(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + class MochiTransformer3DModel(metaclass=DummyObject): _backends = ["torch"] @@ -3681,6 +3771,21 @@ def from_pretrained(cls, *args, **kwargs): requires_backends(cls, ["torch"]) +class PiflowScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + class PNDMScheduler(metaclass=DummyObject): _backends = ["torch"] diff --git a/src/diffusers/utils/dummy_torch_and_transformers_objects.py b/src/diffusers/utils/dummy_torch_and_transformers_objects.py index ec3cc45bf16d..9ede7a7543f6 100644 --- a/src/diffusers/utils/dummy_torch_and_transformers_objects.py +++ b/src/diffusers/utils/dummy_torch_and_transformers_objects.py @@ -2732,6 +2732,66 @@ def from_pretrained(cls, *args, **kwargs): requires_backends(cls, ["torch", "transformers"]) +class Kandinsky6SRPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky6SRPipelineOutput(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky6TI2VAPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky6TI2VAPipelineOutput(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + class KandinskyCombinedPipeline(metaclass=DummyObject): _backends = ["torch", "transformers"] diff --git a/src/diffusers/utils/export_utils.py b/src/diffusers/utils/export_utils.py index f06f172e79b2..5ceb3c5b3452 100644 --- a/src/diffusers/utils/export_utils.py +++ b/src/diffusers/utils/export_utils.py @@ -276,8 +276,9 @@ def _write_audio( ) -> None: import torch - if samples.ndim == 1: - samples = samples[:, None] + # Mono audio is written as stereo, with the channel duplicated. + if samples.ndim == 1 or 1 in samples.shape: + samples = samples.reshape(-1, 1).repeat(1, 2) if samples.shape[1] != 2 and samples.shape[0] == 2: samples = samples.T diff --git a/src/diffusers/utils/peft_utils.py b/src/diffusers/utils/peft_utils.py index ea6f86798100..f20e3f32b008 100644 --- a/src/diffusers/utils/peft_utils.py +++ b/src/diffusers/utils/peft_utils.py @@ -368,6 +368,126 @@ def check_peft_version(min_version: str) -> None: ) +def _maybe_fuse_qkv_projections_for_lokr(model, state_dict) -> None: + """ + Fuse the model's QKV projections when a peft-format LoKr state dict targets fused `to_qkv` / `to_added_qkv` + projections that the model does not have yet. + + BFL-format Flux2 LoKr checkpoints apply LoKr to the fused QKV projections. Unlike a LoRA delta, a Kronecker product + delta over the fused projection cannot be split exactly into separate Q/K/V factors, so the model's projections are + fused instead and the adapter maps 1:1. + """ + fused_targets = { + module + for module in (k.rpartition(".lokr_")[0] for k in state_dict if ".lokr_" in k) + if module.rsplit(".", 1)[-1] in ("to_qkv", "to_added_qkv") + } + named_modules = dict(model.named_modules()) + if all(module in named_modules for module in fused_targets) or not hasattr(model, "fuse_qkv_projections"): + return + + if getattr(model, "is_quantized", False): + raise ValueError( + "This LoKr checkpoint targets fused QKV projections. Fusing concatenates the Q/K/V weights into a new " + "`nn.Linear`, which is not possible with quantized weights. Please load the transformer without " + "quantization." + ) + + # Fusing replaces to_q/to_k/to_v (and the add_*_proj) with a single projection, which would orphan any adapter + # already injected on the unfused ones. + from peft.tuners.tuners_utils import BaseTunerLayer + + unfused_projections = {"to_q", "to_k", "to_v", "add_q_proj", "add_k_proj", "add_v_proj"} + adapted = [ + name + for name, module in named_modules.items() + if isinstance(module, BaseTunerLayer) and name.rsplit(".", 1)[-1] in unfused_projections + ] + if adapted: + raise ValueError( + "This LoKr checkpoint targets fused QKV projections, but an adapter is already loaded on the unfused " + f"projections (e.g. `{adapted[0]}`). Unload it with `unload_lora_weights()` before loading this checkpoint." + ) + + logger.info("The LoKr checkpoint targets fused QKV projections; calling `fuse_qkv_projections()` on the model.") + model.fuse_qkv_projections() + + +def _create_lokr_config(state_dict, metadata): + """ + Create a `LoKrConfig` from a peft-format LoKr state dict (keys like `{module}.lokr_w1`). + + Without metadata, the config is inferred from the tensor shapes. The checkpoint alpha is expected to be already + baked into the weights by the state dict conversion, so `alpha` is set equal to the rank (runtime scaling 1.0). + peft re-derives each module's Kronecker factorization from `decompose_factor` and only creates rank-decomposed + factors when the rank is small compared to the factorized dimensions, so for modules whose checkpoint factors are + full matrices the rank is set to `max(lokr_w2.shape)` to make peft create full matrices as well. + """ + from peft import LoKrConfig + from peft.tuners.lokr.layer import factorization + + if metadata is not None: + try: + return LoKrConfig(**metadata) + except TypeError as e: + raise TypeError("`LoKrConfig` class could not be instantiated.") from e + + modules = sorted({k.rpartition(".lokr_")[0] for k in state_dict if ".lokr_" in k}) + + # Reconstruct each module's factorized dimensions, (out_l, out_k) x (in_m, in_n), from the checkpoint. A factor + # is either stored as a full matrix (`lokr_w1`) or rank-decomposed into `lokr_w1_a @ lokr_w1_b` (same for w2). + factorizations = {} + rank_dict = {} + for module in modules: + w1, w1_a, w1_b = (state_dict.get(f"{module}.lokr_w1{s}") for s in ("", "_a", "_b")) + w2, w2_a, w2_b = (state_dict.get(f"{module}.lokr_w2{s}") for s in ("", "_a", "_b")) + out_l, in_m = w1.shape if w1 is not None else (w1_a.shape[0], w1_b.shape[1]) + out_k, in_n = w2.shape if w2 is not None else (w2_a.shape[0], w2_b.shape[1]) + factorizations[module] = ((out_l, out_k), (in_m, in_n)) + if w2_a is not None: + rank_dict[module] = w2_a.shape[1] + elif w1_a is not None: + rank_dict[module] = w1_a.shape[1] + else: + rank_dict[module] = max(w2.shape) + + # Find the `decompose_factor` under which peft reproduces the checkpoint factorizations. A fixed factor shows up + # as the left dimension of the modules it divides (modules it does not divide fall back to a near-square + # factorization, like with factor -1), so every observed left dimension is a candidate. + left_dims = {dims[0][0] for dims in factorizations.values()} + decompose_factor = None + for candidate in sorted(left_dims) + [-1]: + if all( + factorization(out_l * out_k, candidate) == (out_l, out_k) + and factorization(in_m * in_n, candidate) == (in_m, in_n) + for (out_l, out_k), (in_m, in_n) in factorizations.values() + ): + decompose_factor = candidate + break + if decompose_factor is None: + raise ValueError( + "Could not infer a `decompose_factor` that reproduces the Kronecker factorizations of this LoKr " + "state dict. Please open an issue: https://github.com/huggingface/diffusers/issues/new" + ) + + r = collections.Counter(rank_dict.values()).most_common(1)[0][0] + rank_pattern = {k: v for k, v in rank_dict.items() if v != r} + + lokr_config_kwargs = { + "r": r, + "alpha": r, + "rank_pattern": rank_pattern, + "alpha_pattern": dict(rank_pattern), + "target_modules": modules, + "decompose_both": any(".lokr_w1_a" in k for k in state_dict), + "decompose_factor": decompose_factor, + } + try: + return LoKrConfig(**lokr_config_kwargs) + except TypeError as e: + raise TypeError("`LoKrConfig` class could not be instantiated.") from e + + def _create_lora_config( state_dict, network_alphas, metadata, rank_pattern_dict, is_unet=True, model_state_dict=None, adapter_name=None ): @@ -397,7 +517,7 @@ def _maybe_warn_for_unhandled_keys(incompatible_keys, adapter_name: str) -> None # Check only for unexpected keys. unexpected_keys = getattr(incompatible_keys, "unexpected_keys", None) if unexpected_keys: - lora_unexpected_keys = [k for k in unexpected_keys if ".lora_" in k] + lora_unexpected_keys = [k for k in unexpected_keys if ".lora_" in k or "lokr_" in k] if lora_unexpected_keys: warn_msg = ( f"Loading adapter weights from state_dict led to unexpected keys found in the model:" @@ -407,7 +527,7 @@ def _maybe_warn_for_unhandled_keys(incompatible_keys, adapter_name: str) -> None # Filter missing keys specific to the current adapter. missing_keys = getattr(incompatible_keys, "missing_keys", None) if missing_keys: - lora_missing_keys = [k for k in missing_keys if ".lora_" in k and adapter_name in k] + lora_missing_keys = [k for k in missing_keys if (".lora_" in k or "lokr_" in k) and adapter_name in k] if lora_missing_keys: warn_msg += ( f"Loading adapter weights from state_dict led to missing keys in the model:" diff --git a/tests/models/autoencoders/test_models_autoencoder_kandinsky6_sr.py b/tests/models/autoencoders/test_models_autoencoder_kandinsky6_sr.py new file mode 100644 index 000000000000..f7a27ce31e78 --- /dev/null +++ b/tests/models/autoencoders/test_models_autoencoder_kandinsky6_sr.py @@ -0,0 +1,105 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from diffusers import Kandinsky6SRVAE +from diffusers.utils.torch_utils import randn_tensor + +from ...testing_utils import assert_tensors_close, enable_full_determinism, torch_device +from ..testing_utils import ( + BaseModelTesterConfig, + MemoryTesterMixin, + ModelTesterMixin, + TorchCompileTesterMixin, +) + + +enable_full_determinism() + + +class Kandinsky6SRVAETesterConfig(BaseModelTesterConfig): + @property + def model_class(self): + return Kandinsky6SRVAE + + @property + def pretrained_model_name_or_path(self): + return "kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers" + + @property + def pretrained_model_kwargs(self): + return {"subfolder": "vae"} + + @property + def main_input_name(self) -> str: + return "sample" + + @property + def generator(self): + return torch.Generator("cpu").manual_seed(0) + + def get_init_dict(self) -> dict: + return { + "in_channels": 3, + "out_channels": 3, + "latent_channels": 4, + "encoder_block_out_channels": (4, 8, 8), + "decoder_block_out_channels": (4, 8, 8), + "layers_per_block": 1, + "temporal_compression_ratio": 4, + "temporal_compression_start_level": 0, + } + + def get_dummy_inputs(self) -> dict: + return {"sample": randn_tensor((2, 3, 9, 16, 16), generator=self.generator, device=torch_device)} + + @property + def input_shape(self) -> tuple[int, ...]: + return (3, 9, 16, 16) + + @property + def output_shape(self) -> tuple[int, ...]: + return (3, 9, 16, 16) + + +class TestKandinsky6SRVAEModel(Kandinsky6SRVAETesterConfig, ModelTesterMixin): + def test_compression_ratios(self): + model = self.model_class(**self.get_init_dict()).to(torch_device).eval() + with torch.no_grad(): + latents = model.encode(self.get_dummy_inputs()["sample"]).latent_dist.mode() + assert model.spatial_compression_ratio == 4 + assert model.temporal_compression_ratio == 4 + assert latents.shape == (2, 4, 3, 4, 4) + + def test_segmented_processing_matches_single_pass(self): + # 41 frames span three causal segments; the carried padding must reproduce a single-segment result. + model = self.model_class(**self.get_init_dict()).to(torch_device).eval() + sample = randn_tensor((1, 3, 41, 16, 16), generator=self.generator, device=torch_device) + with torch.no_grad(): + latents = model.encode(sample).latent_dist.mode() + latents_prefix = model.encode(sample[:, :, :17]).latent_dist.mode() + decoded = model.decode(latents).sample + decoded_prefix = model.decode(latents[:, :, :5]).sample + assert_tensors_close(latents_prefix, latents[:, :, :5], atol=1e-5, rtol=0) + assert_tensors_close(decoded_prefix, decoded[:, :, :17], atol=1e-4, rtol=0) + + +class TestKandinsky6SRVAEMemory(Kandinsky6SRVAETesterConfig, MemoryTesterMixin): + pass + + +class TestKandinsky6SRVAETorchCompile(Kandinsky6SRVAETesterConfig, TorchCompileTesterMixin): + pass diff --git a/tests/models/autoencoders/test_models_autoencoder_mmaudio.py b/tests/models/autoencoders/test_models_autoencoder_mmaudio.py new file mode 100644 index 000000000000..a12e01ee4049 --- /dev/null +++ b/tests/models/autoencoders/test_models_autoencoder_mmaudio.py @@ -0,0 +1,96 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from diffusers import MMAudioVAE +from diffusers.utils.torch_utils import randn_tensor + +from ...testing_utils import enable_full_determinism, torch_device +from ..testing_utils import ( + BaseModelTesterConfig, + MemoryTesterMixin, + ModelTesterMixin, + TorchCompileTesterMixin, +) + + +enable_full_determinism() + + +class MMAudioVAETesterConfig(BaseModelTesterConfig): + @property + def model_class(self): + return MMAudioVAE + + @property + def pretrained_model_name_or_path(self): + return "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers" + + @property + def pretrained_model_kwargs(self): + return {"subfolder": "audio_vae"} + + @property + def main_input_name(self) -> str: + return "sample" + + @property + def generator(self): + return torch.Generator("cpu").manual_seed(0) + + def get_init_dict(self) -> dict: + return { + "mel_bins": 8, + "latent_channels": 4, + "hidden_channels": 8, + "channel_multipliers": (1, 2), + "layers_per_block": 1, + "sample_rate": 64, + "n_fft": 16, + "hop_length": 4, + } + + def get_dummy_inputs(self) -> dict: + waveform = randn_tensor((2, 256), generator=self.generator, device=torch_device).clamp(-1, 1) + return {"sample": waveform} + + @property + def input_shape(self) -> tuple[int, ...]: + return (256,) + + @property + def output_shape(self) -> tuple[int, ...]: + # `decode`/`forward` return a mel spectrogram (`mel_bins`, num_mel_frames); the waveform is produced by the + # separate `MMAudioVocoder`. + return (8, 64) + + +class TestMMAudioVAEModel(MMAudioVAETesterConfig, ModelTesterMixin): + def test_latent_shape(self): + model = self.model_class(**self.get_init_dict()).to(torch_device).eval() + with torch.no_grad(): + latents = model.encode(self.get_dummy_inputs()["sample"]).latent_dist.mode() + # 256 samples -> 64 mel frames (hop 4) -> 32 latent frames (one 2x downsample) + assert model.latent_hop_length == 8 + assert latents.shape == (2, 4, 32) + + +class TestMMAudioVAEMemory(MMAudioVAETesterConfig, MemoryTesterMixin): + pass + + +class TestMMAudioVAETorchCompile(MMAudioVAETesterConfig, TorchCompileTesterMixin): + pass diff --git a/tests/models/autoencoders/test_models_vocoder.py b/tests/models/autoencoders/test_models_vocoder.py new file mode 100644 index 000000000000..225cfdbf4386 --- /dev/null +++ b/tests/models/autoencoders/test_models_vocoder.py @@ -0,0 +1,86 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from diffusers import MMAudioVocoder +from diffusers.utils.torch_utils import randn_tensor + +from ...testing_utils import enable_full_determinism, torch_device +from ..testing_utils import ( + BaseModelTesterConfig, + MemoryTesterMixin, + ModelTesterMixin, + TorchCompileTesterMixin, +) + + +enable_full_determinism() + + +class MMAudioVocoderTesterConfig(BaseModelTesterConfig): + @property + def model_class(self): + return MMAudioVocoder + + @property + def pretrained_model_name_or_path(self): + return "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers" + + @property + def pretrained_model_kwargs(self): + return {"subfolder": "vocoder"} + + @property + def main_input_name(self) -> str: + return "mel" + + @property + def generator(self): + return torch.Generator("cpu").manual_seed(0) + + def get_init_dict(self) -> dict: + return { + "num_mels": 8, + "upsample_initial_channel": 8, + "upsample_rates": (2, 2), + "upsample_kernel_sizes": (4, 4), + "resblock_kernel_sizes": (3,), + "resblock_dilation_sizes": ((1, 3),), + } + + def get_dummy_inputs(self) -> dict: + return {"mel": randn_tensor((2, 8, 16), generator=self.generator, device=torch_device)} + + @property + def input_shape(self) -> tuple[int, ...]: + return (8, 16) + + @property + def output_shape(self) -> tuple[int, ...]: + # `upsample_rates` multiply to 4, so 16 mel frames decode to 64 samples. + return (1, 64) + + +class TestMMAudioVocoderModel(MMAudioVocoderTesterConfig, ModelTesterMixin): + pass + + +class TestMMAudioVocoderMemory(MMAudioVocoderTesterConfig, MemoryTesterMixin): + pass + + +class TestMMAudioVocoderTorchCompile(MMAudioVocoderTesterConfig, TorchCompileTesterMixin): + pass diff --git a/tests/models/latent_upscaler/__init__.py b/tests/models/latent_upscaler/__init__.py new file mode 100644 index 000000000000..e69de29bb2d1 diff --git a/tests/models/latent_upscaler/test_models_latent_upscaler.py b/tests/models/latent_upscaler/test_models_latent_upscaler.py new file mode 100644 index 000000000000..059041af075d --- /dev/null +++ b/tests/models/latent_upscaler/test_models_latent_upscaler.py @@ -0,0 +1,96 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from diffusers import Kandinsky6SRLatentUpscalerBank +from diffusers.utils.torch_utils import randn_tensor + +from ...testing_utils import enable_full_determinism, torch_device +from ..testing_utils import ( + BaseModelTesterConfig, + MemoryTesterMixin, + ModelTesterMixin, + TorchCompileTesterMixin, +) + + +enable_full_determinism() + + +class Kandinsky6SRLatentUpscalerBankTesterConfig(BaseModelTesterConfig): + @property + def model_class(self): + return Kandinsky6SRLatentUpscalerBank + + @property + def pretrained_model_name_or_path(self): + return "kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers" + + @property + def pretrained_model_kwargs(self): + return {"subfolder": "latent_upscaler"} + + @property + def main_input_name(self) -> str: + return "latents" + + @property + def generator(self): + return torch.Generator("cpu").manual_seed(0) + + def get_init_dict(self) -> dict: + return { + "in_channels": 4, + "stage_channels": (8, 8, 4), + "num_pre_blocks": 1, + "num_mid_blocks": 1, + "num_post_blocks": 1, + "num_x2_adapter_blocks": 1, + "scales": (2, 4), + } + + def get_dummy_inputs(self) -> dict: + return { + "latents": randn_tensor((2, 4, 3, 4, 4), generator=self.generator, device=torch_device), + "scale": 2, + } + + @property + def input_shape(self) -> tuple[int, ...]: + return (4, 3, 4, 4) + + @property + def output_shape(self) -> tuple[int, ...]: + return (4, 3, 8, 8) + + +class TestKandinsky6SRLatentUpscalerBankModel(Kandinsky6SRLatentUpscalerBankTesterConfig, ModelTesterMixin): + def test_x4_scale(self): + model = self.model_class(**self.get_init_dict()).to(torch_device).eval() + inputs = self.get_dummy_inputs() + with torch.no_grad(): + output = model(inputs["latents"], scale=4).sample + assert output.shape == (2, 4, 3, 16, 16) + + +class TestKandinsky6SRLatentUpscalerBankMemory(Kandinsky6SRLatentUpscalerBankTesterConfig, MemoryTesterMixin): + pass + + +class TestKandinsky6SRLatentUpscalerBankTorchCompile( + Kandinsky6SRLatentUpscalerBankTesterConfig, TorchCompileTesterMixin +): + pass diff --git a/tests/models/testing_utils/__init__.py b/tests/models/testing_utils/__init__.py index 2d7d5ae23257..8bab73f67ca4 100644 --- a/tests/models/testing_utils/__init__.py +++ b/tests/models/testing_utils/__init__.py @@ -17,6 +17,7 @@ from .common import BaseModelTesterConfig, ModelTesterMixin from .compile import TorchCompileTesterMixin from .ip_adapter import IPAdapterTesterMixin +from .lokr import LoKrTesterMixin from .lora import LoraHotSwappingForModelTesterMixin, LoraTesterMixin from .memory import CPUOffloadTesterMixin, GroupOffloadTesterMixin, LayerwiseCastingTesterMixin, MemoryTesterMixin from .parallelism import ( @@ -80,6 +81,7 @@ "GroupOffloadTesterMixin", "IPAdapterTesterMixin", "LayerwiseCastingTesterMixin", + "LoKrTesterMixin", "LoraHotSwappingForModelTesterMixin", "LoraTesterMixin", "MemoryTesterMixin", diff --git a/tests/models/testing_utils/lokr.py b/tests/models/testing_utils/lokr.py new file mode 100644 index 000000000000..d1589d28fadd --- /dev/null +++ b/tests/models/testing_utils/lokr.py @@ -0,0 +1,139 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import pytest +import torch +import torch.nn as nn + +from diffusers.utils.import_utils import is_peft_available + +from ...testing_utils import assert_tensors_close, is_lora, require_peft_backend, torch_device +from .common import BaseModelOutputMixin + + +if is_peft_available(): + from peft.tuners.lokr.layer import LoKrLayer, factorization + + from diffusers.loaders.peft import PeftAdapterMixin + + +def make_lokr_factors(out_features, in_features, factor=4, rank=None): + """ + Random LoKr factors for an `out_features x in_features` layer, factorized like peft does with `decompose_factor`. + With `rank`, the right factor is stored rank-decomposed (`lokr_w2_a @ lokr_w2_b`). + + Returns the factors keyed by their state dict suffix, and the delta weight they encode. + """ + out_l, out_k = factorization(out_features, factor) + in_m, in_n = factorization(in_features, factor) + w1 = torch.randn(out_l, in_m) + if rank is None: + w2 = torch.randn(out_k, in_n) + return {"lokr_w1": w1, "lokr_w2": w2}, torch.kron(w1, w2) + w2_a, w2_b = torch.randn(out_k, rank), torch.randn(rank, in_n) + return {"lokr_w1": w1, "lokr_w2_a": w2_a, "lokr_w2_b": w2_b}, torch.kron(w1, w2_a @ w2_b) + + +def check_lokr_deltas(model, expected_deltas, adapter_name="default", atol=1e-5): + """Check that exactly the expected modules carry a LoKr adapter, each with the expected delta weight.""" + named_modules = dict(model.named_modules()) + adapted = {name for name, module in named_modules.items() if isinstance(module, LoKrLayer)} + assert adapted == set(expected_deltas) + for name, expected in expected_deltas.items(): + delta = named_modules[name].get_delta_weight(adapter_name).cpu() + assert_tensors_close(delta, expected, atol=atol, rtol=0, msg=f"Wrong LoKr delta on {name}") + + +@is_lora +@require_peft_backend +class LoKrTesterMixin(BaseModelOutputMixin): + """ + Mixin class for testing loading LoKr (LyCORIS Kronecker product) adapters with `load_lora_adapter`. + + Expected from config mixin: + - model_class: The model class to test + + Expected methods from config mixin: + - get_init_dict(): Returns dict of arguments to initialize the model + - get_dummy_inputs(): Returns dict of inputs to pass to the model forward pass + + Pytest mark: lora + Use `pytest -m "not lora"` to skip these tests + """ + + def setup_method(self): + if not issubclass(self.model_class, PeftAdapterMixin): + pytest.skip(f"PEFT is not supported for this model ({self.model_class.__name__}).") + + def _flatten_output(self, output): + # Some models (e.g. Z-Image) return a list of per-sample tensors. + if isinstance(output, (list, tuple)): + return torch.cat([t.flatten() for t in output]) + return output + + def _model_output(self, model, inputs_dict): + return self._flatten_output(model(**inputs_dict, return_dict=False)[0]) + + def get_lokr_state_dict(self, model, rank=None): + """ + A peft-format LoKr state dict on every attention `to_q` and `to_v`, with the expected delta of each. With + `rank`, the `to_v` factors are rank-decomposed, so the config inference has to mix both kinds. + """ + state_dict, expected_deltas = {}, {} + for name, module in model.named_modules(): + projection = name.rsplit(".", 1)[-1] + if isinstance(module, nn.Linear) and projection in ("to_q", "to_v"): + factors, delta = make_lokr_factors( + module.out_features, module.in_features, rank=rank if projection == "to_v" else None + ) + state_dict.update({f"{name}.{suffix}": weight for suffix, weight in factors.items()}) + expected_deltas[name] = delta + return state_dict, expected_deltas + + @pytest.mark.parametrize("rank", [None, 1], ids=["full_factors", "rank_decomposed_factors"]) + @torch.no_grad() + def test_lokr_adapter_loads_exact_kronecker_deltas(self, base_model_output, rank): + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + state_dict, expected_deltas = self.get_lokr_state_dict(model, rank=rank) + + model.load_lora_adapter(state_dict, prefix=None, adapter_name="default") + + check_lokr_deltas(model, expected_deltas) + output = self._model_output(model, self.get_dummy_inputs()) + base_output = self._flatten_output(base_model_output) + assert not torch.allclose(output, base_output, atol=1e-4, rtol=1e-4), "Output should differ with LoKr" + + @torch.no_grad() + def test_lokr_unload_restores_base_output(self, base_model_output): + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + state_dict, _ = self.get_lokr_state_dict(model) + + model.load_lora_adapter(state_dict, prefix=None, adapter_name="default") + model.unload_lora() + + assert not any(isinstance(module, LoKrLayer) for module in model.modules()) + output = self._model_output(model, self.get_dummy_inputs()) + assert_tensors_close(output, self._flatten_output(base_model_output), atol=1e-4, rtol=1e-4) + + def test_lokr_hotswap_raises(self): + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + state_dict, _ = self.get_lokr_state_dict(model) + model.load_lora_adapter(state_dict, prefix=None, adapter_name="default") + + with pytest.raises(ValueError, match="Hotswapping LoKr adapters is not supported"): + model.load_lora_adapter(state_dict, prefix=None, adapter_name="default", hotswap=True) diff --git a/tests/models/transformers/test_models_transformer_flux2.py b/tests/models/transformers/test_models_transformer_flux2.py index 3263ce68202c..cc4f5cad966a 100644 --- a/tests/models/transformers/test_models_transformer_flux2.py +++ b/tests/models/transformers/test_models_transformer_flux2.py @@ -17,9 +17,11 @@ import subprocess import sys +import pytest import torch from diffusers import Flux2Transformer2DModel +from diffusers.loaders.lora_pipeline import Flux2LoraLoaderMixin from diffusers.models.transformers.transformer_flux2 import ( Flux2KVAttnProcessor, Flux2KVCache, @@ -36,6 +38,7 @@ ContextParallelTesterMixin, GGUFCompileTesterMixin, GGUFTesterMixin, + LoKrTesterMixin, LoraHotSwappingForModelTesterMixin, LoraTesterMixin, MemoryTesterMixin, @@ -47,6 +50,7 @@ TorchCompileTesterMixin, TrainingTesterMixin, ) +from ..testing_utils.lokr import check_lokr_deltas, make_lokr_factors enable_full_determinism() @@ -202,6 +206,116 @@ class TestFlux2TransformerLoRA(Flux2TransformerTesterConfig, LoraTesterMixin): """LoRA adapter tests for Flux2 Transformer.""" +class TestFlux2TransformerLoKr(Flux2TransformerTesterConfig, LoKrTesterMixin): + """LoKr adapter tests for Flux2 Transformer, including the Flux2 LoKr checkpoint formats.""" + + # ai-toolkit stores a placeholder alpha for full-matrix factors, where LoKr applies no scaling. + placeholder_alpha = torch.tensor(9999220736.0) + + def get_bfl_qkv_state_dict(self, model): + """A BFL-format LoKr state dict on the fused QKV projections of the first double block.""" + to_q = model.transformer_blocks[0].attn.to_q + state_dict, expected_deltas = {}, {} + for bfl_path, diffusers_path in [ + ("double_blocks.0.img_attn.qkv", "transformer_blocks.0.attn.to_qkv"), + ("double_blocks.0.txt_attn.qkv", "transformer_blocks.0.attn.to_added_qkv"), + ]: + factors, expected_deltas[diffusers_path] = make_lokr_factors(3 * to_q.out_features, to_q.in_features) + state_dict.update({f"diffusion_model.{bfl_path}.{k}": v for k, v in factors.items()}) + state_dict[f"diffusion_model.{bfl_path}.alpha"] = self.placeholder_alpha + return state_dict, expected_deltas + + @torch.no_grad() + def test_lokr_bfl_checkpoint(self): + # BFL checkpoints (e.g. ai-toolkit) apply LoKr to the fused QKV projections. A Kronecker product delta cannot + # be split exactly into Q/K/V, so loading fuses the model's projections and maps the adapter 1:1. + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + state_dict, expected_deltas = self.get_bfl_qkv_state_dict(model) + for bfl_path, diffusers_path in [ + ("single_blocks.0.linear1", "single_transformer_blocks.0.attn.to_qkv_mlp_proj"), + ("double_blocks.0.img_attn.proj", "transformer_blocks.0.attn.to_out.0"), + ("double_blocks.0.img_mlp.0", "transformer_blocks.0.ff.linear_in"), + ]: + linear = model.get_submodule(diffusers_path) + factors, expected_deltas[diffusers_path] = make_lokr_factors(linear.out_features, linear.in_features) + state_dict.update({f"diffusion_model.{bfl_path}.{k}": v for k, v in factors.items()}) + state_dict[f"diffusion_model.{bfl_path}.alpha"] = self.placeholder_alpha + + converted = Flux2LoraLoaderMixin.lora_state_dict(state_dict) + model.load_lora_adapter(converted, prefix="transformer", adapter_name="default") + + assert model.transformer_blocks[0].attn.fused_projections + check_lokr_deltas(model, expected_deltas) + + def test_lokr_fused_qkv_checkpoint_refuses_when_unfused_projections_are_adapted(self): + # Fusing would replace to_q and orphan the adapter already injected there. + from peft import LoraConfig + + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + model.add_adapter(LoraConfig(r=2, target_modules=["to_q"]), adapter_name="lora") + state_dict, _ = self.get_bfl_qkv_state_dict(model) + converted = Flux2LoraLoaderMixin.lora_state_dict(state_dict) + + with pytest.raises(ValueError, match="already loaded on the unfused projections"): + model.load_lora_adapter(converted, prefix="transformer", adapter_name="lokr") + assert not model.transformer_blocks[0].attn.fused_projections + + @torch.no_grad() + def test_lokr_lycoris_checkpoint(self): + # LyCORIS wraps the diffusers model and encodes module paths with underscores under a `lycoris_` prefix. + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + state_dict, expected_deltas = {}, {} + for diffusers_path in [ + "single_transformer_blocks.0.attn.to_qkv_mlp_proj", + "transformer_blocks.0.attn.to_q", + "transformer_blocks.0.attn.to_out.0", + "transformer_blocks.0.ff.linear_in", + ]: + linear = model.get_submodule(diffusers_path) + factors, expected_deltas[diffusers_path] = make_lokr_factors(linear.out_features, linear.in_features) + lycoris_path = "lycoris_" + diffusers_path.replace(".", "_") + state_dict.update({f"{lycoris_path}.{k}": v for k, v in factors.items()}) + state_dict[f"{lycoris_path}.alpha"] = torch.tensor(16.0) + + converted = Flux2LoraLoaderMixin.lora_state_dict(state_dict) + model.load_lora_adapter(converted, prefix="transformer", adapter_name="default") + + check_lokr_deltas(model, expected_deltas) + + def test_lokr_lycoris_checkpoint_with_unknown_keys_raises(self): + state_dict = { + "lycoris_transformer_blocks_0_attn_to_q.lokr_w1": torch.randn(4, 4), + "lycoris_transformer_blocks_0_attn_norm_q.lokr_w1": torch.randn(4, 4), + } + with pytest.raises(ValueError, match="lycoris_transformer_blocks_0_attn_norm_q.lokr_w1"): + Flux2LoraLoaderMixin.lora_state_dict(state_dict) + + @torch.no_grad() + def test_lokr_diffusers_names_checkpoint(self): + # Checkpoints that store the diffusers module paths directly, with alpha keys and no prefix (e.g. SimpleTuner, + # `bghira/flux2-klein-9b-distillation-lokr`). Alpha scales the rank-decomposed factors only. + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + rank, alpha = 2, 1.0 + state_dict, expected_deltas = {}, {} + for diffusers_path, factor_rank in [ + ("single_transformer_blocks.0.attn.to_out", None), + ("transformer_blocks.0.attn.to_k", rank), + ]: + linear = model.get_submodule(diffusers_path) + factors, delta = make_lokr_factors(linear.out_features, linear.in_features, rank=factor_rank) + state_dict.update({f"{diffusers_path}.{k}": v for k, v in factors.items()}) + state_dict[f"{diffusers_path}.alpha"] = torch.tensor(alpha) + expected_deltas[diffusers_path] = delta if factor_rank is None else (alpha / rank) * delta + + converted = Flux2LoraLoaderMixin.lora_state_dict(state_dict) + model.load_lora_adapter(converted, prefix="transformer", adapter_name="default") + + check_lokr_deltas(model, expected_deltas) + + class TestFlux2TransformerLoRAHotSwap(Flux2TransformerTesterConfig, LoraHotSwappingForModelTesterMixin): """LoRA hot-swapping tests for Flux2 Transformer.""" diff --git a/tests/models/transformers/test_models_transformer_kandinsky6.py b/tests/models/transformers/test_models_transformer_kandinsky6.py new file mode 100644 index 000000000000..88be69c550b7 --- /dev/null +++ b/tests/models/transformers/test_models_transformer_kandinsky6.py @@ -0,0 +1,158 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import pytest +import torch + +from diffusers import Kandinsky6Transformer3DModel +from diffusers.utils.torch_utils import randn_tensor + +from ...testing_utils import enable_full_determinism, torch_device +from ..testing_utils import ( + AttentionTesterMixin, + BaseModelTesterConfig, + MemoryTesterMixin, + ModelTesterMixin, + TorchCompileTesterMixin, + TrainingTesterMixin, +) + + +enable_full_determinism() + + +class Kandinsky6TransformerTesterConfig(BaseModelTesterConfig): + @property + def model_class(self): + return Kandinsky6Transformer3DModel + + @property + def pretrained_model_name_or_path(self): + return "kandinskylab/Kandinsky-6.0-Pro-distill-5s-Diffusers" + + @property + def pretrained_model_kwargs(self): + return {"subfolder": "transformer"} + + @property + def main_input_name(self) -> str: + return "hidden_states" + + @property + def generator(self): + return torch.Generator("cpu").manual_seed(0) + + def get_init_dict(self) -> dict: + return { + "in_visual_dim": 4, + "out_visual_dim": 4, + "in_text_dim": 8, + "in_text_dim2": 8, + "time_dim": 16, + "patch_size": (1, 2, 2), + "model_dim": 48, + "ff_dim": 64, + "num_text_blocks": 1, + "num_visual_blocks": 2, + "axes_dims": (4, 4, 4), + "visual_cond": True, + "in_audio_dim": 4, + "out_audio_dim": 4, + "visual_token_type_num_embeddings": 2, + } + + def _build_dummy_inputs(self, batch_size: int, num_frames: int, height: int, width: int) -> dict: + init_dict = self.get_init_dict() + # `visual_cond=True` appends conditioning latents and a mask to the input channels + num_input_channels = 2 * init_dict["in_visual_dim"] + 1 + return { + "hidden_states": randn_tensor( + (batch_size, num_frames, height, width, num_input_channels), + generator=self.generator, + device=torch_device, + ), + "audio_hidden_states": randn_tensor( + (batch_size, 5, init_dict["in_audio_dim"]), generator=self.generator, device=torch_device + ), + "encoder_hidden_states": randn_tensor( + (batch_size, 6, init_dict["in_text_dim"]), generator=self.generator, device=torch_device + ), + "pooled_projections": randn_tensor( + (batch_size, init_dict["in_text_dim2"]), generator=self.generator, device=torch_device + ), + "timestep": torch.randint(0, 1000, (batch_size,), generator=self.generator).float().to(torch_device), + } + + def get_dummy_inputs(self) -> dict: + return self._build_dummy_inputs(batch_size=1, num_frames=2, height=4, width=4) + + @property + def input_shape(self) -> tuple[int, ...]: + return (2, 4, 4, 2 * 4 + 1) + + @property + def output_shape(self) -> tuple[int, ...]: + return (2, 4, 4, 4) + + +class TestKandinsky6TransformerModel(Kandinsky6TransformerTesterConfig, ModelTesterMixin): + def test_video_only_forward(self): + model = self.model_class(**self.get_init_dict()).to(torch_device).eval() + inputs = self.get_dummy_inputs() + inputs.pop("audio_hidden_states") + with torch.no_grad(): + output = model(**inputs) + assert output.sample.shape == (1, *self.output_shape) + assert output.audio_sample is None + + def test_tail_conditioning_inputs(self): + # An appended reference frame reuses temporal rotary position 0 and carries token type 1. + model = self.model_class(**self.get_init_dict()).to(torch_device).eval() + inputs = self._build_dummy_inputs(batch_size=1, num_frames=3, height=4, width=4) + inputs["visual_rope_pos"] = ( + torch.tensor([0, 1, 0], device=torch_device), + torch.arange(2, device=torch_device), + torch.arange(2, device=torch_device), + ) + inputs["visual_token_type_ids"] = torch.tensor([[0, 0, 1]], device=torch_device) + with torch.no_grad(): + output = model(**inputs) + assert output.sample.shape == (1, 3, 4, 4, 4) + + +class TestKandinsky6TransformerMemory(Kandinsky6TransformerTesterConfig, MemoryTesterMixin): + pass + + +class TestKandinsky6TransformerTorchCompile(Kandinsky6TransformerTesterConfig, TorchCompileTesterMixin): + @property + def different_shapes_for_compilation(self): + return [(4, 4), (4, 8), (8, 8)] + + def get_dummy_inputs(self, height: int = 4, width: int = 4) -> dict: + return self._build_dummy_inputs(batch_size=1, num_frames=2, height=height, width=width) + + +class TestKandinsky6TransformerTraining(Kandinsky6TransformerTesterConfig, TrainingTesterMixin): + pass + + +class TestKandinsky6TransformerAttention(Kandinsky6TransformerTesterConfig, AttentionTesterMixin): + def test_fuse_unfuse_qkv_projections(self, *args, **kwargs): + pytest.skip( + "Kandinsky6Attention names its projections to_query/to_key/to_value/out_layer (matching the " + "Kandinsky 5 layout) rather than to_q/to_k/to_v/to_out, which " + "AttentionModuleMixin.fuse_projections hardcodes." + ) diff --git a/tests/models/transformers/test_models_transformer_kandinsky6_sr.py b/tests/models/transformers/test_models_transformer_kandinsky6_sr.py new file mode 100644 index 000000000000..27d2a56a4a7a --- /dev/null +++ b/tests/models/transformers/test_models_transformer_kandinsky6_sr.py @@ -0,0 +1,121 @@ +# coding=utf-8 +# Copyright 2026 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import pytest +import torch + +from diffusers import Kandinsky6SRTransformer3DModel +from diffusers.utils.torch_utils import randn_tensor + +from ...testing_utils import enable_full_determinism, torch_device +from ..testing_utils import ( + AttentionTesterMixin, + BaseModelTesterConfig, + MemoryTesterMixin, + ModelTesterMixin, + TorchCompileTesterMixin, + TrainingTesterMixin, +) + + +enable_full_determinism() + + +class Kandinsky6SRTransformerTesterConfig(BaseModelTesterConfig): + @property + def model_class(self): + return Kandinsky6SRTransformer3DModel + + @property + def pretrained_model_name_or_path(self): + return "kandinskylab/Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers" + + @property + def pretrained_model_kwargs(self): + return {"subfolder": "transformer"} + + @property + def main_input_name(self) -> str: + return "hidden_states" + + @property + def generator(self): + return torch.Generator("cpu").manual_seed(0) + + def get_init_dict(self) -> dict: + return { + "in_visual_dim": 4, + "out_visual_dim": 8, + "time_dim": 16, + "patch_size": (1, 2, 2), + "model_dim": 24, + "ff_dim": 32, + "num_visual_blocks": 2, + "axes_dims": (4, 4, 4), + } + + def _build_dummy_inputs(self, batch_size: int, num_frames: int, height: int, width: int) -> dict: + # The input concatenates the noisy latent, the anchor latent and the anchor mask + num_input_channels = 2 * self.get_init_dict()["in_visual_dim"] + 1 + return { + "hidden_states": randn_tensor( + (batch_size, num_frames, height, width, num_input_channels), + generator=self.generator, + device=torch_device, + ), + "timestep": torch.randint(0, 1000, (batch_size,), generator=self.generator).float().to(torch_device), + } + + def get_dummy_inputs(self) -> dict: + return self._build_dummy_inputs(batch_size=1, num_frames=2, height=16, width=16) + + @property + def input_shape(self) -> tuple[int, ...]: + return (2, 16, 16, 2 * 4 + 1) + + @property + def output_shape(self) -> tuple[int, ...]: + return (2, 16, 16, 8) + + +class TestKandinsky6SRTransformerModel(Kandinsky6SRTransformerTesterConfig, ModelTesterMixin): + pass + + +class TestKandinsky6SRTransformerMemory(Kandinsky6SRTransformerTesterConfig, MemoryTesterMixin): + pass + + +class TestKandinsky6SRTransformerTorchCompile(Kandinsky6SRTransformerTesterConfig, TorchCompileTesterMixin): + @property + def different_shapes_for_compilation(self): + return [(16, 16), (16, 32), (32, 32)] + + def get_dummy_inputs(self, height: int = 16, width: int = 16) -> dict: + return self._build_dummy_inputs(batch_size=1, num_frames=2, height=height, width=width) + + +@pytest.mark.skipif(torch_device == "cpu", reason="FlexAttention does not support backward on CPU.") +class TestKandinsky6SRTransformerTraining(Kandinsky6SRTransformerTesterConfig, TrainingTesterMixin): + pass + + +class TestKandinsky6SRTransformerAttention(Kandinsky6SRTransformerTesterConfig, AttentionTesterMixin): + def test_fuse_unfuse_qkv_projections(self, *args, **kwargs): + pytest.skip( + "Kandinsky6SRAttention names its projections to_query/to_key/to_value/out_layer (matching the " + "Kandinsky 5 layout) rather than to_q/to_k/to_v/to_out, which " + "AttentionModuleMixin.fuse_projections hardcodes." + ) diff --git a/tests/models/transformers/test_models_transformer_z_image.py b/tests/models/transformers/test_models_transformer_z_image.py index 35bafa5702ae..1a6881c13126 100644 --- a/tests/models/transformers/test_models_transformer_z_image.py +++ b/tests/models/transformers/test_models_transformer_z_image.py @@ -18,6 +18,7 @@ import torch from diffusers import ZImageTransformer2DModel +from diffusers.loaders.lora_pipeline import ZImageLoraLoaderMixin from diffusers.utils.torch_utils import randn_tensor from ...testing_utils import assert_tensors_close, torch_device @@ -25,6 +26,7 @@ AutoRoundCompileTesterMixin, AutoRoundTesterMixin, BaseModelTesterConfig, + LoKrTesterMixin, LoraTesterMixin, MemoryTesterMixin, ModelTesterMixin, @@ -32,6 +34,7 @@ TorchCompileTesterMixin, TrainingTesterMixin, ) +from ..testing_utils.lokr import check_lokr_deltas, make_lokr_factors # Z-Image requires torch.use_deterministic_algorithms(False) due to complex64 RoPE operations @@ -183,6 +186,36 @@ class TestZImageTransformerLoRA(ZImageTransformerTesterConfig, LoraTesterMixin): """LoRA adapter tests for Z-Image Transformer.""" +class TestZImageTransformerLoKr(ZImageTransformerTesterConfig, LoKrTesterMixin): + """LoKr adapter tests for Z-Image Transformer, including the ai-toolkit Z-Image LoKr checkpoint format.""" + + @torch.no_grad() + def test_lokr_ai_toolkit_checkpoint(self): + # ai-toolkit stores the diffusers module paths under a `diffusion_model.` prefix. Full-matrix factors come with + # a placeholder alpha, where LoKr applies no scaling; rank-decomposed factors are scaled by `alpha / rank`. + torch.manual_seed(0) + model = self.model_class(**self.get_init_dict()).eval().to(torch_device) + rank = 1 + state_dict, expected_deltas = {}, {} + for module, factor_rank, alpha in [ + ("layers.0.attention.to_q", None, 9999220736.0), + ("layers.0.feed_forward.w1", None, 9999220736.0), + ("layers.0.adaLN_modulation.0", None, 9999220736.0), + ("layers.0.attention.to_v", rank, 0.5), + ]: + linear = model.get_submodule(module) + factors, delta = make_lokr_factors(linear.out_features, linear.in_features, rank=factor_rank) + state_dict.update({f"diffusion_model.{module}.{k}": v for k, v in factors.items()}) + state_dict[f"diffusion_model.{module}.alpha"] = torch.tensor(alpha) + expected_deltas[module] = delta if factor_rank is None else (alpha / rank) * delta + + converted = ZImageLoraLoaderMixin.lora_state_dict(state_dict) + assert all(k.startswith("transformer.") and ".lokr_" in k for k in converted) + model.load_lora_adapter(converted, prefix="transformer", adapter_name="default") + + check_lokr_deltas(model, expected_deltas) + + # TODO: Add pretrained_model_name_or_path once a tiny Z-Image model is available on the Hub # class TestZImageTransformerBitsAndBytes(ZImageTransformerTesterConfig, BitsAndBytesTesterMixin): # """BitsAndBytes quantization tests for Z-Image Transformer.""" diff --git a/tests/pipelines/kandinsky6/__init__.py b/tests/pipelines/kandinsky6/__init__.py new file mode 100644 index 000000000000..e69de29bb2d1 diff --git a/tests/pipelines/kandinsky6/test_pipeline_kandinsky6_sr.py b/tests/pipelines/kandinsky6/test_pipeline_kandinsky6_sr.py new file mode 100644 index 000000000000..14e1b7376524 --- /dev/null +++ b/tests/pipelines/kandinsky6/test_pipeline_kandinsky6_sr.py @@ -0,0 +1,131 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import torch + +from diffusers import ( + FlowMatchEulerDiscreteScheduler, + Kandinsky6SRLatentUpscalerBank, + Kandinsky6SRPipeline, + Kandinsky6SRTransformer3DModel, + Kandinsky6SRVAE, +) + +from ...testing_utils import torch_device +from ..testing_utils import BasePipelineTesterConfig, MemoryTesterMixin, PipelineTesterMixin + + +class Kandinsky6SRPipelineTesterConfig(BasePipelineTesterConfig): + pipeline_class = Kandinsky6SRPipeline + required_input_params_in_call_signature = frozenset(["video", "resolution_scale", "num_inference_steps"]) + batch_input_params = frozenset(["video"]) + optional_input_params = frozenset(["num_inference_steps", "generator", "output_type", "return_dict"]) + # (num_frames, channels, height, width) for output_type="pt": the 5x16x32 input video upscaled 2x. + output_shape = (5, 3, 32, 64) + + def get_dummy_components(self): + torch.manual_seed(0) + transformer = Kandinsky6SRTransformer3DModel( + in_visual_dim=4, + out_visual_dim=4, + time_dim=16, + patch_size=(1, 1, 1), + model_dim=24, + ff_dim=32, + num_visual_blocks=2, + axes_dims=(4, 4, 4), + # Trained tile resolutions. NABLA needs each tile's latent token grid divisible by 8, so every size is a + # multiple of 32 (VAE spatial factor 4 times 8). The 2x route tiles the 16x32 test video at (16, 32). + tile_sizes=((32, 32), (32, 64), (64, 32)), + ) + + torch.manual_seed(0) + # Three levels give a 4x spatial factor; both non-final levels compress time for a 4x temporal factor. + vae = Kandinsky6SRVAE( + latent_channels=4, + encoder_block_out_channels=(4, 8, 8), + decoder_block_out_channels=(4, 8, 8), + layers_per_block=1, + temporal_compression_ratio=4, + temporal_compression_start_level=0, + ) + + torch.manual_seed(0) + latent_upscaler = Kandinsky6SRLatentUpscalerBank( + in_channels=4, + stage_channels=(8, 8, 4), + num_pre_blocks=1, + num_mid_blocks=1, + num_post_blocks=1, + num_x2_adapter_blocks=1, + scales=(2, 4), + ) + + scheduler = FlowMatchEulerDiscreteScheduler(shift=3.5) + + return { + "transformer": transformer, + "vae": vae, + "scheduler": scheduler, + "latent_upscaler": latent_upscaler, + } + + def get_dummy_inputs(self): + # A `(num_frames, channels, height, width)` video in [0, 1] with 1 + 4k frames. + video = torch.rand((5, 3, 16, 32), generator=self.get_generator(0)) + return { + "video": video, + "resolution_scale": 2, + "num_inference_steps": 2, + "generator": self.get_generator(0), + "min_overlap": 0.2, + "tiles_batch_size": 4, + "output_type": "pt", + } + + +class TestKandinsky6SRPipeline(Kandinsky6SRPipelineTesterConfig, PipelineTesterMixin): + def test_kandinsky6_sr_scales(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + # The 2.25x route rounds the 1.125x pre-upscaled size to the VAE spatial factor (4 here): 16 -> 16, 32 -> 36. + for resolution_scale, expected in ((2, (32, 64)), (2.25, (32, 72)), (4, (64, 128))): + inputs = self.get_dummy_inputs() + inputs["resolution_scale"] = resolution_scale + output = pipe(**inputs) + assert output.frames.shape == (1, 5, 3, *expected), f"unexpected shape for scale {resolution_scale}" + assert not torch.isnan(output.frames).any() + + def test_kandinsky6_sr_without_latent_upscaler(self): + # Without the latent upscaler the pixel tiles are bilinearly upscaled and encoded instead. + components = self.get_dummy_components() + components["latent_upscaler"] = None + pipe = self.pipeline_class(**components).to(torch_device) + output = pipe(**self.get_dummy_inputs()) + assert output.frames.shape == (1, *self.output_shape) + assert not torch.isnan(output.frames).any() + + def test_kandinsky6_sr_rejects_wrong_frame_count(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + inputs = self.get_dummy_inputs() + inputs["video"] = inputs["video"][:4] + try: + pipe(**inputs) + except ValueError as error: + assert "frames" in str(error) + else: + raise AssertionError("expected a ValueError for a video without 1 + 4k frames") + + +class TestKandinsky6SRPipelineMemory(Kandinsky6SRPipelineTesterConfig, MemoryTesterMixin): + pass diff --git a/tests/pipelines/kandinsky6/test_pipeline_kandinsky6_ti2va.py b/tests/pipelines/kandinsky6/test_pipeline_kandinsky6_ti2va.py new file mode 100644 index 000000000000..235d32f6b5c4 --- /dev/null +++ b/tests/pipelines/kandinsky6/test_pipeline_kandinsky6_ti2va.py @@ -0,0 +1,303 @@ +# Copyright 2025 The Kandinsky Team and The HuggingFace Team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import numpy as np +import PIL.Image +import pytest +import torch +from transformers import ( + AutoProcessor, + CLIPTextConfig, + CLIPTextModel, + CLIPTokenizer, + Qwen2_5_VLConfig, + Qwen2_5_VLForConditionalGeneration, +) + +from diffusers import ( + AutoencoderKLHunyuanVideo, + FlowMatchEulerDiscreteScheduler, + Kandinsky6TI2VAPipeline, + Kandinsky6Transformer3DModel, + MMAudioVAE, + MMAudioVocoder, +) + +from ...testing_utils import assert_tensors_close, torch_device +from ..testing_utils import BasePipelineTesterConfig, MemoryTesterMixin, PipelineTesterMixin + + +class Kandinsky6TI2VAPipelineTesterConfig(BasePipelineTesterConfig): + pipeline_class = Kandinsky6TI2VAPipeline + required_input_params_in_call_signature = frozenset( + ["prompt", "height", "width", "num_frames", "num_inference_steps", "guidance_scale"] + ) + batch_input_params = frozenset(["prompt", "negative_prompt"]) + optional_input_params = frozenset( + ["num_inference_steps", "num_videos_per_prompt", "generator", "latents", "output_type", "return_dict"] + ) + # (num_frames, channels, height, width) for output_type="pt", matching `get_dummy_inputs()`'s + # (num_frames=5, height=16, width=16) at the tiny VAE's 8x spatial / 4x temporal compression. + output_shape = (5, 3, 16, 16) + + # `audio_vae` (`MMAudioVAE`) reads its own `data_std`/`data_mean` buffers directly in + # `MMAudioAutoencoder.decode` rather than through one of its leaf submodules, so leaf-level onload hooks on + # its children never onload them and decoding runs on a mix of onload/offload devices. Every other component + # offloads fine at leaf level, so exclude just this one rather than skipping the test. + group_offloading_leaf_level_exclude_modules = ["audio_vae"] + + def get_dummy_components(self): + torch.manual_seed(0) + # 3 down/up levels so the tiny VAE's realized compression matches the declared + # spatial_compression_ratio=8 / temporal_compression_ratio=4 the pipeline reads. + vae = AutoencoderKLHunyuanVideo( + act_fn="silu", + block_out_channels=[8, 8, 8], + down_block_types=[ + "HunyuanVideoDownBlock3D", + "HunyuanVideoDownBlock3D", + "HunyuanVideoDownBlock3D", + ], + in_channels=3, + latent_channels=4, + layers_per_block=1, + mid_block_add_attention=False, + norm_num_groups=2, + out_channels=3, + scaling_factor=0.476986, + spatial_compression_ratio=8, + temporal_compression_ratio=4, + up_block_types=[ + "HunyuanVideoUpBlock3D", + "HunyuanVideoUpBlock3D", + "HunyuanVideoUpBlock3D", + ], + ) + + torch.manual_seed(0) + # A tiny sample rate keeps the audio latent sequence short (2 latent frames for 5 video frames). + audio_vae = MMAudioVAE( + mel_bins=8, + latent_channels=4, + hidden_channels=8, + channel_multipliers=(1, 2), + layers_per_block=1, + sample_rate=64, + n_fft=16, + hop_length=4, + ) + + torch.manual_seed(0) + # `upsample_rates` must multiply to `audio_vae.config.hop_length` (4 = 2 * 2). + vocoder = MMAudioVocoder( + num_mels=8, + upsample_initial_channel=8, + upsample_rates=(2, 2), + upsample_kernel_sizes=(4, 4), + resblock_kernel_sizes=(3,), + resblock_dilation_sizes=((1, 3),), + ) + + scheduler = FlowMatchEulerDiscreteScheduler(shift=7.0) + + # mrope_section must sum to (hidden_size / num_attention_heads) / 2, matching the + # hf-internal-testing/tiny-random-Qwen2VLForConditionalGeneration processor used below. + qwen_hidden_size = 32 + torch.manual_seed(0) + qwen_config = Qwen2_5_VLConfig( + text_config={ + "hidden_size": qwen_hidden_size, + "intermediate_size": qwen_hidden_size, + "num_hidden_layers": 2, + "num_attention_heads": 2, + "num_key_value_heads": 2, + "rope_scaling": { + "mrope_section": [2, 2, 4], + "rope_type": "default", + "type": "default", + }, + "rope_theta": 1000000.0, + }, + vision_config={ + "depth": 2, + "hidden_size": qwen_hidden_size, + "intermediate_size": qwen_hidden_size, + "num_heads": 2, + "out_hidden_size": qwen_hidden_size, + }, + hidden_size=qwen_hidden_size, + vocab_size=152064, + vision_end_token_id=151653, + vision_start_token_id=151652, + vision_token_id=151654, + ) + text_encoder = Qwen2_5_VLForConditionalGeneration(qwen_config) + tokenizer = AutoProcessor.from_pretrained("hf-internal-testing/tiny-random-Qwen2VLForConditionalGeneration") + + clip_hidden_size = 16 + torch.manual_seed(0) + clip_config = CLIPTextConfig( + bos_token_id=0, + eos_token_id=2, + hidden_size=clip_hidden_size, + intermediate_size=16, + layer_norm_eps=1e-05, + num_attention_heads=2, + num_hidden_layers=2, + pad_token_id=1, + vocab_size=1000, + projection_dim=clip_hidden_size, + ) + text_encoder_2 = CLIPTextModel(clip_config) + tokenizer_2 = CLIPTokenizer.from_pretrained("hf-internal-testing/tiny-random-clip") + + torch.manual_seed(0) + transformer = Kandinsky6Transformer3DModel( + in_visual_dim=4, + out_visual_dim=4, + in_text_dim=qwen_hidden_size, + in_text_dim2=clip_hidden_size, + time_dim=16, + patch_size=(1, 2, 2), + model_dim=12, + ff_dim=24, + num_text_blocks=1, + num_visual_blocks=2, + axes_dims=(2, 1, 1), + visual_cond=True, + in_audio_dim=4, + out_audio_dim=4, + visual_token_type_num_embeddings=2, + ) + + return { + "transformer": transformer, + "vae": vae, + "text_encoder": text_encoder, + "tokenizer": tokenizer, + "text_encoder_2": text_encoder_2, + "tokenizer_2": tokenizer_2, + "scheduler": scheduler, + "audio_vae": audio_vae, + "vocoder": vocoder, + } + + def get_dummy_inputs(self): + return { + "prompt": "A cat and a dog baking a cake together in a kitchen.", + "negative_prompt": "static, blurry", + "generator": self.get_generator(0), + "num_inference_steps": 2, + "guidance_scale": 5.0, + "height": 16, + "width": 16, + "num_frames": 5, + "max_sequence_length": 16, + "output_type": "pt", + } + + +class TestKandinsky6TI2VAPipeline(Kandinsky6TI2VAPipelineTesterConfig, PipelineTesterMixin): + def test_save_load_optional_components(self, tmp_path, expected_max_difference=1e-4): + # Dropping the optional `audio_vae`/`vocoder` components also drops the pipeline's ability to sample + # audio, so `sample_audio` must be turned off explicitly instead of relying on its default. + if not getattr(self.pipeline_class, "_optional_components", None): + pytest.skip(f"Skipping test because {self.pipeline_class} has no `_optional_components`.") + + pipe = self.get_pipeline().to(torch_device) + + for optional_component in pipe._optional_components: + setattr(pipe, optional_component, None) + + inputs = self.get_dummy_inputs() + inputs["sample_audio"] = False + torch.manual_seed(0) + output = pipe(**inputs)[0] + + pipe.save_pretrained(tmp_path, safe_serialization=False) + pipe_loaded = self.pipeline_class.from_pretrained(tmp_path) + pipe_loaded.to(torch_device) + pipe_loaded.set_progress_bar_config(disable=None) + + for optional_component in pipe._optional_components: + assert getattr(pipe_loaded, optional_component) is None, ( + f"`{optional_component}` did not stay set to None after loading." + ) + + inputs = self.get_dummy_inputs() + inputs["sample_audio"] = False + torch.manual_seed(0) + output_loaded = pipe_loaded(**inputs)[0] + + assert_tensors_close( + output_loaded, + output, + atol=expected_max_difference, + msg="Output changed after dropping optional components.", + ) + + def test_kandinsky6_ti2va_audio_output(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + output = pipe(**self.get_dummy_inputs()) + + # 5 frames at 24 fps and 64 Hz -> 2 audio latent frames -> 4 mel frames -> 16 samples + assert output.frames.shape == (1, *self.output_shape) + assert output.audio.shape == (1, 16) + assert not torch.isnan(output.audio).any() + + def test_kandinsky6_ti2va_video_only(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + inputs = self.get_dummy_inputs() + inputs["sample_audio"] = False + output = pipe(**inputs) + + assert output.frames.shape == (1, *self.output_shape) + assert output.audio is None + + def test_kandinsky6_ti2va_i2va(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + inputs = self.get_dummy_inputs() + inputs["image"] = PIL.Image.fromarray(np.zeros((16, 16, 3), dtype=np.uint8)) + + output = pipe(**inputs) + + assert output.frames.shape == (1, *self.output_shape) + assert not torch.isnan(output.frames.float()).any() + + def test_kandinsky6_ti2va_different_images(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + inputs = self.get_dummy_inputs() + inputs["image"] = PIL.Image.fromarray(np.zeros((16, 16, 3), dtype=np.uint8)) + output_black_image = pipe(**inputs).frames + + inputs = self.get_dummy_inputs() + inputs["image"] = PIL.Image.fromarray(np.full((16, 16, 3), 255, dtype=np.uint8)) + output_white_image = pipe(**inputs).frames + + max_diff = (output_black_image.float() - output_white_image.float()).abs().max() + assert max_diff > 1e-6, "Outputs should be different for different reference images." + + def test_kandinsky6_ti2va_num_videos_per_prompt(self): + pipe = self.pipeline_class(**self.get_dummy_components()).to(torch_device) + inputs = self.get_dummy_inputs() + inputs["num_videos_per_prompt"] = 2 + + output = pipe(**inputs) + + assert output.frames.shape == (2, *self.output_shape) + assert output.audio.shape[0] == 2 + + +class TestKandinsky6TI2VAPipelineMemory(Kandinsky6TI2VAPipelineTesterConfig, MemoryTesterMixin): + pass diff --git a/tests/schedulers/test_scheduler_piflow.py b/tests/schedulers/test_scheduler_piflow.py new file mode 100644 index 000000000000..53b7d5d2c043 --- /dev/null +++ b/tests/schedulers/test_scheduler_piflow.py @@ -0,0 +1,198 @@ +# Copyright 2026 The Kandinsky Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import unittest + +import torch + +from diffusers import PiflowScheduler +from diffusers.schedulers.scheduling_piflow import PiflowSchedulerOutput + + +class PiflowSchedulerTest(unittest.TestCase): + """ + PiflowScheduler's model output is "widened" (``n_grid`` predictions packed into the channel + dimension) rather than matching the sample shape, so it cannot use ``SchedulerCommonTest`` (see + ``FlowMapEulerDiscreteSchedulerTest`` for the same situation with a different non-standard + contract). These tests exercise the contract `Kandinsky6TI2VAPipeline` actually relies on. + """ + + scheduler_class = PiflowScheduler + + def get_default_config(self, **kwargs): + config = { + "num_train_timesteps": 1000, + "shift": 5.0, + "n_grid": 4, + "eps": 1e-6, + "final_step_size_scale": 0.5, + "num_policy_substeps": 32, + } + config.update(**kwargs) + return config + + def make_widened_output(self, velocity: torch.Tensor, n_grid: int) -> torch.Tensor: + """Pack one velocity prediction into `n_grid` identical grid slots (channel-minor layout).""" + return velocity.repeat(1, n_grid) + + # ---- config validation ---- + + def test_instantiation_with_defaults(self): + scheduler = self.scheduler_class(**self.get_default_config()) + self.assertEqual(scheduler.config.num_train_timesteps, 1000) + self.assertEqual(scheduler.config.n_grid, 4) + + def test_invalid_n_grid_raises(self): + with self.assertRaises(ValueError): + self.scheduler_class(**self.get_default_config(n_grid=1)) + + def test_invalid_eps_raises(self): + with self.assertRaises(ValueError): + self.scheduler_class(**self.get_default_config(eps=0.0)) + + def test_invalid_final_step_size_scale_raises(self): + with self.assertRaises(ValueError): + self.scheduler_class(**self.get_default_config(final_step_size_scale=0.0)) + with self.assertRaises(ValueError): + self.scheduler_class(**self.get_default_config(final_step_size_scale=1.5)) + + def test_invalid_num_policy_substeps_raises(self): + with self.assertRaises(ValueError): + self.scheduler_class(**self.get_default_config(num_policy_substeps=0)) + + # ---- set_timesteps ---- + + def test_set_timesteps_shapes_and_monotonic(self): + scheduler = self.scheduler_class(**self.get_default_config()) + for nfe in [1, 2, 4, 8, 16]: + scheduler.set_timesteps(nfe) + self.assertEqual(scheduler.timesteps.shape, (nfe,)) + self.assertEqual(scheduler.sigmas.shape, (nfe + 1,)) + self.assertEqual(scheduler.sigmas[-1].item(), 0.0) + # strictly decreasing: this schedule should never hit the duplicate-timestep branch + # in `_step_index_for` that other flow schedulers need for interpolated sigmas. + diffs = scheduler.timesteps[1:] - scheduler.timesteps[:-1] + self.assertTrue(torch.all(diffs < 0)) + + def test_set_timesteps_rejects_unsupported_args(self): + scheduler = self.scheduler_class(**self.get_default_config()) + with self.assertRaises(ValueError): + scheduler.set_timesteps(4, sigmas=[1.0, 0.5, 0.0]) + with self.assertRaises(ValueError): + scheduler.set_timesteps(4, mu=1.0) + with self.assertRaises(ValueError): + scheduler.set_timesteps(4, timesteps=[900, 500, 100]) + with self.assertRaises(ValueError): + scheduler.set_timesteps(0) + + # ---- step() input validation ---- + + def test_step_rejects_integer_timestep(self): + scheduler = self.scheduler_class(**self.get_default_config()) + scheduler.set_timesteps(4) + sample = torch.randn(1, 3) + model_output = self.make_widened_output(torch.randn(1, 3), scheduler.n_grid) + with self.assertRaises(ValueError): + scheduler.step(model_output, 0, sample) + + def test_step_after_exhausted_schedule_raises(self): + scheduler = self.scheduler_class(**self.get_default_config()) + scheduler.set_timesteps(2) + sample = torch.randn(1, 3) + for t in scheduler.timesteps: + model_output = self.make_widened_output(torch.randn(1, 3), scheduler.n_grid) + sample = scheduler.step(model_output, t, sample).prev_sample + with self.assertRaises(RuntimeError): + scheduler.step( + self.make_widened_output(torch.randn(1, 3), scheduler.n_grid), scheduler.timesteps[-1], sample + ) + + def test_step_return_dict_false_returns_tuple(self): + scheduler = self.scheduler_class(**self.get_default_config()) + scheduler.set_timesteps(2) + sample = torch.randn(1, 3) + model_output = self.make_widened_output(torch.randn(1, 3), scheduler.n_grid) + output = scheduler.step(model_output, scheduler.timesteps[0], sample, return_dict=False) + self.assertIsInstance(output, tuple) + output_dict = scheduler.step(model_output, scheduler.timesteps[0], sample, return_dict=True) + self.assertIsInstance(output_dict, PiflowSchedulerOutput) + + def test_to_grid_rejects_mismatched_shapes(self): + scheduler = self.scheduler_class(**self.get_default_config()) + scheduler.set_timesteps(2) + sample = torch.randn(1, 3) + with self.assertRaises(ValueError): + # channel count not divisible by n_grid + scheduler.step(torch.randn(1, 5), scheduler.timesteps[0], sample) + with self.assertRaises(ValueError): + # divisible by n_grid, but the per-grid width doesn't match the sample's channel count + scheduler.step(torch.randn(1, 4 * 2), scheduler.timesteps[0], sample) + + # ---- correctness ---- + + def test_step_is_deterministic(self): + # Like every diffusers scheduler with an auto-incrementing `_step_index` (e.g. + # FlowMatchEulerDiscreteScheduler), `step()` only resolves `timestep` into an index on the + # first call after `set_timesteps`; a second call reuses the advanced internal counter + # regardless of the `timestep` passed in. So determinism must be checked across two freshly + # reset schedulers, not two `step()` calls on the same instance. + torch.manual_seed(0) + sample = torch.randn(2, 5) + model_output = self.make_widened_output(torch.randn(2, 5), self.get_default_config()["n_grid"]) + + scheduler1 = self.scheduler_class(**self.get_default_config()) + scheduler1.set_timesteps(4) + out1 = scheduler1.step(model_output, scheduler1.timesteps[0], sample.clone()).prev_sample + + scheduler2 = self.scheduler_class(**self.get_default_config()) + scheduler2.set_timesteps(4) + out2 = scheduler2.step(model_output, scheduler2.timesteps[0], sample.clone()).prev_sample + + torch.testing.assert_close(out1, out2) + + def test_no_nan_across_configs(self): + for n_grid in (2, 4, 8): + for nfe in (1, 2, 8): + scheduler = self.scheduler_class(**self.get_default_config(n_grid=n_grid)) + scheduler.set_timesteps(nfe) + sample = torch.randn(2, 6) + for t in scheduler.timesteps: + model_output = self.make_widened_output(torch.randn(2, 6), n_grid) + sample = scheduler.step(model_output, t, sample).prev_sample + self.assertFalse(torch.isnan(sample).any(), f"NaN with n_grid={n_grid}, nfe={nfe}") + self.assertFalse(torch.isinf(sample).any(), f"Inf with n_grid={n_grid}, nfe={nfe}") + + def test_step_recovers_known_clean_target(self): + """A "perfect" model whose implied x0 prediction is always exactly `target` (i.e. every grid + slot predicts the velocity of the straight line from the current sample to `target`) should + drive the sample to `target` after the full schedule: that straight-line ODE has a velocity + that is exactly constant along the true path, so the scheduler's Euler-style substep + integration has zero discretization error and the only residual comes from stopping at + `eps` instead of sigma=0. This catches sign/broadcasting/indexing bugs that a shape-only or + no-NaN check would miss. + """ + torch.manual_seed(0) + scheduler = self.scheduler_class(**self.get_default_config(n_grid=4, num_policy_substeps=64)) + scheduler.set_timesteps(8) + batch, dim = 2, 3 + target = torch.randn(batch, dim) + sample = torch.randn(batch, dim) * 3.0 + 5.0 # arbitrary, far from target + + for i, t in enumerate(scheduler.timesteps): + sigma = scheduler.sigmas[i] + velocity = (sample - target) / sigma.clamp(min=scheduler.eps) + model_output = self.make_widened_output(velocity, scheduler.n_grid) + sample = scheduler.step(model_output, t, sample).prev_sample + + torch.testing.assert_close(sample, target, atol=1e-3, rtol=1e-3)