fix(loss): exclude -inf logprobs from the actor reduction, not the KL - #3551
tianyi-zhang-02 wants to merge 13 commits into
Conversation


mask_out_neg_inf_logprobs prints "Masking out these positions", computes a
narrowed mask, and then returns only the logprobs -- the narrowed mask never
leaves the function. All five call sites keep the un-narrowed mask, and
ClippedPGLossFn re-derives its own reduction mask from the untouched batch.

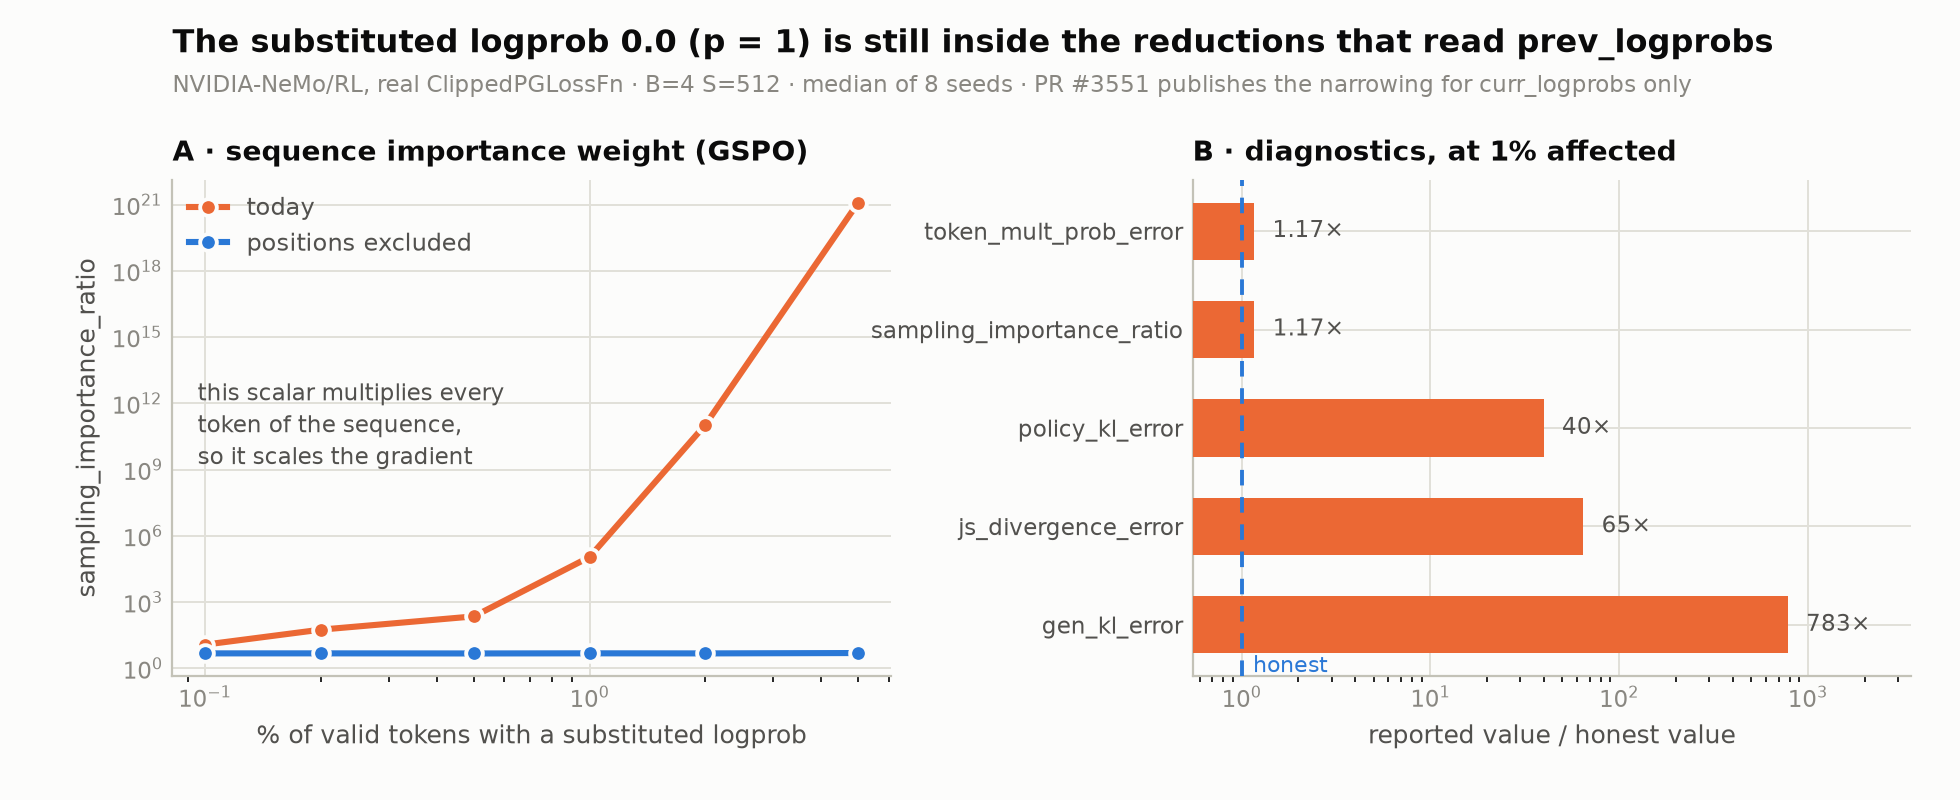
The substituted 0.0 is not a neutral filler. It means log p = 0, i.e. p = 1,
while generation_logprobs at the same position is finite by construction
(vLLM sampled the token from its own filtered distribution). Everything that
compares the two therefore reads a large fabricated difference:
token_mult_prob_error, gen_kl_error and js_divergence_error all evaluate
exp(|0 - log pi_gen|), which is ~224 for a typical -5.4. Under
sequence_level_importance_ratios the same difference is summed over the
sequence and exponentiated, so it inflates the importance weight multiplying
the whole sequence's clipped loss -- a gradient effect, not just a metric.

Return the keep mask and fold it into token_mask at the two curr-logprob call
sites, which is where the loss reads it back. The three prev-logprob sites
cannot pass it on today because LogprobOutputSpec carries logprobs only; they
discard it explicitly with a comment rather than silently.

Reachable in shipped recipes: grpo-llama3.2-1b-instruct-1n8g-fsdp2tp2-
temp0.8-topp0.9-topk50.yaml and its megatron twin set top_k=50, top_p=0.9,
and the defect fires whenever the existing warning prints.

Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>


Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
tianyi-zhang-02
changed the title
 svcnvidia-nemo-ci
added
the
waiting-on-maintainers

|
One consequence of this change that the description did not spell out, and that a reviewer should decide on rather than discover. Folding the narrowed mask into Happy to change it if you would rather the KL stayed on the full mask; flagging it because it is the kind of thing that is easy to miss in a diff this size. |
|
Followed up on the open question in my earlier comment rather than leaving it to review. Folding the keep mask into The reference-policy KL reduces with
Latest push publishes the mask as
The test asserts both halves. It goes red under either mutation: ignoring the keep mask, or folding it back into |
tianyi-zhang-02
changed the title
svcnvidia-nemo-ci
added
waiting-on-maintainers
|
One more thing the description does not say, and should.
It cannot be closed here because the narrowed mask has no way to travel with What that leaves: if the previous policy had a Two reasons I left it. Both sides are filtered under the same The three call sites carry a comment saying the same thing, so it is not silent in the code either :) |

 yuki-97
left a comment
yuki-97
left a comment
There was a problem hiding this comment.
@jinglinglingling to review
 svcnvidia-nemo-ci
removed
the
waiting-on-maintainers

 jinglinglingling
left a comment
jinglinglingling
left a comment
There was a problem hiding this comment.
LGTM. No concerns from my side.
svcnvidia-nemo-ci
added
the
waiting-on-customer
…nostics

Folding the -inf keep mask into ``token_mask`` narrowed every reduction in
ClippedPGLossFn, not just the actor term. Two of those should not narrow:

- The reference-policy KL reduces with ``token_mask`` but is computed from
  ``curr_logprobs_unfiltered``, which is finite at the filtered positions.
  Dropping them removes real KL terms, and removes them selectively: a token
  is filtered precisely where the training policy assigns it near-zero mass
  while the reference checkpoint may not, i.e. where the two disagree most.
- token_mult_prob_error / gen_kl_error / policy_kl_error / JS divergence read
  only prev and generation logprobs, so they are unaffected by the
  substitution and narrowing them hides mismatch the metrics exist to report.

Publish the mask as ``curr_logprobs_keep_mask`` instead and apply it only to
quantities derived from ``curr_logprobs``: the actor loss (both reduction
modes), the GSPO sequence-level ratio, the entropy approximation, the VAPO
NLL term, and the probs_ratio metrics -- where a substituted logprob of 0.0
otherwise fabricates a ratio of exp(-prev_logprob).

The new test pins both halves and fails under either mutation: ignoring the
keep mask, and folding it back into ``token_mask``.

Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
The note still described the old mechanism, where the curr side folded its
narrowing into token_mask. It now publishes curr_logprobs_keep_mask and
narrows only the actor reduction.

Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
8c038e0 to
a21ca6d
Compare
|
Merged current main in. Should be clean merge w/ no conflicts. |
svcnvidia-nemo-ci
added
waiting-on-maintainers
|
Ran this on Linux, since the body notes the two caller tests could not execute on the macOS host. All six new tests pass, and One correction for the merge description: the body says the keep mask is "folded into Three things I measured while checking it. 1. 2. 3. The deferred prev-side case is not diagnostics-only. The worker comments are right that it needs
At 1% of valid tokens substituted, |
 svcnvidia-nemo-ci
removed
the
waiting-on-maintainers
svcnvidia-nemo-ci
added
the
waiting-on-maintainers
The keep mask is applied at six reductions; one test pinned one of them.
Four of the rest are now covered, and two of those move the gradient rather
than a dashboard number:

  - the GSPO sequence ratio. masked_mean with no global normalization factor,
    so the filtered position corrupts numerator and divisor, and the result is
    exponentiated.
  - the SEQUENCE_LEVEL actor loss. Its inner masked_mean normalizes by the
    mask sum, so the position both injects a fabricated clip_loss and inflates
    its own divisor.
  - VAPO's positive-example NLL, which normalizes by its own mask sum: the
    filtered position adds -0.0 to the numerator and +1 to the denominator, so
    the term is deflated rather than merely noisy.
  - probs_ratio and probs_ratio_clamped. The existing test pins only
    probs_ratio_max, which comes from a separate reduction.

The two sequence-level tests widen ratio_clip deliberately: at the default
0.2 both ratios land above the ceiling and clamp to the same value, so the
loss is identical either way and the assertion would be vacuous -- while the
metrics still differ, which makes the degenerate case easy to miss.

Mutation-tested: reverting each of the four sites to the un-narrowed mask
turns one of these red.

Signed-off-by: Tianyi Zhang <zhangtianyi975@gmail.com>
Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
…owed

The comment claimed they "read only prev/generation logprobs, so narrowing
them would drop real terms". That is wrong, and it contradicts the comment
this same PR adds at the worker call sites, which says the opposite.

prev_logprobs carries its own 0.0 substitutions: mask_out_neg_inf_logprobs
runs on the logprob-inference pass too, at the three worker sites this PR
edits. So those diagnostics are not reading real terms at the filtered
positions either.

The actual reason they stay on the full mask is different and weaker: the keep
mask published this step identifies what THIS forward filtered, not what the
earlier one did, so narrowing with it would drop the wrong positions.
force_on_policy_ratio is the single case where the two sets coincide, because
prev is then an alias of curr -- which is what the follow-up handles.

Comment only. No behaviour change.

Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
59ee3c9 to
d5b618f
Compare
Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
Emit actor-mask diagnostic numerators with their retained-token count, then finalize the global ratio after microbatch and rank aggregation. This keeps KL on the full valid-token mask while making filtered ratio and entropy metrics invariant to uneven shards.

Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
|
Follow-up on final SHA
cc @jinglinglingling — this is the final behavior after the earlier reviewed head moved. |
svcnvidia-nemo-ci
added
waiting-on-maintainers
Reuse the parent retained-token aggregation protocol and extend it to forced-on-policy prev reductions.

Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
Signed-off-by: Tianyi Zhang <123608656+tianyi-zhang-02@users.noreply.github.com>
|
Closing to avoid competing with the active top-k/top-p masking direction in #4154 (and the related masked-value safety work in #4120). This PR intentionally made a different KL-mask choice, so the right next step is maintainer clarification rather than keeping two policy-loss semantics open in parallel. |
svcnvidia-nemo-ci
removed
the
waiting-on-maintainers
4 participants


What does this PR do?
Removes positions whose current-policy logprob was
-inffrom actor-side reductions without narrowing the reference-policy KL.mask_out_neg_inf_logprobsnow returns the keep mask. Regular and packed callers publish it ascurr_logprobs_keep_mask, andClippedPGLossFnderives a separate actor mask instead of changingtoken_mask.The diagnostic means remain exact across uneven microbatches and DP ranks: the loss emits additive numerator fragments plus the retained actor-token count, and GRPO, synchronous GRPO, PPO, and SingleController divide once after global aggregation.
Prev-policy keep-mask propagation would require widening
LogprobOutputSpecand remains out of scope.Validation
Current head:
3ebc1e860cb9f95e5eda38be18a69324cfcf5df7, includingmainatfd7112c374af23b3bcc392637fb737495f8a3f31.On 2026-09-21, all four changed unit-test files passed on Runpod Secure Cloud: 161 passed, 0 failed/skipped. Environment: 1× H100 80 GB,
nvcr.io/nvidia/nemo-rl:v0.7.0, driver 580.126.09, CUDA 13.0, PyTorch 2.11.0+cu130. The current-main test fixture requiredpytest==9.0.3and pinnednemo-lenscommitb85578f, installed only in the temporary Pod. No multi-GPU functional run was attempted in this single-GPU session.The earlier CPU-only validation on head
cbfd57d454fdb8e6f963b4d241bece9c2b6f2df7also passed five exact-value targeted tests (including a SingleController caller with four uneven microbatch/rank fragments) and 65 related CPU tests; 44 GPU-only tests were skipped then.